Acapela Group is a company that develops personalized digital voices using voice AI technology. It offers text-to-speech solutions for services, applications and devices, with support for over 30 languages and more than 200 pre-made voices, plus custom voice creation options. The company provides SDKs for multiple platforms, cloud streaming APIs, and specialized solutions including voice AI for accessibility, transport and customer interaction.
Directory
Search results
Published directory entries matching your search.
AceTagGen is a free prompt system for SUNO AI. It offers a structured 12-step Tag Builder, a library of verified tags, a prompt scorer, and a research blog with articles and guides. No signup is required.
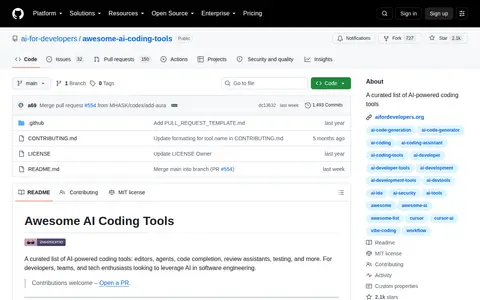
Open-source project that supports software development with code generation, analysis, debugging, or documentation.
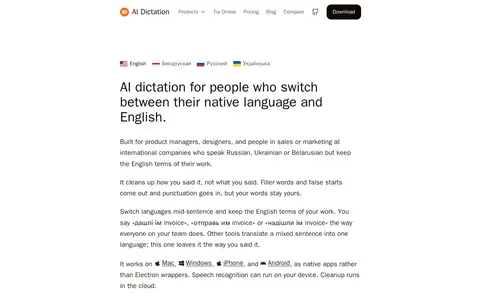
AI Dictation is a voice typing app for people who mix English into Russian, Ukrainian or Belarusian. It removes filler words and adds punctuation without translating work terms. It runs on Mac, Windows, iPhone and Android, and speech recognition can run on device while cleanup runs in the cloud.
Creates, edits or enhances video and animation with generative models.
AI Gallery is a tool for creating AI artwork on volunteer GPUs. According to the site, no GPU or installation is required, and the generated gallery stays on the user's device. Help documentation covers queues, models, credits, local storage, backups and generation controls.
AI Mastering is an automated online audio mastering service that uses AI. Free mastering is available, with drag-and-drop uploading, target loudness and mastering level customization, and output format, spectrum and loudness analysis. An API is documented, and a desktop offline version has been released.
A web tool for generating songs from text, lyrics or uploaded audio, with style, voice and tempo options and instrumental-only tracks. Songs can be downloaded or shared. The free tier offers 20 daily credits and royalty-free output.
An AI detector covering text, image, music and video content, with an API for detecting AI-generated images, text, videos and deepfakes. Pricing starts with free credits, and a Pro plan is listed at $5/month.
AI Voice Generator is a free online tool that produces natural-sounding text-to-speech voice overs. Users enter text, select from various AI voices, and generate a voiceover. The service emphasizes simplicity and accessibility for creating spoken content.
AI Wedding Toast is a free AI wedding speech generator that turns shared stories and memories into personalized speeches. It offers speech types including best man, maid of honor, father of the bride, groom, bride, wedding vows and others, generated in under two minutes without a credit card.
aiimagegenerator.org is a free online AI image generator. It creates AI art from text or image prompts using AI models such as Flux. An optional sketch can be provided as an initial image to guide generation.
AIVA is an AI music generation assistant that creates new songs in more than 250 styles within seconds. Users can build style models, upload audio or MIDI influence, and edit generated tracks. A free plan offers non-commercial use with credit to AIVA and three downloads per month.
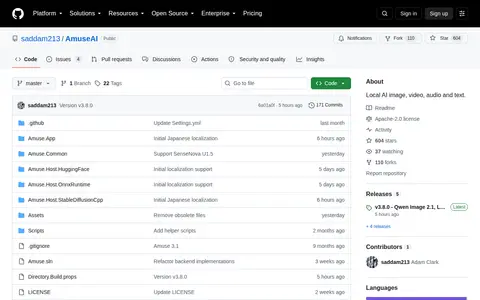
Amuse is an open-source local AI tool hosted on GitHub. It supports generation of images, videos, audio, and text, with dedicated pipelines for each media type, and welcomes community contributions to its development.
AnyVoiceLab is a free, no-login-required AI voice cloning tool. Users provide a short voice sample to create lifelike voice replicas, generate studio-quality speech, and download the resulting audio for free. Additional features include long-form text-to-speech, voice changing, sound effect generation, premium voice options, AI voice generation, payment plans, and support for emotion tags in speech.
Artificial Art is a free online AI image generation tool based on Stable Diffusion and powered by Stable Horde. It presents a compact interface for generating images, described as similar to DALL-E or Midjourney.
AssemblyAI provides voice AI infrastructure, including pre-recorded, realtime and synchronous speech-to-text APIs, a voice agent API, speech understanding features and guardrails. Features such as speaker diarization, summarization, sentiment analysis and PII redaction run on the same transcription request.
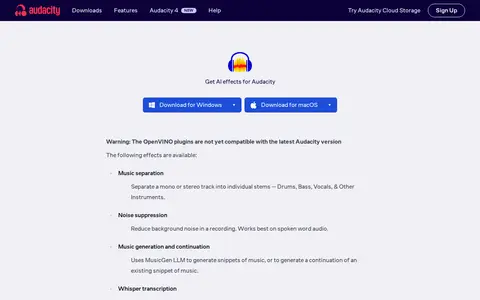
Audacity Effects is a set of OpenVINO AI plugins for Audacity, offering effects such as music separation into stems, noise suppression, music generation with MusicGen, Whisper transcription and audio super resolution. It is available for Windows and macOS. The plugins are noted as not yet compatible with the latest Audacity version.
AudioLDM is a text-to-audio system built on a latent space that learns continuous audio representations from CLAP latents. It generates text-conditional sound effects, human speech and music, and enables zero-shot text-guided audio style transfer, inpainting and super-resolution.
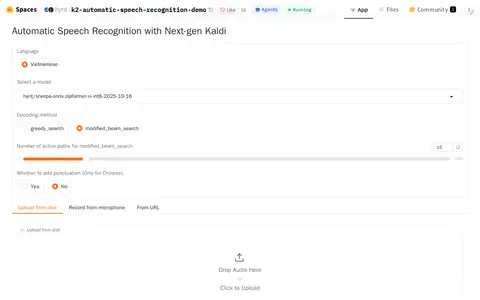
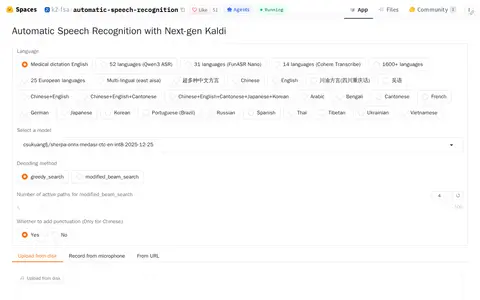
This Automatic Speech Recognition Hugging Face Space converts spoken audio to written text. Users can upload audio files, record from their microphone, or provide an audio URL, and select options including language, model, decoding method, and punctuation.
This Automatic Speech Recognition Hugging Face Space processes audio files, microphone recordings, or audio clips up to 40 seconds from a URL, and outputs the spoken content as written text.
Open-source project that supports software development with code generation, analysis, debugging, or documentation.