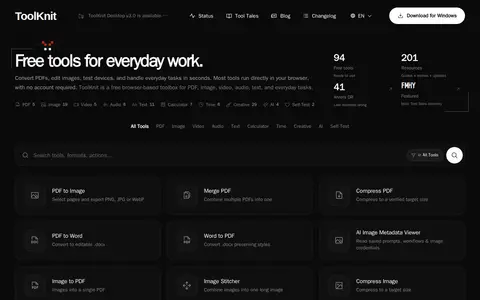
ToolKnit is a free browser-based toolbox of 94 tools for PDF, image, video, audio and text tasks, plus a World Holidays Hub. Local file tools process files on the user's device, while AI requests go to a configured provider and speech features use a server endpoint. No account is required.
Directory
Search results
Published directory entries matching your search.
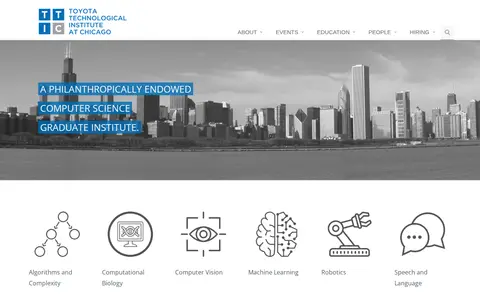
Toyota Technological Institute at Chicago is a philanthropically endowed computer science graduate institute. Its research areas include algorithms and complexity, computational biology, computer vision, machine learning, robotics, and speech and language. The institute offers a PhD program.
Treat is a natural language processing and computational linguistics toolkit for Ruby. It covers document retrieval, text chunking, segmentation, tokenization, parsing, part-of-speech tagging, keyword extraction and named entity recognition. The README states the gem is unmaintained.
Treblo, formerly Sonauto, is a free AI music generator that turns ideas into songs with lyrics, vocals and thousands of styles. It offers unlimited songs, editing, covers and remixes, and is available on iOS and Android.
Magazine offering news and articles about Ubuntu, including help with first steps, advanced tips, and introductions to applications. Its online news section covers topics such as speech control and installing Ubuntu 13.10.
The University of Aruba Open Knowledge Repository is a work-in-progress repository for the university's research output, showing featured items, recent submissions and communities. It hosts publications such as law articles, reports and academic speeches. Questions and discrepancy reports go to [email protected].
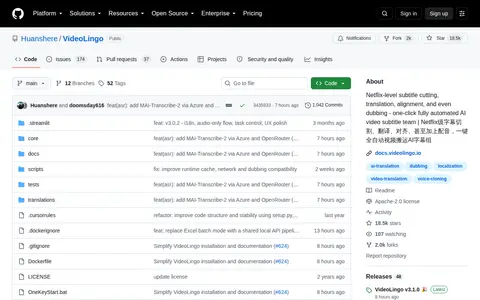
VideoLingo combines speech recognition, subtitle translation, segmentation and dubbing in a Streamlit interface. It produces subtitle files and optionally subtitled or dubbed videos, and supports input languages including English, Russian, French, German, Italian, Spanish, Japanese and Chinese.
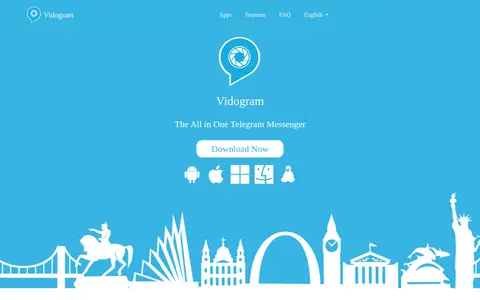
Vidogram is a messaging app based on Telegram, presented with video and voice calls and live streaming. It lists features including themes and stickers, speech to text, forwarding to WhatsApp, advanced forwarding and copying, special contact notifications, music playlists and a timeline of channel posts. A lighter version, Vidogram Lite, targets older phones, weaker hardware or slow internet.
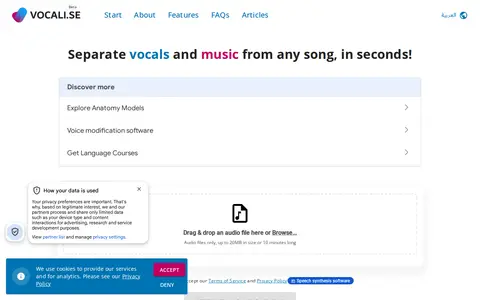
Vocali.se is a free web service that separates vocals and music from songs or audio files, allowing users to create karaoke versions. It runs a machine learning engine using pre-trained Demucs models and requires no software installation or account registration. Processing takes less than three minutes, after which the separated files download automatically.
VocalRemover is a free online application that separates a song into a karaoke version without vocals and an acapella version with isolated vocals. It uses artificial intelligence algorithms and processing usually takes about 10 seconds.
VCClient is software that performs real-time voice conversion using AI. It supports several AI models and offers both standalone use on a local PC and voice conversion over a network, and it provides a REST API. Editions support different models, and Windows and M1 Mac versions can be downloaded from a Hugging Face repository.
A site for browsing AI voice models for RVC. It lists 30,000+ voice models covering characters, singers and creators, allows previewing samples, and supports running compatible voices online with EasyAIVoice.
Voice-Swap is an AI voice platform for musicians, content creators, and artists. It offers a text-to-speech voiceover studio, a singing studio for voice swapping and stem separation, and custom voice model training. The site states that voice modelling, generation and rights management are combined into a single system.
VoiceNotebook is a speech-to-text application available for Windows, Mac, Linux, Android, and iOS. The desktop version operates via the Chrome browser, while mobile apps are available for Android and iOS. It supports direct voice typing to the clipboard, free transcription of audio files including mp3, mp4, and YouTube content, and offers features such as case adjustment, undo functionality, punctuation insertion, optional voice commands, and punctuation replacement.
G4F Chat is a conversational AI platform that supports private, customizable conversations using multiple AI providers and models. It includes features such as cloud sync, conversation export, markdown rendering, speech recognition, voice synthesis, custom system prompt configuration and MCP server support.
Transcription tool for converting audio or video recordings into searchable text.
Whisper is a robust speech recognition system developed by OpenAI, hosted on GitHub. It uses large-scale weak supervision for training, and the repository includes documentation on its approach, setup, available models and supported languages, plus command-line usage instructions.
Xinference is a model serving tool that provides a unified production-ready inference API. It allows users to run open-source, speech and multimodal models on cloud infrastructure, on-premises systems or personal laptops by modifying a single line of code.
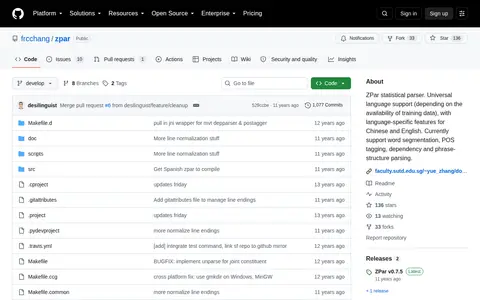
ZPar is an open-source statistical parser hosted on GitHub. It offers universal language support contingent on the availability of training data, with dedicated language-specific features for Chinese and English. The tool supports word segmentation, part-of-speech tagging, dependency parsing, and phrase-structure parsing.
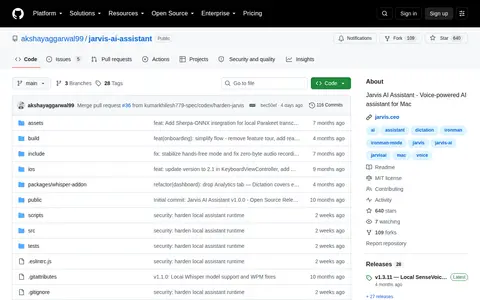
Jarvis AI Assistant is a voice dictation application for Mac that transcribes speech into text. It removes filler words, fixes grammar and supports local transcription with Whisper or Parakeet and local LLMs via Ollama, or cloud services. It is released under the MIT license and is described as open-source and local-capable.