MMAudio is a research project on multimodal joint training for video-to-audio synthesis. It generates synchronized audio given video and/or text inputs. The work is presented at CVPR 2025 by authors from the University of Illinois Urbana-Champaign and Sony.
Directory
Search results
Published directory entries matching your search.
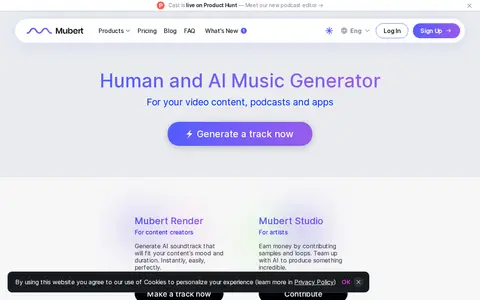
Mubert is an AI music generator offering royalty-free music from text prompts. It provides Render for content creators, Studio for contributing samples and loops, API for developers, and Play for listeners. The API supports track generation and music streaming integration.
Museum of Failure is a museum that showcases collections of past failures across fields including technology, medicine, finance and culture to illustrate how learning from mistakes drives innovation. Its most recent location is the Musee des Arts et Métiers in Paris, and it offers pop-up museum hire for organizational events paired with keynote speeches.
MusicGen is a single-stage auto-regressive Transformer model for music generation trained over a 32kHz EnCodec tokenizer with four codebooks, part of the AudioCraft library. It supports text-to-music and text-plus-melody-to-music models ranging from 300M to 3.3B parameters. Running it locally requires a GPU, with at least 16 GB of memory recommended for medium-sized models.
MusicGPT is an AI music generator and song maker. It creates original songs, beats, instrumentals and sound effects, and offers editing tools to split stems, change voices and enhance audio. The site lists Plus, Pro and Ultra plans, with a free start and upgrades for more minutes and commercial use.
Mythology.net is a reference site on mythology. It explains that the term comes from the Greek “mythos,” meaning story of people, and “logos,” meaning speech, and describes the field as the study of stories of creation, good versus evil, life and death, god and the afterlife. An alphabetically indexed character list covers figures such as gods, titans, angels, demons and mythical creatures.
Compromise is a JavaScript natural-language processing library that turns text into data, offering tokenization of words, sentences and punctuation along with part-of-speech tagging, matching, and transformations such as verb conjugation and number handling. It runs on the client side, is about 250kb minified, and includes plugins, with multilingual support listed for French, German, Italian and Spanish.
NSynth Super is an open source experimental instrument that lets musicians play sounds generated by the NSynth algorithm. The NSynth algorithm uses a deep neural network to learn sound characteristics and synthesize new sounds from four source sounds. The interface can be played via any MIDI source, such as a DAW, sequencer or keyboard.
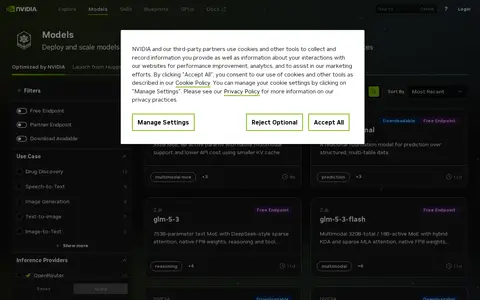
NVIDIA NIM is a catalog of models offered as inference microservices for deployment on the user's GPU infrastructure. The listings include downloadable models and free or partner endpoints, organized by use cases such as image generation, speech-to-text and drug discovery.
OCR tool for extracting readable text from images, screenshots, and scanned files.
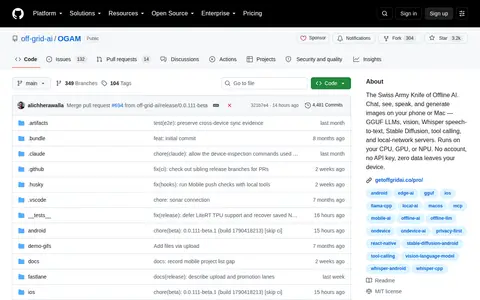
An offline AI application for phones and Macs that supports chat, image generation, vision, Whisper speech-to-text, tool calling and local-network servers. It runs on CPU, GPU or NPU, requires no account or API key, and keeps data on the device. A paid Pro tier adds voice mode, custom personas and draft-and-approve actions.
OLI (Open Learning Initiative) offers free and low-cost self-paced online courses designed exclusively for independent learners. The courses are not intended for classroom use or formal assignments, and cover subject areas including language and speech, computer science, life sciences, and social sciences. Independent learner courses do not provide instructor support, tests, certificates, or academic credit.
Apache OpenNLP is a machine learning based toolkit for the processing of natural language text. It supports tasks such as sentence segmentation, tokenization, lemmatization, part-of-speech tagging, named entity extraction, chunking, parsing, language detection and coreference resolution. The project is developed by volunteers and welcomes contributions, from small documentation fixes to new components.
openScope is a free and open source air traffic control simulator. The interface references arrivals, overflights, departures, fixes and runways, SID and STAR displays, airspace depiction, restricted areas, terrain, video maps, settings, speech, traffic, an airport guide, commands, a tutorial, a changelog and chat.
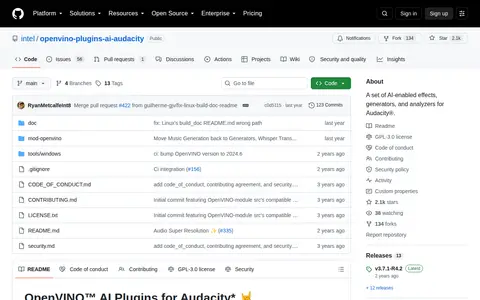
OpenVINO AI Plugins for Audacity is a set of AI-enabled effects, generators and analyzers for Audacity. The features run locally on the PC without an internet connection, using OpenVINO to run AI models on the system's CPU, GPU or NPU. Included tools cover music separation, noise suppression, MusicGen-based music generation and continuation, Whisper transcription and audio super resolution.
Paper2GUI is an AI desktop application toolbox that is free and ready to use out of the box. It supports more than 10 AI models covering speech synthesis, video frame filling, video overscoring, target detection, image stylization and OCR recognition, on Windows, Mac OS and Linux.
pkuseg is a Python toolkit for multi-domain Chinese word segmentation, based on a 2019 paper. It provides pretrained models for news, web, medicine, tourism, and mixed domains, and supports user-trained models and part-of-speech tagging. It is distributed under the MIT license.
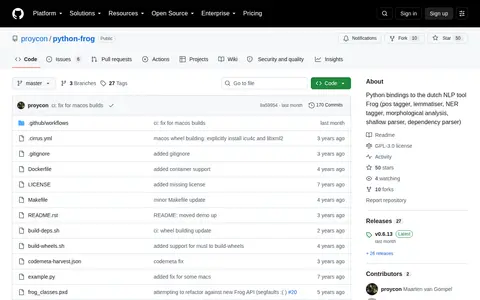
python-frog is an open-source Python library hosted on GitHub providing bindings to the Dutch NLP tool Frog, which supports part-of-speech tagging, lemmatisation, named entity recognition, morphological analysis, shallow parsing and dependency parsing.
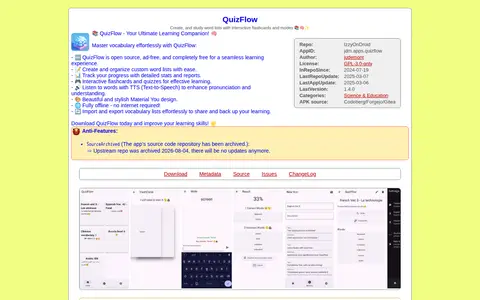
QuizFlow is an open-source, ad-free Android app for creating and studying custom word lists with interactive flashcards and quizzes. It includes progress stats, text-to-speech pronunciation, import and export of lists, and works fully offline. The upstream source repository was archived, so no further updates are planned.
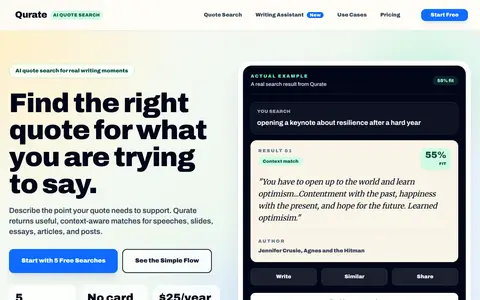
Qurate is a tool for finding quotes tailored to specific messages. Users can search for quotes by idea, tone, or situation for use in speeches, articles, presentations, and social media posts.
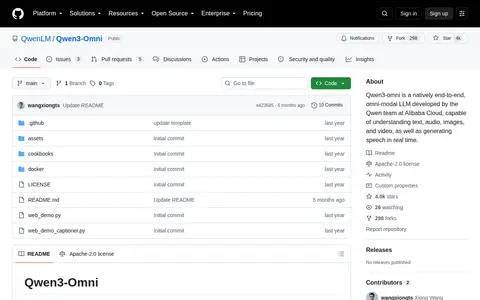
Qwen3-Omni is a natively end-to-end omni-modal large language model developed by the Qwen team at Alibaba Cloud. It can process text, audio, images, and video inputs, and generate speech in real time. The project's resources are hosted on a public GitHub repository.
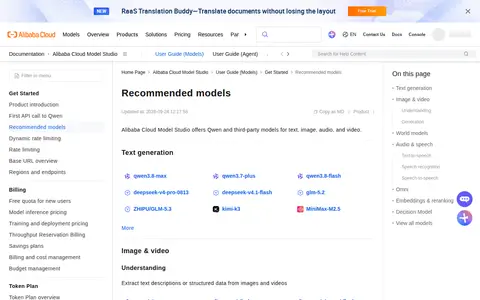
The listing qwen3.6-max-preview points to Alibaba Cloud Model Studio's supported models overview page. The page states that Alibaba Cloud Model Studio offers Qwen and third-party models for text, image, audio, and video use cases, with model categories including text generation, image and video generation, audio and speech processing, and world models, along with specific example models for each category.
Read Aloud is a text-to-speech voice reader available as a Chrome extension that reads aloud the current web-page article with one click and supports 40+ languages. The site also lists browser extensions for Firefox and Edge and a TTS widget service.
Reader Mode is a distraction-free reader that turns webpages into a simpler reading view with adjustable fonts, text size, spacing, colours and contrast. It includes reading rulers, text-to-speech, a Pomodoro timer, Bionic Reading and a highlighter. Version 2.0 is available as a Chrome extension; version 3.0 is in development.