MiniMax is a general AI technology company that develops multimodal foundation models and AI-native products. Its models are described as handling text, audio, image, video, and music, and it offers an open platform for enterprises and developers.
Directory
Search results
Published directory entries matching your search.
MusicLM is a model that generates high-fidelity music from text descriptions. It frames conditional music generation as hierarchical sequence-to-sequence modeling and produces audio at 24 kHz consistent over several minutes. It can also be conditioned on text and a melody, transforming whistled or hummed melodies according to a text caption. The project released MusicCaps, a dataset of 5.5k music-text pairs with descriptions by human experts.
NSynth Super is an open source experimental instrument that lets musicians play sounds generated by the NSynth algorithm. The NSynth algorithm uses a deep neural network to learn sound characteristics and synthesize new sounds from four source sounds. The interface can be played via any MIDI source, such as a DAW, sequencer or keyboard.
Nuance presents itself as now part of Microsoft, offering productivity solutions including speech recognition and AI-powered solutions for physicians and radiologists in healthcare. The page highlights transforming workflows and improving patient experiences.
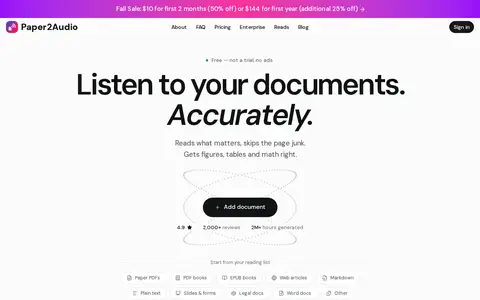
Paper2Audio is a free text-to-speech service designed for reading digital documents aloud. It supports PDFs, EPUBs, web articles, and other common document formats, uses natural AI voices for accurate reading, and includes no ads or paywalled voice features. The tool correctly processes figures, tables, and mathematical content, and skips extraneous page elements like inline references and endnotes to focus on relevant content.
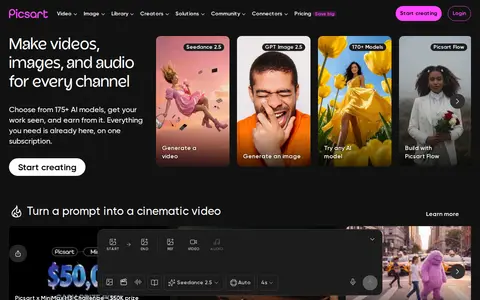
Picsart is described as an all-in-one creative platform offering free AI design tools, templates, and asset libraries. It also supports generating and editing videos, images, and audio, with access to multiple AI models under a subscription.
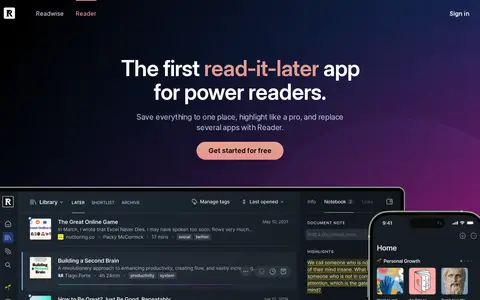
Readwise Reader is a read-it-later app that saves articles, newsletters, RSS feeds, PDFs, EPUBs, YouTube videos and Twitter threads in one place. It offers web highlighting and annotation through a browser extension and integrates with the Readwise app, which resurfaces highlights via Daily Review and exports them to note-taking tools.
Renderforest is an AI-powered creative platform for making videos, designs, and websites. It offers AI video, image, and audio generation, over 1200 video templates, an AI video editor, AI website builder, and logo generator. The pricing page lists Lite, Pro, and Business plans, with a free plan available.
Retrieval-based-Voice-Conversion-WebUI is a project for training voice conversion models from voice data, with an easy-to-use WebUI. It includes a pymss/MSST model to separate vocals and instruments and a high-pitch voice extraction algorithm to prevent a muted sound problem. Dependencies differ by hardware, including CPU, AMD, Intel and NVIDIA GPU setups.
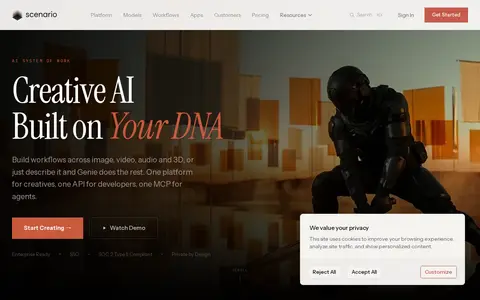
Scenario is a platform for creative production and game assets that brings together image, video, 3D and audio generation models. Users build pipelines as nodes on a canvas and can publish a chain as an app for teammates. It offers custom model training on reference images and connects to assistants and code through Scenario MCP and a REST API.
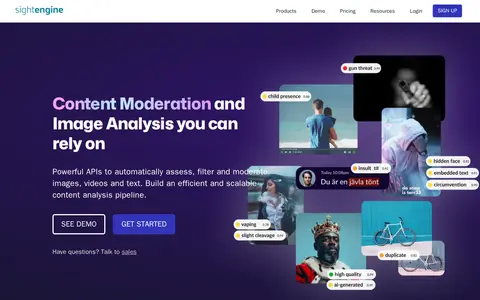
Sightengine provides APIs for assessing, filtering and moderating images, videos, text and audio. It detects nudity, violence and offensive content, and flags AI-generated media such as images, video, speech and music. Additional models cover face liveness, near-duplicate and spam detection, and OCR, returning JSON detection results from a single API call.
SkillBoss supports AI agents, automated workflows, orchestration, or delegated tasks.
SOUNDRAW is an AI music generator that lets users create royalty-free beats in seconds. It supports genre blending, instrument customization, stem downloads, and music monetization. Its AI is trained exclusively on in-house created music, with no use of scraped content, to ensure copyright-safe outputs for creators and artists.
Create professional videos using just a still image with text or audio powered by AI.
Text-to-Music And Text-to-Image Generator is a Hugging Face Space created by HarshRathi09. It accepts text prompts to generate either musical compositions or images, allowing users to turn ideas into audio or visual content. The space is currently running.
Toolbaz offers free AI tools for writing, image and audio generation, powered by models including GPT-5, Claude, Gemini and Meta-AI. The site lists writer tools such as article and content writer, story and book writer, and rewriting and editing tools.
Tortoise TTS is an open-source multi-voice text-to-speech system hosted on the GitHub repository neonbjb/tortoise-tts, trained with an emphasis on output quality. An associated Hugging Face space for the project is available for demonstration.
Treblo, formerly Sonauto, is a free AI music generator that turns ideas into songs with lyrics, vocals and thousands of styles. It offers unlimited songs, editing, covers and remixes, and is available on iOS and Android.
A free online text-to-speech tool that converts text into speech using an AI voice generator. It offers 100+ voices in 27 languages, allows MP3 download, and lets users adjust speed and pitch. No registration is required.
Vimeo Create is Vimeo's free online video creation and editing tool. It offers customizable video templates, in-browser editing, video hosting, streaming capabilities, and AI-powered features including audio and caption translation.
VocalRemover is a free online application that separates a song into a karaoke version without vocals and an acapella version with isolated vocals. It uses artificial intelligence algorithms and processing usually takes about 10 seconds.
VCClient is software that performs real-time voice conversion using AI. It supports several AI models and offers both standalone use on a local PC and voice conversion over a network, and it provides a REST API. Editions support different models, and Windows and M1 Mac versions can be downloaded from a Hugging Face repository.
A site for browsing AI voice models for RVC. It lists 30,000+ voice models covering characters, singers and creators, allows previewing samples, and supports running compatible voices online with EasyAIVoice.