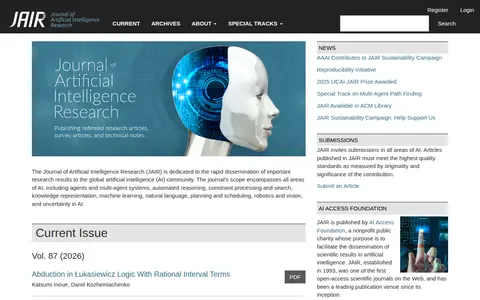
The Journal of Artificial Intelligence Research (JAIR) is a journal dedicated to the rapid dissemination of important research results to the global AI community. Its scope encompasses all areas of AI, including agents and multi-agent systems, automated reasoning, knowledge representation, machine learning, natural language, planning and scheduling, robotics and vision, and uncertainty in AI.
MusicLM
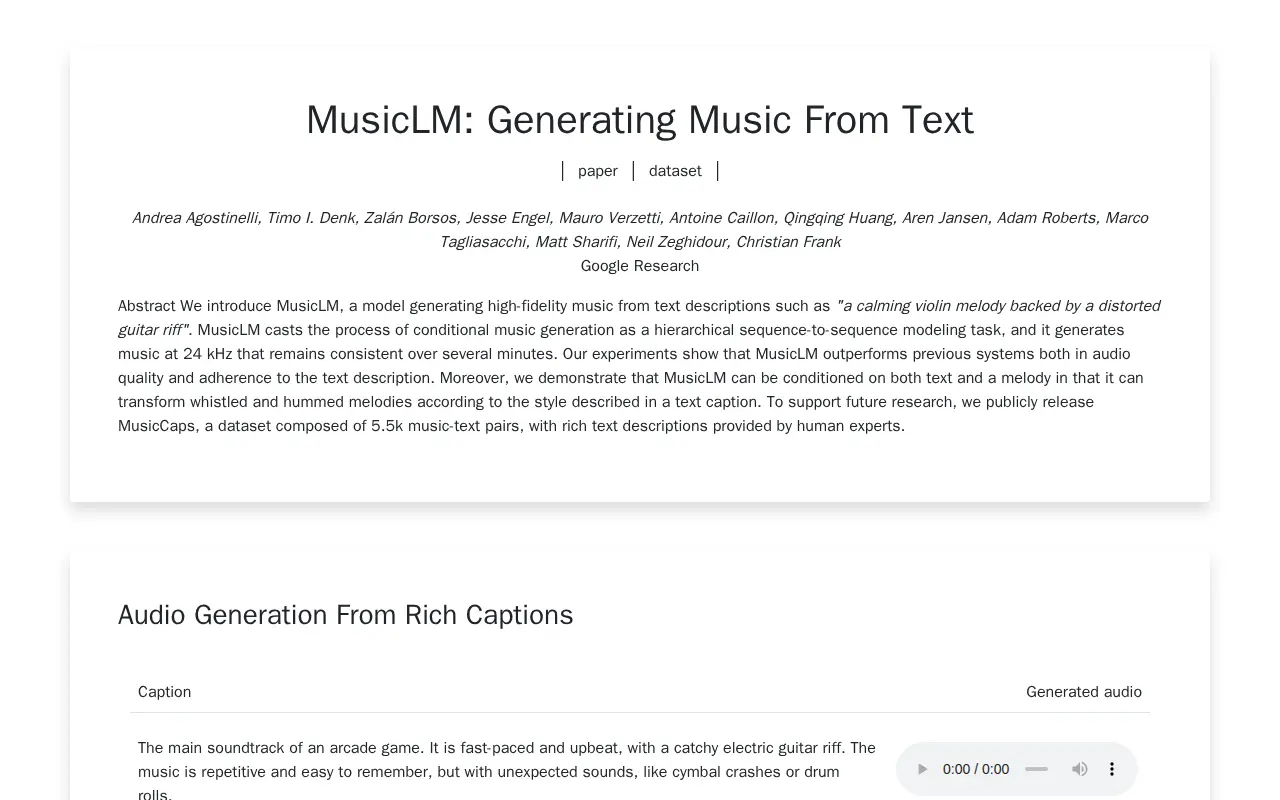
MusicLM is a model that generates high-fidelity music from text descriptions. It frames conditional music generation as hierarchical sequence-to-sequence modeling and produces audio at 24 kHz consistent over several minutes. It can also be conditioned on text and a melody, transforming whistled or hummed melodies according to a text caption. The project released MusicCaps, a dataset of 5.5k music-text pairs with descriptions by human experts.
Website Directory import
Features
- generates music at 24 kHz consistent over several minutes Source: google-research.github.io
Links
Tags
-
 0
The Journal of Artificial Intelligence Research (JAIR) is a journal dedicated to the rapid dissemination of important research results to the global AI community. Its scope encompasses all areas of AI, including agents and multi-agent systems, automated reasoning, knowledge representation, machine learning, natural language, planning and scheduling, robotics and vision, and uncertainty in AI.
-
 0
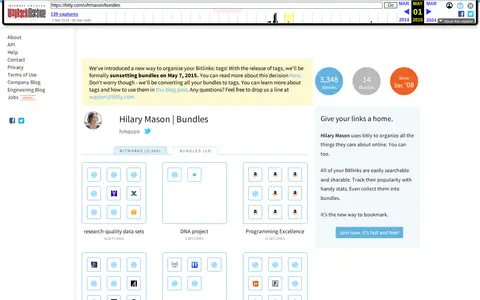
An archived Bitly bundles page belonging to Hilary Mason, listing link collections on topics such as research-quality data sets, programming, data stories and data science blogs. The page notes that Bitly sunset bundles on May 7, 2015 and converted them to tags.
-
 0
Scholarcy is a tool for summarizing and organizing research, built around AI-powered tools described as made specifically for academic papers. It converts long texts into interactive summary flashcards highlighting key information, and accepts imports including PDFs, book chapters, articles, Zotero, Google Drive and YouTube. Summaries can be enhanced and exported to other apps and citation managers.
-
 0
Telborg tracks construction and power developments for Texas data centers, drawing on state and county filings. It reports new campuses, power facilities and semiconductor fabs, along with the operator behind an LLC, design and construction firms, approval stage and power supplier. The site also offers a siting demo for a Corpus Christi industrial corridor.
-
 0
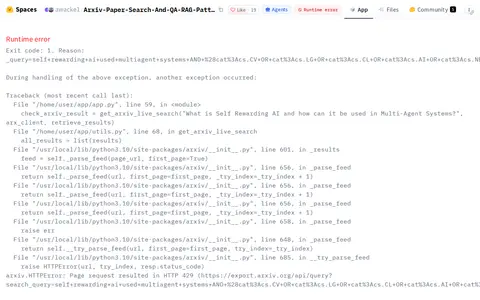
Interactive Hugging Face app that helps find, analyze or synthesize information for research and knowledge discovery.
-
 0
Cosmos generates 30-second video essays from a typed idea, with sourced facts, archive pictures, a voiceover and original music. Films can be made free up to three a day, with a watermark, and a clean 1080p MP4 can be bought for $9. No credit card is required to start and there is no subscription.
Community notes
Reviews and discussion
No reviews yet
Be the first to share how this project worked for you.
Join the discussion
Sign in with a verified account to leave a review or join the discussion.
Sign in to reviewKeep exploring
More in AI Search & Research
web.archive.org
An archived Bitly bundles page belonging to Hilary Mason, listing link collections on topics such as research-quality data sets, programming, data stories and data science blogs. The page notes that Bitly sunset bundles on May 7, 2015 and converted them to tags.
scholarcy.com
Scholarcy is a tool for summarizing and organizing research, built around AI-powered tools described as made specifically for academic papers. It converts long texts into interactive summary flashcards highlighting key information, and accepts imports including PDFs, book chapters, articles, Zotero, Google Drive and YouTube. Summaries can be enhanced and exported to other apps and citation managers.
telborg.com
Telborg tracks construction and power developments for Texas data centers, drawing on state and county filings. It reports new campuses, power facilities and semiconductor fabs, along with the operator behind an LLC, design and construction firms, approval stage and power supplier. The site also offers a siting demo for a Corpus Christi industrial corridor.
huggingface.co
Interactive Hugging Face app that helps find, analyze or synthesize information for research and knowledge discovery.
meetcosmos.com
Cosmos generates 30-second video essays from a typed idea, with sourced facts, archive pictures, a voiceover and original music. Films can be made free up to three a day, with a watermark, and a clean 1080p MP4 can be bought for $9. No credit card is required to start and there is no subscription.