Hadoop Illuminated's Chapter 16 page lists pointers to publicly available big data sets, covering generic repositories, geo data, web data and government data. It links to sources such as Amazon AWS data sets, InfoChimps, the Comprehensive Knowledge Archive Network, OpenStreetMap, Wikipedia data, Google N-gram data, Freebase, data.gov and World Bank data.
Directory
Search results
Published directory entries matching your search.
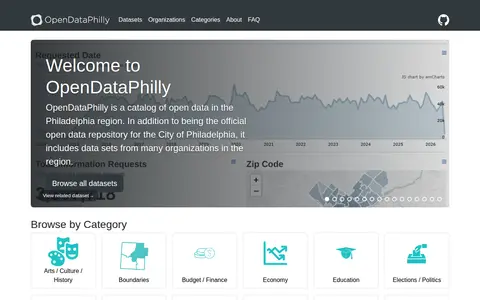
OpenDataPhilly is a catalog of open data in the Philadelphia region. It is the official open data repository for the City of Philadelphia and also includes data sets from many organizations in the region. The catalog covers categories such as arts, culture and history, boundaries, budget and finance, economy, education, elections and politics, environment, food, health and human services, parks and recreation, planning and zoning, public safety, real estate and land records, and transportation.
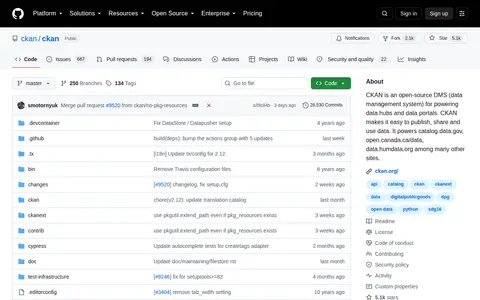
CKAN is an open-source data management system for creating and operating data hubs and portals. It enables organizations to publish, share, and use data. It powers government data sites such as data.gov, open.canada.ca, and humdata.org.
RedPajama-Data-v2 is a 30 trillion token open dataset from 84 CommonCrawl dumps across five languages, with over 40 precomputed quality annotations. Data processing scripts are open source on GitHub and all data are available on HuggingFace. The dataset is intended for further filtering and weighting of data, and the release notes describe it as an open dataset for training large language models.
IGSR, the International Genome Sample Resource, provides open human variation data. Data files from many studies are shared via FTP, with key data sets presented in a data portal browsable by sample, population, technology, data type and collection. Ensembl presents some key call sets in genomic context. Bulk downloads are recommended via Globus, with FTP and Aspera also available.
Open Government Data Platform India applies AI to data analysis, extraction, visualization, or business intelligence.
VisPy is a high-performance interactive 2D/3D data visualization library that uses GPUs through OpenGL to display large datasets. It offers a Pythonic, NumPy-aware interface for OpenGL ES 2.0 called gloo and an experimental OpenGL backend for matplotlib. The project is described as young and under heavy development, with high-level plotting interfaces still experimental.
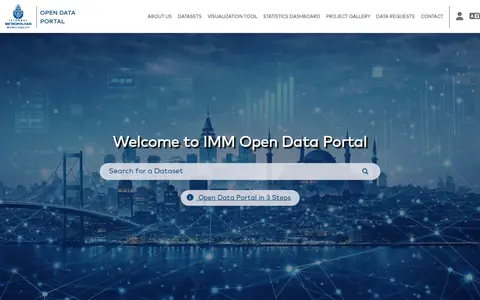
Istanbul Metropolitan Municipality's open data platform enables users to search for datasets by keyword or topic, review them, and download data or query it via API to create projects. Published datasets are labeled under categories such as energy, economy, environment, mobility and governance.
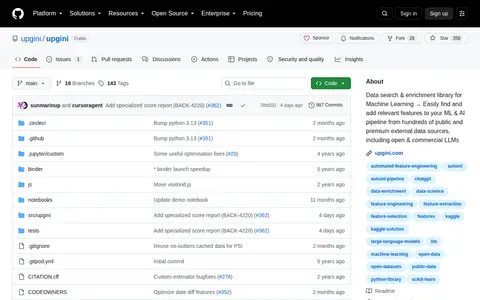
Upgini is an open-source data search and enrichment library for Machine Learning and AI pipelines. It enables users to find and add relevant features from hundreds of public and premium external data sources, including open and commercial large language models.
mexopencv is a collection and development kit of MATLAB MEX functions for the OpenCV library. It provides MATLAB MEX functions interfacing a hundred OpenCV APIs and includes a C++ class converting between MATLAB and OpenCV data types. The package is intended for fast prototyping of OpenCV applications in MATLAB and for developing custom MEX functions.
An archived, read-only GitHub repository holding an open solution to the Google AI Open Images Object Detection Track. It offers starter code, configs and notebooks, with RetinaNet training and references to the Neptune experiment platform; Neptune use is optional and the code can run as a plain Python script. The README notes the competition used Open Images Dataset V4.
ReadStat.jl, listed as Data Read, is an open-source Julia library for reading data files in Stata, SAS, and SPSS formats. The project is hosted on GitHub under the queryverse organization, where users can access source code and contribute to its development.
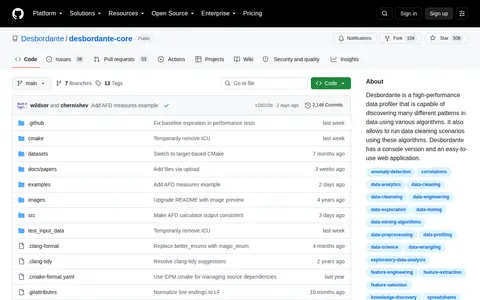
Desbordante is a high-performance open-source data profiler. It uses a variety of algorithms to discover different patterns in data and supports running data cleaning scenarios using these algorithms. The tool is available as a console version and an easy-to-use web application.
KNIME Analytics Platform is free and open source data analytics software with a visual workflow builder for creating data science solutions. The page lists access, blending and transformation of data from any source, visualization and analysis, and saving, sharing and reuse of workflows. It also describes integrating scripting in Python, R and JavaScript and deploying solutions in the enterprise.
A federated, open-source data catalog for all your big data and small data.
pandas is an open source, BSD-licensed library providing high-performance, easy-to-use data structures and data analysis tools for the Python programming language. It is described as a data analysis and manipulation tool built on top of Python. Documentation, a user guide and an API reference are available.
Redash is an open source tool for connecting to data sources, querying, visualizing and sharing data. It supports SQL, NoSQL, Big Data and API sources including PostgreSQL, MySQL, Redshift, BigQuery and MongoDB. Users build dashboards, set alerts and manage access.
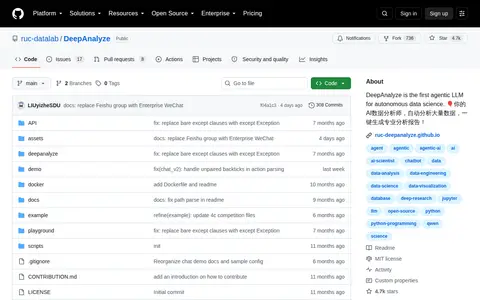
An agentic LLM for autonomous data science that performs data preparation, analysis, modeling, visualization, and report generation without human intervention. It supports open-ended research on structured, semi-structured, and unstructured data sources, and the model, code, training data, and demo are open-sourced.
Open-source project that applies AI to data analysis, extraction, visualization, or business intelligence.
LINDAT/CLARIAH-CZ Repository is a repository for linguistic data and NLP tools. It supports free and safe deposits with a license of choice, encouraging open licenses, and provides citation support with persistent IDs. Publicly available items include corpora and lexical resources, such as Czech, Slovak, Russian and Belarusian locative adverb data.
Dagster is an open source, cloud-native data pipeline orchestrator for the data development lifecycle, with integrated lineage and observability. Users declare data assets as Python functions, and Dagster runs them and keeps assets up to date. It is designed for developing and maintaining data assets such as tables, data sets, machine learning models, and reports.
A blog documenting a self-designed open source data science master's program. Posts cover a six-month plan to become a data scientist, study examples after one month, MOOCs versus classroom learning, and a final project using the D3.js library to present what was learned.
DrivenData hosts online machine learning competitions with social impact and works with mission-driven organizations on data science and engineering projects. It also maintains open-source projects for the data science community and shares prize-winning solutions from past competitions on GitHub. Areas of work include public health, conservation and international development.
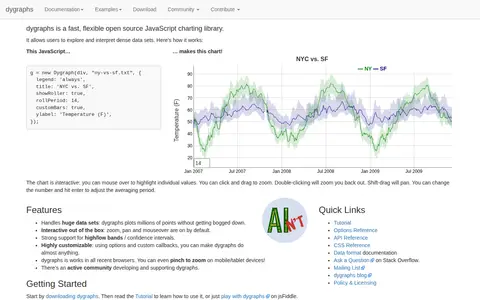
dygraphs is a fast, flexible open source JavaScript charting library that allows users to explore and interpret dense data sets. Charts are interactive, with zoom, pan and mouseover available by default, and the library handles very large data sets. It works in all recent browsers.