Text To Sql Example Explanation is a Hugging Face Space created by user suriya7. It accepts natural language queries and table details as input, and outputs a corresponding SQL query, sample query results, and an explanation of the generated query.
Directory
Search results
Published directory entries matching your search.
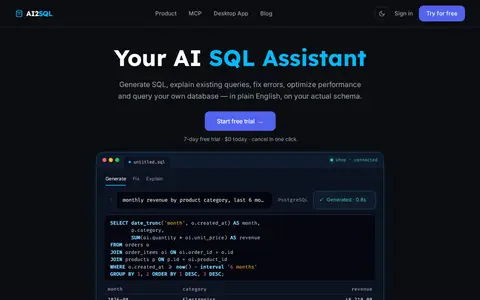
AI-powered SQL query builder enables you to quickly build SQL queries without any knowledge of SQL for beginners.
Apache Hama is a retired Apache Software Foundation Top-Level Project established in 2012. It is a framework for Big Data analytics that uses the Bulk Synchronous Parallel (BSP) computing model. It also provides vertex-centric and neuron-centric programming models inspired by Google's Pregel and DistBelief. Its components include core BSP, Apache MRQL for query processing, a graph computing package, and Apache Horn for deep learning, and it integrates with Hadoop HDFS.
AskYourDatabase is a tool for querying SQL databases in natural language, returning SQL, answers, and charts. It supports PostgreSQL, MySQL, SQL Server, BigQuery, Snowflake, and other engines. Offerings include a Windows or macOS desktop app, an embeddable website chatbot, a dashboard builder, and a private deployment option for organizations with hosting or data-handling requirements.
This repository collects notebooks that explore Retrieval-Augmented Generation (RAG) for various applications, from introductory to advanced implementations. It includes a full_basic_rag.ipynb starter and notebooks on multi-querying, routing, query construction, indexing, and advanced retrieval. The materials cover environment setup, data loading, embedding generation, and vector store configuration with ChromaDB or Pinecone.
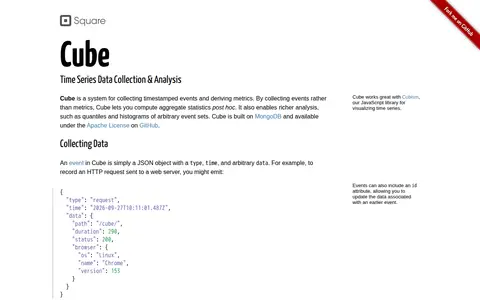
Cube is a system for collecting timestamped events and deriving metrics, built on MongoDB and released under the Apache License on GitHub. It accepts events via UDP, HTTP POST, and WebSockets, defines a query language for retrieving events, and groups events by time to compute aggregate metrics.
ReadStat.jl, listed as Data Read, is an open-source Julia library for reading data files in Stata, SAS, and SPSS formats. The project is hosted on GitHub under the queryverse organization, where users can access source code and contribute to its development.
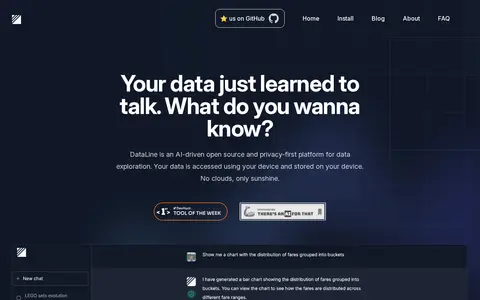
DataLine is an AI data analysis and visualization tool that lets users chat with their data to generate tables, charts, and dashboards. The page describes it as suited to non-technical people querying data and to developers seeking a text2sql solution.
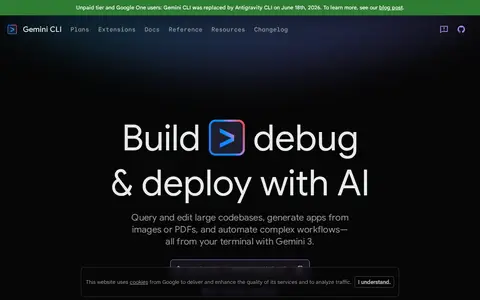
Gemini CLI is a terminal-based tool that brings Gemini models into the local development environment. It can query and edit large codebases, generate apps from images or PDFs, and automate workflows. Documentation covers configuration, extensions, agent skills, and IDE integration. Release channels include nightly, preview, and stable.
GeoLite databases and web services from MaxMind provide free geolocation and limited network data for IP addresses. The data is less accurate than MaxMind's paid GeoIP products. A free GeoLite account is required to download databases or query the web services, which use the same integration methods and documentation as GeoIP with minor modifications.
GritQL is a declarative query language from Grit for searching and modifying source code. It lets users search with code snippets and metavariables, define custom lints, and apply auto-fix rules, and it supports rewriting JavaScript/TypeScript, Python, JSON, Java, Terraform, Solidity, CSS, Markdown, YAML, Rust, Go and SQL.
ChainForge is an open-source visual programming environment for battle-testing prompts to large language models. It supports querying multiple models at once, comparing response quality across prompts, models and model settings, and setting evaluation metrics to visualize results. Built on ReactFlow and Flask, it can be installed locally with pip or tried on the web, where features are limited.
Istanbul Metropolitan Municipality's open data platform enables users to search for datasets by keyword or topic, review them, and download data or query it via API to create projects. Published datasets are labeled under categories such as energy, economy, environment, mobility and governance.
Impala is a distributed C++ query engine for SQL queries over petabytes of data stored in Apache Hadoop clusters. It supports data in HDFS, Apache HBase and Amazon S3, window functions and subqueries, and uses LLVM for on-the-fly code generation. It is Apache-licensed and open source, and the repository is a mirror of Apache Impala.
LabNotebook is a tool that allows you to flexibly monitor, record, save, and query all your machine learning experiments.
Metabase is an open source analytics and business intelligence platform. It grounds answers in a governed semantic layer of metrics and business logic so the query behind each answer can be inspected. It supports querying data in plain English with AI, interactive dashboards, documents, subscriptions and alerts, and embedded analytics. Users can self-host or use Metabase Cloud.
MongoDB is a document-oriented operational database that stores data in flexible JSON-like documents. The documentation describes built-in query capabilities including geospatial search, lexical search and vector search, and the platform page lists Atlas use cases such as vector search and stream processing.
Pavlov.js is a reinforcement learning library that uses Markov Decision Processes. It is written in C++ and compiled to JavaScript. The package is installed through npm. Users define transitions and rewards, then call learn to derive a policy and query actions for states.
Polars is an extremely fast open-source query engine for DataFrames written in Rust, hosted as a GitHub repository under the pola-rs organization. It is built to handle large datasets, including data volumes that exceed available system RAM.
A python framework to transform natural language questions to queries in a database query language.
Redash is an open source tool for connecting to data sources, querying, visualizing and sharing data. It supports SQL, NoSQL, Big Data and API sources including PostgreSQL, MySQL, Redshift, BigQuery and MongoDB. Users build dashboards, set alerts and manage access.
Statewave is an open-source memory runtime for AI agents. It uses reproducible, provenance-tagged context bundles in place of query-time retrieval, is licensed under Apache-2.0, self-hosted on Postgres with pgvector, and offers Python and TypeScript SDKs. The project is hosted on GitHub under the smaramwbc organization.
This Hugging Face Space generates SQL queries from natural language for datasets on Hugging Face; users enter a dataset and a query. The Space is currently paused, and the author can be asked to restart it.
A lightweight, self-hosted workspace for databases that runs in the browser and is also available as a desktop app or terminal CLI. It offers spreadsheet-style data editing, a visual schema graph and a query scratchpad, with optional AI features through a chosen provider.