github.com
Data-to-paper: AI-driven research from data to human-verifiable research papers.
Directory
Published directory entries matching your search.
Data-to-paper: AI-driven research from data to human-verifiable research papers.
LinkedIn's generalized metadata search & discovery tool.
A blog documenting a self-designed open source data science master's program. Posts cover a six-month plan to become a data scientist, study examples after one month, MOOCs versus classroom learning, and a final project using the D3.js library to present what was learned.
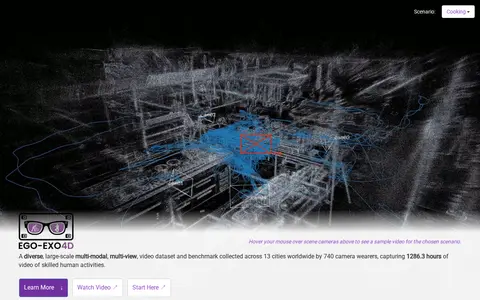
Ego-Exo4D is a large-scale multi-modal, multi-view video dataset and benchmark of simultaneously captured ego-centric and exo-centric video of skilled human activities such as sports, music, dance, and bike repair. It includes natural language datasets, multi-view capture with Aria glasses and GoPros, and benchmarks including Keystep Recognition and Proficiency Estimation.
DB GPT is an open-source agentic AI data assistant developed by eosphoros-ai and hosted on GitHub, designed for use in next-generation AI and data products. It offers capabilities including agentic data analysis and autonomous SQL and code execution.
Official PyTorch implementation of the CVPR 2019 paper on deep high-resolution representation learning for human pose estimation. The network maintains high-resolution representations through the whole process and connects multi-resolution subnetworks in parallel with repeated multi-scale fusions. Results are reported on the COCO keypoint detection dataset and the MPII Human Pose dataset.
An agentic LLM for autonomous data science that performs data preparation, analysis, modeling, visualization, and report generation without human intervention. It supports open-ended research on structured, semi-structured, and unstructured data sources, and the model, code, training data, and demo are open-sourced.
Deepchecks is an open-source project for validating machine learning models and data from research to production. It includes built-in and custom checks and suites for tabular, NLP and CV validation, CI and testing management, and monitoring of deployed models. Installation is via pip.
Delta Lake is an open-source storage framework designed to support the construction of a Lakehouse architecture. It is compatible with multiple compute engines including Apache Spark, PrestoDB, Flink, Trino, and Hive, as well as associated APIs.
Listof - Community based data collection, packed in gem. Get list of pretty much anything (stop words, countries, non words) in txt, JSON or hash.
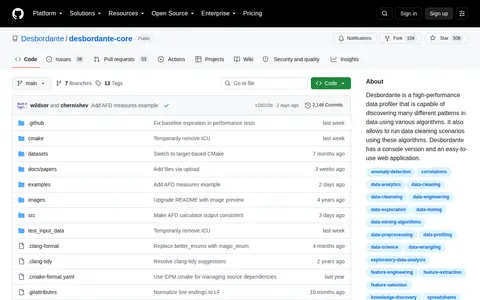
Desbordante is a high-performance open-source data profiler. It uses a variety of algorithms to discover different patterns in data and supports running data cleaning scenarios using these algorithms. The tool is available as a console version and an easy-to-use web application.
Basic proof of concept for genetic architecture search in Keras.
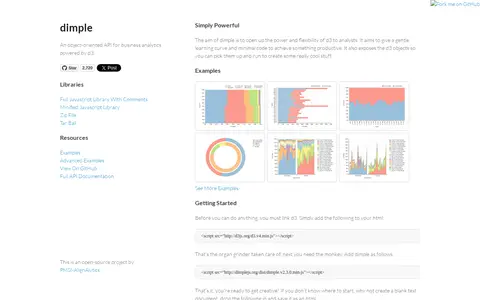
Dimple is an open-source charting API for d3 aimed at business analytics, letting users create and combine bar, line, area and scatter charts. It exposes underlying d3 objects so analysts can build on them, and requires linking d3 before adding dimple to a page.
A Java scientific and numerical library written by Michael Thomas Flanagan to support his research and undergraduate programming courses. It is distributed as the flanagan.jar package and includes general classes, example programs and arbitrary precision methods. The author has retired and states it will be updated less frequently. Commercial use, public listing of source codes and redistribution are not permitted.

DrivenData hosts online machine learning competitions with social impact and works with mission-driven organizations on data science and engineering projects. It also maintains open-source projects for the data science community and shares prize-winning solutions from past competitions on GitHub. Areas of work include public health, conservation and international development.

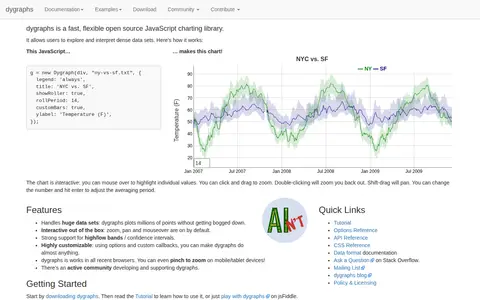
dygraphs is a fast, flexible open source JavaScript charting library that allows users to explore and interpret dense data sets. Charts are interactive, with zoom, pan and mouseover available by default, and the library handles very large data sets. It works in all recent browsers.

Effective Python: 125 Specific Ways to Write Better Python, 3rd Edition is a book by Brett Slatkin, published by Pearson Addison-Wesley in November 2024. It expands on the second edition from 90 to 125 best practices for writing Python code, adds new chapters on robustness and performance, and covers the language through Python version 3.13.
ELKI is an open source data mining software written in Java. It focuses on research in algorithms, emphasizing unsupervised methods in cluster analysis and outlier detection, and offers data index structures for performance and scalability. It is designed for researchers and students to extend.
Enigma is a business data platform that provides access to millions of public, private and proprietary data points on businesses and people, supporting workflows including know-your-business verification, customer onboarding, go-to-market operations, payment risk assessment and customer screening.
Exhibit is an open source publishing framework for creating data-rich interactive web pages. It provides advanced text search and filtering, along with interactive maps, timelines and other visualizations. The software is licensed under the BSD license and was originally sponsored partially by The Andrew W. Mellon Foundation as part of the SIMILE project.
Explainpaper is a tool for reading research papers. Users highlight confusing text to get explanations, and can ask follow-up questions. It offers plans from a free tier to paid Pro and Teams options, with Pro including advanced AI models and clickable explanations for graphs, figures and equations.
Helps find, analyze or synthesize information for research and knowledge discovery.
ImageBind is a PyTorch implementation with pretrained models from FAIR, Meta AI. It learns a joint embedding across six modalities: images, text, audio, depth, thermal, and IMU data. The release includes code and model weights under the CC-BY-NC 4.0 license.
Foundational Models for State-of-the-Art Speech and Text Translation.