Datacast is the personal blog and podcast series of James Le. It features written posts and podcast episodes covering topics such as data infrastructure, data observability, responsible AI, product management, and data engineering.
Directory
Search results
Published directory entries matching your search.
DataTalks.Club is an online community for data science professionals, ML engineers and AI practitioners. It offers free courses, weekly podcasts, webinars, workshops and book discussions, along with articles, a Slack group and a weekly newsletter. Events and podcast episodes cover topics such as machine learning, AI platforms and LLM engineering.
Devika is an open-source implementation of an Agentic Software Engineer, initially started as an alternative to Devin. It uses large language models, planning and reasoning algorithms, and web browsing to develop software from human instructions. The project is in an early experimental stage, and the repository notes that there are unimplemented or broken features.
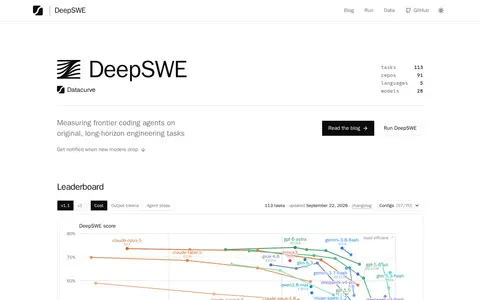
DeepSWE is a GitHub repository that provides a benchmark for measuring the performance of frontier coding AI agents on original, long-horizon engineering tasks. The repository includes documentation on task format, quickstart guides, and details about supported agents and models.
DeepLearning.ai is an educational platform led by Andrew Ng that offers online AI courses, specializations, and certifications for people learning to use and build artificial intelligence. The platform serves over 7 million learners and covers topics including AI Python, prompt engineering, generative AI, and machine learning.
DeepSWE is a benchmarking platform that evaluates frontier coding agents on original, long-horizon software engineering tasks. It provides a public leaderboard, task examples, and tracks results across 113 tasks, 91 repositories, 5 programming languages, and 28 models.
Delta Lake is an open-source storage framework designed to support the construction of a Lakehouse architecture. It is compatible with multiple compute engines including Apache Spark, PrestoDB, Flink, Trino, and Hive, as well as associated APIs.
Devin is an AI coding agent and software engineer that helps developers build better software faster. It runs in the cloud or on a machine, tests in its own browser, and works from problem to merged pull request. Plans include Free, Pro, Max, Teams, and Enterprise.
Devv AI is an AI-powered search engine designed for developers, providing fast and accurate results to programming-related queries. Its GitHub repository is issues-only, used for bug reports, feature requests, questions and feedback about the tool.
Dexter Storey is a GitHub user profile for an AI engineer, artist, and hacker. The profile indicates work on RubricLab and involvement in AI and open-source projects. It showcases contributions and repositories related to AI and creative coding.
Open-source project that supports AI agents, automated workflows, orchestration, or delegated tasks.
DigitalOcean describes an AI-native cloud platform with a unified stack for agents, inference and cloud infrastructure. Products listed include Managed Agents, Learning Services, Data Services, an Inference Engine with over 75 models, and core cloud services such as Droplets, Kubernetes and App Platform. Harness Runtime is listed starting at $0.0535/hr for durable cloud sandboxes for AI coding agents.
distilabel is a framework for synthetic data generation and AI feedback intended for engineers. It provides fast, reliable, and scalable pipelines based on verified research papers, supporting data synthesis for AI systems and on-the-fly feedback addition. The framework aims to improve AI output quality via enhanced data quality, give users control over their data and models, and boost efficiency through rapid iteration on research and large language models.
Dosu is knowledge infrastructure for engineering teams and the coding agents they work with. It keeps documentation, specifications and agent memory current with code changes, and connects to tools such as GitHub, GitLab, Slack, Notion and Confluence. A free plan covers public repositories with 200 credits per month; the Pro plan is listed at $16/month with 4,000 credits per month.
DrivenData hosts online machine learning competitions with social impact and works with mission-driven organizations on data science and engineering projects. It also maintains open-source projects for the data science community and shares prize-winning solutions from past competitions on GitHub. Areas of work include public health, conservation and international development.
EmotiVoice is an open-source text-to-speech engine that speaks English and Chinese with over 2000 voices. Its main feature is emotional synthesis across emotions such as happy, excited, sad and angry. It provides a web interface and a scripting interface for batch generation.
Machine learning development environment for data science and AI/ML engineering teams.
EvalML is an AutoML library written in Python that builds, optimizes, and evaluates machine learning pipelines using domain-specific objective functions. It includes data quality checks, cross-validation, preprocessing, feature engineering, feature selection, and model understanding tools. Install from PyPI or conda-forge.
A blog post summarizing a University of Illinois study on solo performance prompting (SPP), a prompt engineering method in which an LLM summons multiple personas that collaborate on a task. The post describes the SPP prompt structure and reports on three experiments: Trivia Creative Writing, Codenames Collaborative, and Logic Grid Puzzle.
Fast inference engine for whisper in C++ using CTranslate2.
Feature engineering package with SKlearn like functionality.
Feature Stores for ML is a global community of data science professionals, researchers, and engineers focused on feature stores for machine learning pipelines. It creates educational content about feature stores and the surrounding data and AI ecosystem, hosts monthly industry meetups, and provides resources including blog posts, videos, benchmarks, and an MLOps dictionary.
Python library for automated feature engineering.
Apache Flink is a distributed data processing engine for stateful computations over data streams. It offers exactly-once state consistency, event-time processing, layered APIs including SQL on stream and batch data, and flexible deployment with savepoints. Its stated use cases include event-driven applications, stream and batch analytics, and data pipelines and ETL.