Wispr Flow is a voice-to-text dictation tool that converts speech into text in any app and on every device. It includes a Notetaker feature. It is available on Mac, Windows, iPhone, and Android. A free plan includes speech-to-text in any app and 100+ languages; paid plans add team management and admin controls.
Directory
Search results
Published directory entries matching your search.
AI Voice Generator is a free online tool that produces natural-sounding text-to-speech voice overs. Users enter text, select from various AI voices, and generate a voiceover. The service emphasizes simplicity and accessibility for creating spoken content.
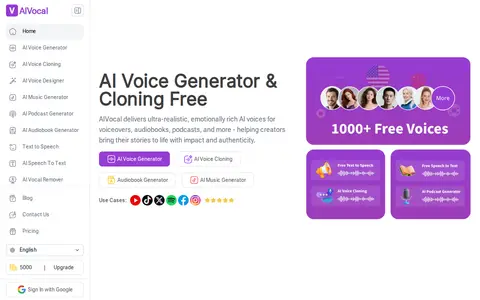
AIVocal is an AI-powered voice assistant platform. It provides tools for AI voice generation, voice cloning, text-to-speech, speech-to-text, vocal removal, audiobook generation, podcast generation and audio transcription, serving creators and professionals for voice-related work.
AnyVoiceLab offers a free long-form text-to-speech converter that processes up to 50,000 characters, about one hour of audio, without requiring login. Users paste text and choose a voice to generate narration and can download the audio for free. A paid premium tier adds a timeline editor for pauses, speed changes, splitting and merging audio.
AudioCraft is a code base for generative audio tasks including music, sound effects, and compression, trained on raw audio signals. MusicGen produces music samples from text inputs, and AudioGen produces audio from environmental sounds via text-to-sound generation. The models use the EnCodec neural audio codec to learn discrete audio tokens from waveforms.
Chatterbox TTS is a Hugging Face Space by ResembleAI that converts up to 300 characters of written text into spoken audio. It can optionally use a short reference recording to make the voice resemble a specific speaker, and includes adjustable settings described as expressive zeroshot text-to-speech.
MMAudio is a Hugging Face Space that generates synchronized audio from video or text. Users can upload a short video and write a prompt, including a negative prompt, to add realistic sound, or create a standalone audio clip from a text description.
Fish Audio provides AI text-to-speech and voice cloning with emotion control and multilingual support. It offers TTS, speech-to-text, voice agents, and developer APIs with Python and TypeScript SDKs. The site lists a free tier with 8,000 monthly credits and paid Plus, Pro, and Max plans.
GPT-SoVITS is a few-shot voice conversion and text-to-speech WebUI. It supports zero-shot TTS from a five-second vocal sample and fine-tuning with one minute of training data. Cross-lingual inference covers English, Japanese, Korean, Cantonese and Chinese. Integrated WebUI tools include voice accompaniment separation, training set segmentation, Chinese ASR and text labeling.
Moe TTS is a Hugging Face Space created by skytnt that enables users to generate speech from input text and convert existing audio to a different speaker's voice. Users can input text to create speech output, select from available speakers, and adjust the playback speed of generated audio.
MusicGen is a single-stage auto-regressive Transformer model for music generation trained over a 32kHz EnCodec tokenizer with four codebooks, part of the AudioCraft library. It supports text-to-music and text-plus-melody-to-music models ranging from 300M to 3.3B parameters. Running it locally requires a GPU, with at least 16 GB of memory recommended for medium-sized models.
Ondoku is text-to-speech software that reads text up to 5,000 characters free of charge and offers paid plans converting up to 1 million characters a month. Generated audio can be saved as MP3 files and used commercially. It runs in a browser on PC or smartphone without installation.
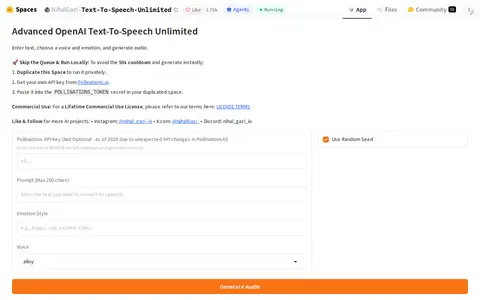
A Hugging Face Space that generates speech from entered text. Users choose a voice and an emotion style and can optionally set a seed. The app sends requests to the Pollinations service and returns an MP3 file with the synthesized speech.
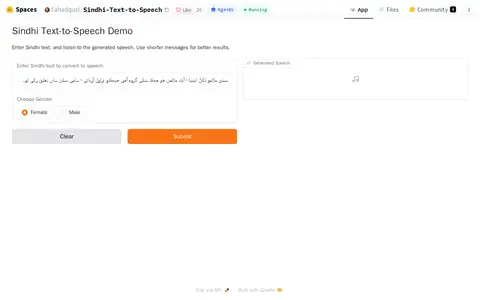
Sindhi TTS is a Hugging Face Space that generates speech from Sindhi text. Users input text and select a gender for the synthesized voice. The system works best with shorter messages.
Speechify is a text to speech and voice typing assistant that reads books, PDFs, documents and web pages aloud with natural-sounding voices. It offers text highlighting, speed control and scan and listen, and is available as browser extensions, desktop apps for Windows and Mac, and mobile apps for iOS and Android.
Speechma is an online text-to-speech converter that turns text into audio using a library of AI voices. The site states that no registration is required and that generated audio can be used commercially. A REST API for developers is also offered under a monthly subscription.
A free online text-to-speech tool that converts text into speech using an AI voice generator. It offers 100+ voices in 27 languages, allows MP3 download, and lets users adjust speed and pitch. No registration is required.
TTS WebUI is a free Gradio-based web interface for text-to-speech, audio and music generation. It can generate audio from text using over 30 AI models, including Bark, MusicGen, Tortoise and Vocos, and offers voices from the Bark Speaker Directory. Installation is available through one-click installers or manual setup.
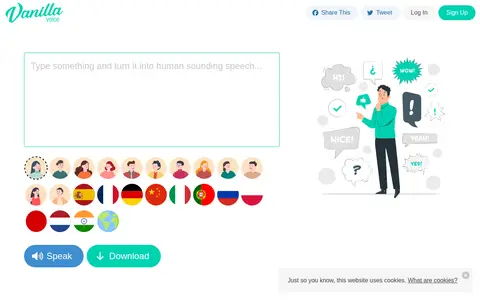
VanillaVoice is a free online text to speech tool that reads text aloud with human-sounding voices. Users can pick male, female or child voices in many languages, adjust volume and speed, and download audio as an MP3 without installing software. A Professional Plan offers a commercial license, speech-enabled products and up to 500 words per recording.
XTTS is a Hugging Face Space that provides multi-language text-to-speech functionality. It converts written text into spoken audio across multiple languages, and allows users to optionally upload a short voice recording or use their microphone for voice input.
Acapela Group is a company that develops personalized digital voices using voice AI technology. It offers text-to-speech solutions for services, applications and devices, with support for over 30 languages and more than 200 pre-made voices, plus custom voice creation options. The company provides SDKs for multiple platforms, cloud streaming APIs, and specialized solutions including voice AI for accessibility, transport and customer interaction.
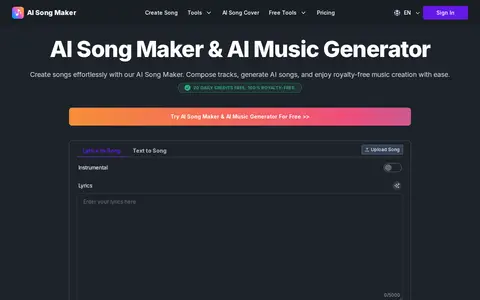
A web tool for generating songs from text, lyrics or uploaded audio, with style, voice and tempo options and instrumental-only tracks. Songs can be downloaded or shared. The free tier offers 20 daily credits and royalty-free output.
Audio diffusion library for PyTorch that includes models for unconditional audio generation, text-conditional audio generation, diffusion autoencoding, upsampling, and vocoding. The models are waveform-based, and the U-Net, DiffusionModel, diffusion method, and samplers are customizable for other formats. No pre-trained models are provided.
AssemblyAI provides voice AI infrastructure, including pre-recorded, realtime and synchronous speech-to-text APIs, a voice agent API, speech understanding features and guardrails. Features such as speaker diarization, summarization, sentiment analysis and PII redaction run on the same transcription request.