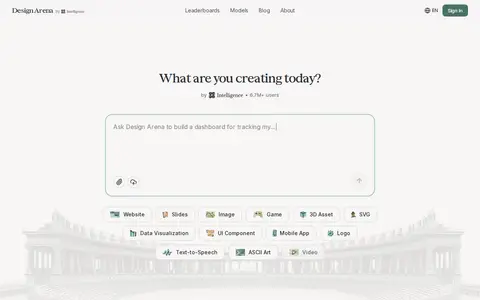
Design Arena is a global crowdsourced benchmark for AI-generated design. It allows users to challenge, vote on, and crown winning design outputs, access category-specific leaderboards for assets including websites, slides, images, video, audio, and code, and use top AI models to generate a wide range of design and development assets. Millions of users across over 190 countries use the platform to discover and compare AI model capabilities.
Directory
Search results
Published directory entries matching your search.
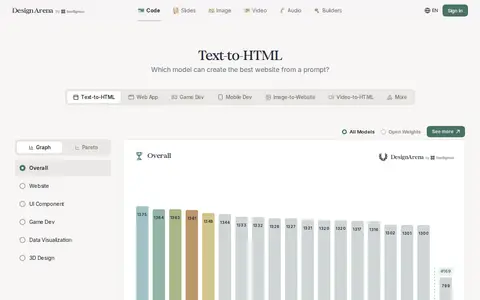
DesignArena is a crowdsourced benchmark platform for AI-generated design, described as the world's fastest-growing of its kind. It hosts leaderboards for AI design tasks including website, UI component, data visualization, 3D asset, image, logo, slides, video, and audio generation, as well as comparisons of model performance by preference versus speed and preference versus price. It also offers tools to build AI-powered design projects.
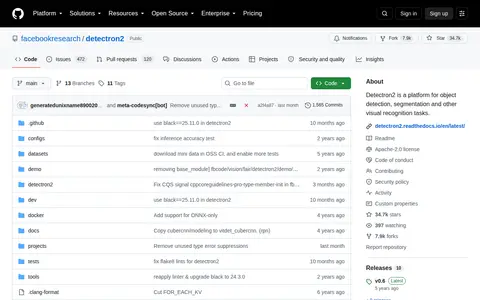
Detectron2 is Facebook AI Research's next generation library providing detection and segmentation algorithms, succeeding Detectron and maskrcnn-benchmark. It supports computer vision research projects and production applications at Facebook and includes capabilities such as panoptic segmentation, Densepose, Cascade R-CNN, rotated bounding boxes, PointRend, DeepLab, ViTDet and MViTv2. Models can be exported to TorchScript or Caffe2 format for deployment.
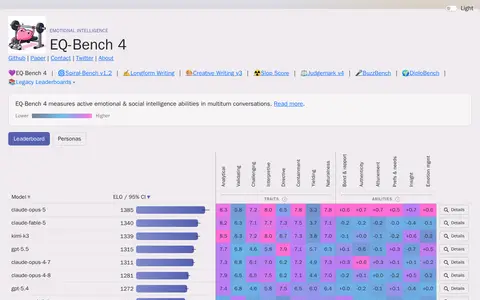
EQ-Bench 4 is a benchmark that measures active emotional and social intelligence abilities in multiturn conversations. It uses 120 personas with assigned traits, including adversarial ones, in roleplay chats played by Gemini 3.1 Pro Preview. Transcripts are assessed by three judges to produce a ranked Elo score.
EQ-Bench 3 is a multi-turn emotional intelligence benchmark for language models. It presents role-play scenarios and analysis tasks requiring empathy, insight and social skill, and an auxiliary judge model scores or pairwise-compares the outputs. An MIT-licensed repository with a readme, results and data folders, it includes rubric scoring and pairwise ELO analysis options.
Feature Stores for ML is a global community of data science professionals, researchers, and engineers focused on feature stores for machine learning pipelines. It creates educational content about feature stores and the surrounding data and AI ecosystem, hosts monthly industry meetups, and provides resources including blog posts, videos, benchmarks, and an MLOps dictionary.
This is a Kaggle page for a Google prompt engineering whitepaper. It invites users to join a community of builders, researchers and labs evaluating AI agents, models and frontier technology through crowdsourced benchmarks, competitions and hackathons.
BIG-bench is a collaborative benchmark intended to probe large language models and extrapolate their future capabilities. It includes more than 200 tasks, summarized by keyword and task name. The repository was archived by its owner and is now read-only.
Gym4ReaL is an open-source GitHub repository maintained by Daveonwave. It is a Gymnasium-based benchmarking suite for testing reinforcement learning algorithms on real-world scenarios. The repository includes documentation on supported characteristics, reinforcement learning paradigms, folder structure, contribution guidelines, and licensing terms.
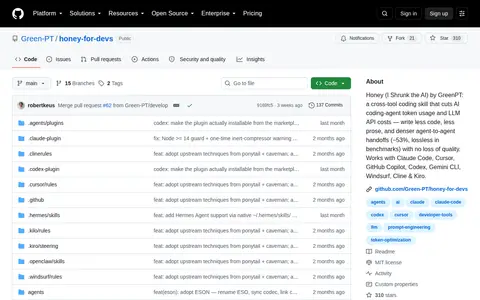
Honey (I Shrunk the AI) by GreenPT is a cross-tool coding skill that reduces AI coding-agent token usage and LLM API costs. It enables writing less code and prose and supports denser agent-to-agent handoffs, with reported 53% cost reduction and no quality loss in benchmarks. It is compatible with Claude Code, Cursor, GitHub Copilot, Codex, Gemini CLI, Windsurf, Cline, and Kiro.
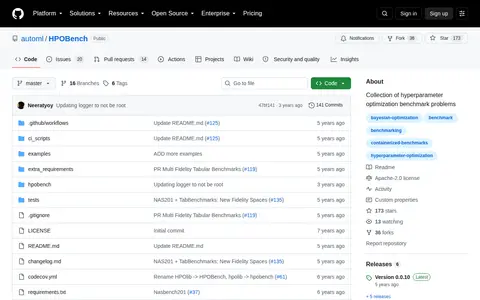
Library for hyperparameter optimization and black box optimization benchmarks.
Imagen is a text-to-image diffusion model from Google Research's Brain Team that creates photorealistic images from input text. It builds on large transformer language models for text understanding and cascaded diffusion models for image generation. The project also introduced DrawBench, a benchmark for comparing text-to-image models.
The Indico LLM Leaderboard provides benchmarking for large language models on extractive, classification, and predictive tasks. It includes accuracy comparisons, cost of ownership assessments, and datasets such as CORD and Kleister NDA, with the latest update in August 2024.
Edit /src/streamlit app.py to customize this app to your heart's desire.:heart:.
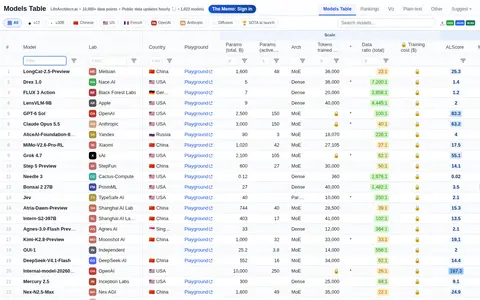
LifeArchitect.ai hosts a Models Table of large language model data, including parameters, tokens trained, and benchmark scores such as MMLU, MMLU-Pro, GPQA and HLE. The page also presents rankings, a data dictionary and visualization snapshots of frontier models.
Linear Digressions is a podcast series covering machine learning and AI topics, with episodes such as "LLM as a Judge," a cross-post on AI and podcasting from the Harvard Data Science Review, and a benchmark installment on ExploitGym. One episode examines mechanistic interpretability, described as an approach that opens the model itself to trace why it behaves as it does.
A Challenging, Contamination-Free LLM Benchmark.
LLM Explorer is a directory of open-source language models and AI agents. It lists 150 AI agents and 64,811 open-source large and small language models, grouped into categories with benchmarks and analytics.
LLM Stats is an AI leaderboard that ranks GPT, Claude, Gemini, Llama, DeepSeek and more than 300 AI models by intelligence, speed and price. Scores are computed from public benchmarks and live API metrics.
LM Council presents source-dated benchmark snapshots for AI models. It covers GPT, Claude, Gemini and other frontier models across benchmarks including Humanity's Last Exam, FrontierMath, GPQA and SWE-bench, with a comparison tool selecting two models. Each snapshot links its source and checked date, and evaluation settings and metrics vary.
Local Deep Research is a tool that achieves approximately 95% accuracy on the SimpleQA benchmark, with an example run using Qwen3.6-27B on an RTX 3090. It supports all local and cloud LLMs including llama.cpp, Ollama, and Google models, integrates over 10 search engines such as arXiv, PubMed, and private document sources, and operates with local and encrypted processing.
MathArena evaluates large language models on uncontaminated math benchmarks. It presents model analysis across competitions such as ArXivLean, BrokenArXiv, ArXivMath, Visual Math, Final-Answer Comps, Proof-Based Comps and Project Euler. A competition is selected to load tables and a leaderboard, and clicking a cell shows the raw model output.
An open source robotics benchmark for meta- and multi-task reinforcement learning.
Moonshot AI is a GitHub organization focused on AI and machine learning research and development. As of the listing snapshot, it hosts 42 public repositories, with areas of work including research, benchmarks, agents, service infrastructure, and community engagement, and its code is available on GitHub.