LLMLingua is a Microsoft-developed series of prompt compression tools for large language models, designed to accelerate LLM inference by shortening input prompts. The series includes LLMLingua, LongLLMLingua, LLMLingua-2, and SeCom, each using distinct compression techniques. It supports use cases such as retrieval-augmented generation and online meeting processing, and is integrated with the LangChain and LlamaIndex frameworks.
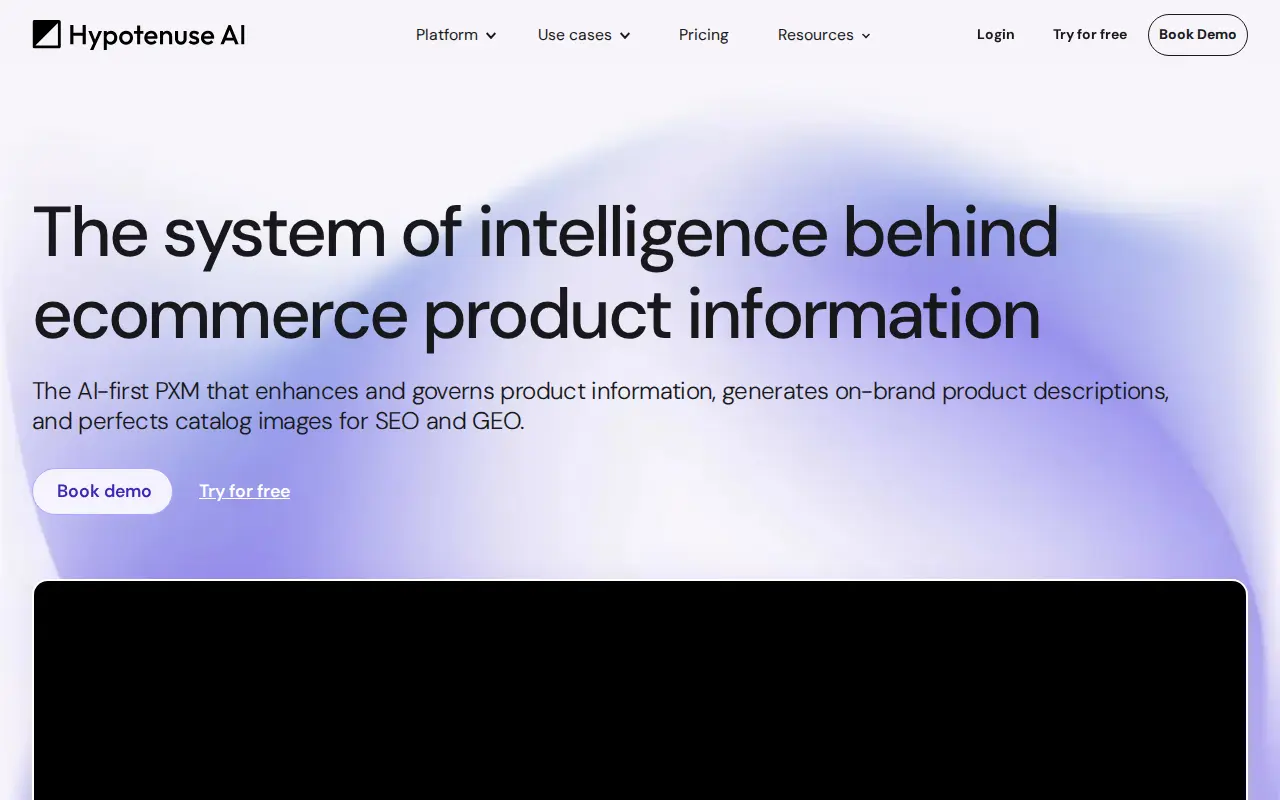
Hypotenuse AI
Hypotenuse AI is an AI-first Product Experience Management platform for ecommerce that enriches and governs product information, generates on-brand content, and perfects catalog images. It offers AI auto-enrichment of product attributes, bulk generation of product descriptions, and AI enhancement of catalog images. It also provides AI agents for product content tasks and an AI product attribute mapping tool.
Links
Tags
-
0
LLMLingua is a Microsoft-developed series of prompt compression tools for large language models, designed to accelerate LLM inference by shortening input prompts. The series includes LLMLingua, LongLLMLingua, LLMLingua-2, and SeCom, each using distinct compression techniques. It supports use cases such as retrieval-augmented generation and online meeting processing, and is integrated with the LangChain and LlamaIndex frameworks.
-
0
Deep Else is a paper presenting a critical framework for exploring AI art, covering its context, poetic features, issues and possible directions. It examines the poetic, expressive and ethical layers of AI art practices within contemporary art, AI research and related disciplines.
-
0DaFreeAi is a platform for creating images and videos with a choice of AI models, listing over 70 models. It offers a Free Plan and paid membership tiers with monthly credit allowances and parallel generations. Payment and account notices appear on its plans page alongside credit package options.
-
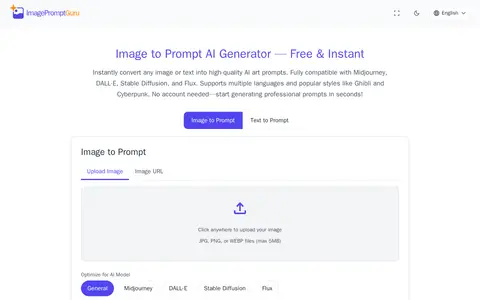
0ImagePromptGuru is a free web tool that converts images or text into prompts for AI art generators. It states compatibility with Midjourney, DALL-E, Stable Diffusion and Flux, supports 18 output languages, and offers scene and style options. No account is required, and uploaded images are said to be processed and discarded without storage.
-
0Creates or edits images with generative models and visual controls.
-
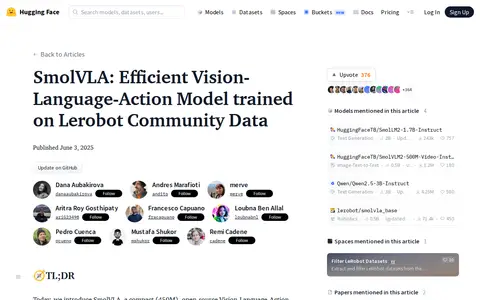
0SmolVLA is a compact 450M open-source Vision-Language-Action model for robotics that runs on consumer hardware. It is pretrained on compatibly licensed, open-source community-shared datasets under the lerobot tag and supports asynchronous inference.
Community notes
Reviews and discussion
No reviews yet
Be the first to share how this project worked for you.
Join the discussion
Sign in with a verified account to leave a review or join the discussion.
Sign in to review