
playground.microsoft.ai
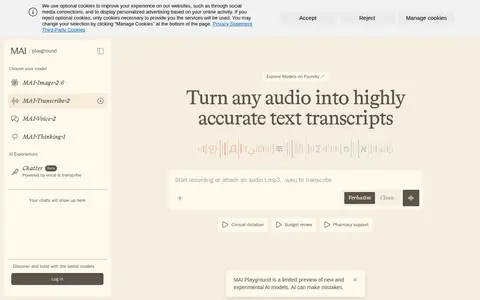
MAI Playground is a Microsoft AI playground for running and experimenting with new AI models. It also offers transcription that turns audio into highly accurate text transcripts, with verbatim and clean output options.