Directory

Search results

Published directory entries matching your search.

Search results

14 listings

A GitHub repository listing packages, services and manuals related to web scraping. It covers libraries for Python, PHP, Ruby, JavaScript and Go, command line tools, and web-scraping manuals. It also lists headless browsers, DNS over HTTPS providers, pastebin sites, tunneling software and captcha solving services.
Internet Utilities 0
github.com

Dev Scraping APIs is a GitHub repository or organization with source code, releases, documentation, or project resources.

APIs & Databases 0
github.com

Proxy service that helps scraping tools handle Cloudflare and browser-based anti-bot challenges.

Internet Utilities 0
github.com

brozzler is an open source project with code, documentation, and setup resources for web archiving and scraping.

Internet Utilities 0

datahoarder-website-to-markdown is an open source project with code, documentation, and setup resources for web archiving and scraping.

Web Archives 0
github.com

DownloadNet (dn) is an open source project with code, documentation, and setup resources for web archiving and scraping.

Web Archives 0
github.com

Httrack is an open source project with code, documentation, and setup resources for web archiving and scraping.

Web Archives 0
github.com

MarkSnip is an open source project with code, documentation, and setup resources for web archiving and scraping.

Web Archives 0

Resurrect Pages Fork is an open source project with code, documentation, and setup resources for web archiving and scraping.

Web Archives 0
github.com

Scoop is an open source project with code, documentation, and setup resources for web archiving and scraping.

Web Archives 0
github.com

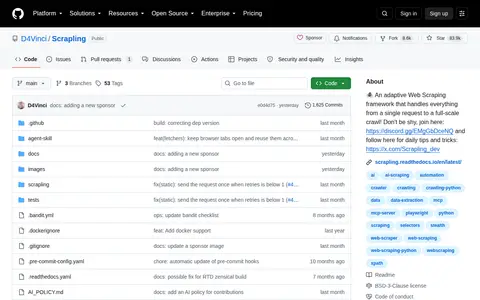
Scrapling is an adaptive web scraping framework that supports tasks ranging from a single request to full-scale crawling. The project offers community channels on Discord and Twitter for tips and support.

Internet Utilities 0
github.com

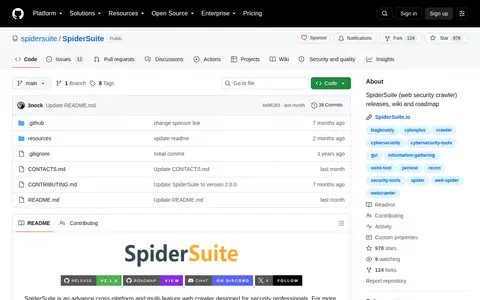
Spider Suite is an open source web scraping or crawling project for collecting website data.

Internet Utilities 0
github.com

SuckIT is an open source project with code, documentation, and setup resources for web archiving and scraping.

Web Archives 0
github.com

Trawl is a self-hosted scraping engine designed to bypass JavaScript challenges and CAPTCHAs including Cloudflare, Turnstile, reCAPTCHA, hCaptcha and GeeTest. It is positioned as an alternative to FlareSolverr and Byparr, and can serve as a drop-in replacement for *arr stack applications.

Internet Utilities 0