github.com
Awesome Web Archiving is a code repository or project page with source code, releases, documentation, or setup notes.
Directory
Published directory entries matching your search.
Awesome Web Archiving is a code repository or project page with source code, releases, documentation, or setup notes.
brozzler is an open source project with code, documentation, and setup resources for web archiving and scraping.
datahoarder-website-to-markdown is an open source project with code, documentation, and setup resources for web archiving and scraping.
DownloadNet (dn) is an open source project with code, documentation, and setup resources for web archiving and scraping.
Twitch VOD and Live Stream archiving platform. Includes a rendered and real-time chat for each archive.
Heritrix3 is an open source project with code, documentation, and setup resources for web archiving and scraping.
Httrack is an open source project with code, documentation, and setup resources for web archiving and scraping.
Self-hosted bookmark manager for saving links, archiving pages, and organizing web resources.
MarkSnip is an open source project with code, documentation, and setup resources for web archiving and scraping.
Resurrect Pages Fork is an open source project with code, documentation, and setup resources for web archiving and scraping.
Scoop is an open source project with code, documentation, and setup resources for web archiving and scraping.
wayback machine spn scripts is an open source project for saving, replaying, or working with archived web pages.
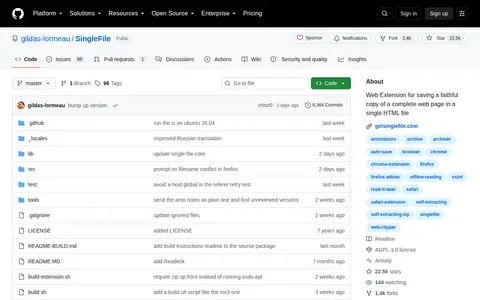
Browser extension and tool for saving complete web pages into a single HTML file.
SuckIT is an open source project with code, documentation, and setup resources for web archiving and scraping.
Trawl is an open source project with code, documentation, and setup resources for web archiving and scraping.
An archiving tool with an IM-style interface that prioritizes privacy and accessibility, integrated with various archival services including Internet Archive, archive.today, Ghostarchive, IPFS, Telegraph, and file systems.
Waymore is an open source project with code, documentation, and setup resources for web archiving and scraping.