github.com
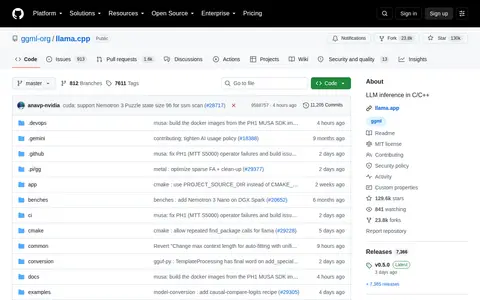
llama.cpp is a C/C++ implementation for large language model and vision language model inference with minimal setup across a range of hardware, locally and in the cloud. It is built on the ggml library and offers command-line and server tools, an OpenAI-compatible API server, and multiple hardware backends.