humanbenchmark.com
Human Benchmark is a miscellaneous web resource for discovery, directories, archives, web culture, or useful tools.
Directory
Published directory entries matching your search.
Human Benchmark is a miscellaneous web resource for discovery, directories, archives, web culture, or useful tools.
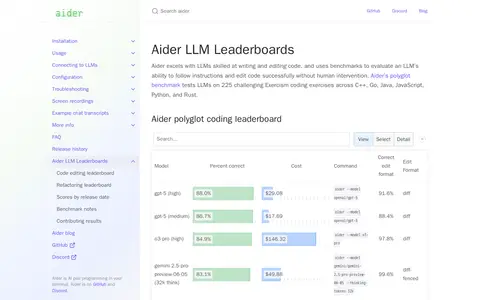
Aider LLM Leaderboards presents quantitative benchmarks of LLM code editing skill. The polyglot benchmark tests LLMs on 225 Exercism coding exercises in C++, Go, Java, JavaScript, Python and Rust, and benchmarks evaluate an LLM's ability to follow instructions and edit code without human intervention.
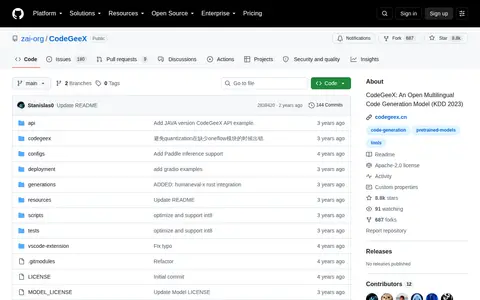
CodeGeeX is an open multilingual code generation model with 13 billion parameters, pre-trained on a code corpus of more than 20 programming languages. It supports multilingual code generation, crosslingual code translation and a VS Code extension, and the repository also releases the HumanEval-X benchmark.
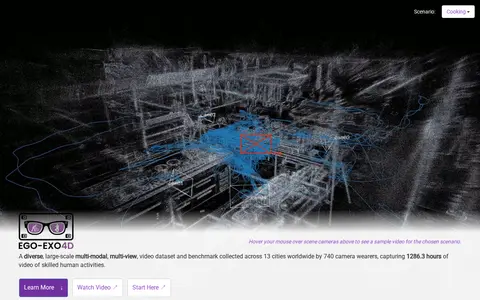
Ego-Exo4D is a large-scale multi-modal, multi-view video dataset and benchmark of simultaneously captured ego-centric and exo-centric video of skilled human activities such as sports, music, dance, and bike repair. It includes natural language datasets, multi-view capture with Aria glasses and GoPros, and benchmarks including Keystep Recognition and Proficiency Estimation.
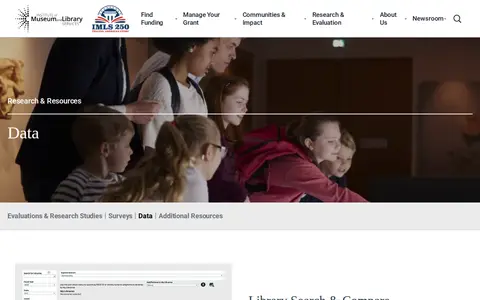
The Institute of Museum and Library Services provides a data page with tools and reports for exploring library and museum data. It includes Library Search & Compare for individual library data and ten-year trends, an indicators workbook on economic status and broadband, a state funding report compilation, a state comparison tool, public library benchmarking tables, and administrative discretionary grant data.
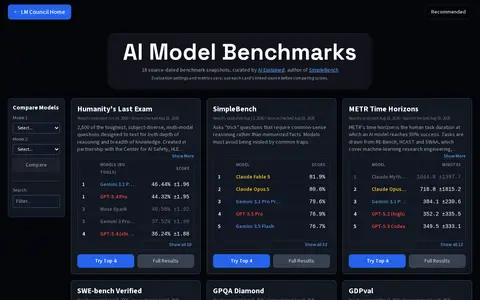
LM Council presents source-dated benchmark snapshots for AI models. It covers GPT, Claude, Gemini and other frontier models across benchmarks including Humanity's Last Exam, FrontierMath, GPQA and SWE-bench, with a comparison tool selecting two models. Each snapshot links its source and checked date, and evaluation settings and metrics vary.

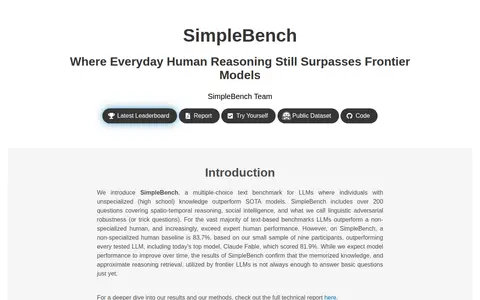
SimpleBench is a multiple-choice text benchmark for LLMs with over 200 questions covering spatio-temporal reasoning, social intelligence and trick questions. Its report states a non-specialized human baseline of 83.7 percent from a small sample of nine participants.
WizardLM is a repository of large language models including WizardLM, WizardCoder and WizardMath, described as LLMs built upon Evol Instruct. The page lists model checkpoints and benchmark results, with WizardCoder-33B-V1.1 reported at 79.9 pass@1 on HumanEval and WizardMath-7B-V1.1 reported at 83.2 pass@1 on GSM8k.