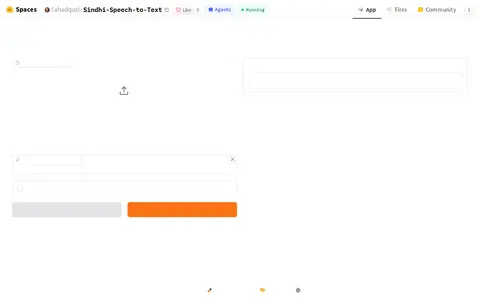
Sindhi Speech To Text is a Hugging Face Space that converts spoken Sindhi language into written text. Users can upload an audio or video file or record directly from their microphone. The application also offers an option to remove background music.
Directory
Search results
Published directory entries matching your search.
This premium domain name is available for purchase!
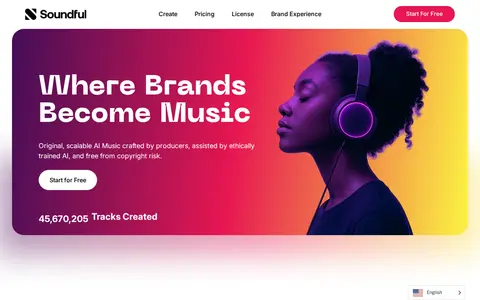
Soundful is an AI music platform for generating royalty-free tracks and loops. Users select a genre and template, with a human-aided AI producing unique tracks. Plans include Free, Plus, Pro, Business and Enterprise, with track downloads varying by plan.
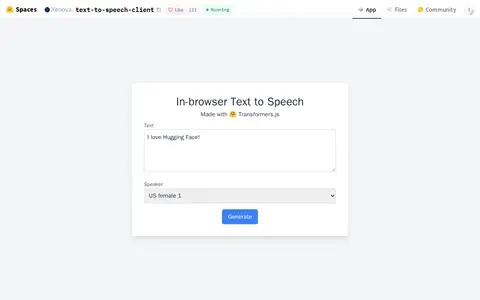
This Hugging Face Space by Xenova is a web application that converts user-entered text to spoken audio. Users can type or paste text into the app, which generates clear audio playback of the content without requiring file uploads.
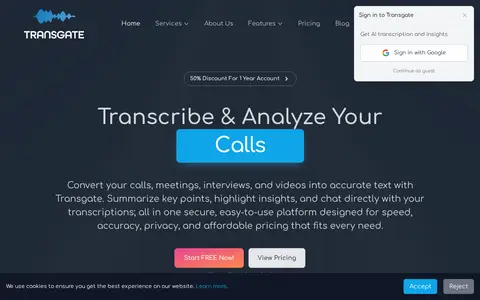
Transgate is an AI transcription and translation service for audio and video. It offers two services: transcribe or translate in 50+ languages, with summaries, highlights and the ability to chat with transcripts. Files are uploaded, processed by AI, and results can be exported. It uses a pay-as-you-go model.
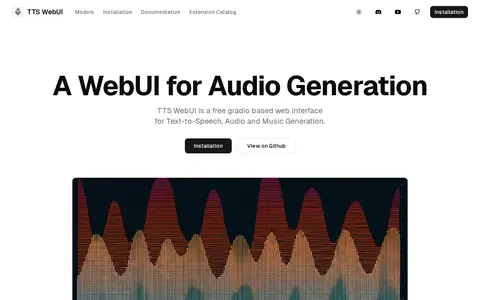
TTS WebUI is a free Gradio-based web interface for text-to-speech, audio and music generation. It can generate audio from text using over 30 AI models, including Bark, MusicGen, Tortoise and Vocos, and offers voices from the Bark Speaker Directory. Installation is available through one-click installers or manual setup.
Tunisian Speech Recognition is a Hugging Face Space created by SalahZa. The application transcribes spoken Tunisian Arabic into text using Arabic characters. Users can provide input audio either by recording through a microphone or uploading an audio file, and the tool returns the corresponding text transcription.
Accelerates transcription with the combination of OpenAI's Whisper Large v2, HF Transformers, Optimum, and flash attention.
Space emoji (emoji-only character allowed).
Veed.io is an AI video creation platform that offers an end-to-end idea-to-video workflow. It provides tools for generating talking heads, AI-powered video editing, dubbing, subtitle addition, AI voice and image generation, and pre-built ad and video templates, targeted at marketers and solopreneurs.
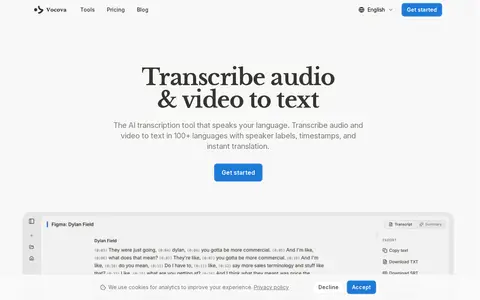
Vocova is an AI tool that transcribes audio and video to text in 100+ languages, with speaker labels, timestamps and translation. It imports from YouTube, Google Drive, Dropbox and other platforms, and exports transcripts as PDF, DOCX, SRT and more.
Voicery is a company that creates natural-sounding text-to-speech engines and custom brand voices for enterprise clients. Its solutions leverage deep-learning research optimized for specific business use cases and technical infrastructure.
Voicesphere is an AI document interaction tool that allows users to upload documents including PDFs, DOCs, PPTs, videos, texts, and CSVs to ask natural language questions and receive context-specific answers. It includes a secure document management system, and is designed for use by manufacturing companies, medical professionals, law firms, researchers, recruitment agencies, and customer service teams.
Vosk is an offline speech recognition API hosted in the alphacep/vosk-api GitHub repository. It is compatible with Android, iOS, Raspberry Pi, and server environments, and provides SDKs for Python, Java, C#, and Node.
A simple and efficient end-to-end Automatic Speech Recognition (ASR) system from Facebook AI Research.
USE BAZEL VERSION=5.0.0./bazelisk-linux-amd64 build wavegru mod -c opt --copt=-march=native.
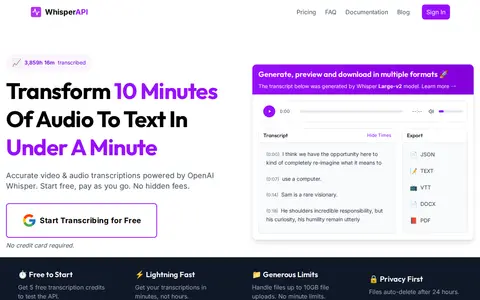
A transcription API built on OpenAI Whisper that converts audio and video files to text. It supports file uploads and remote URLs, multiple output formats, and model size selection for speed versus accuracy. A no-code dashboard offers drag-and-drop transcription. Pricing is pay-as-you-go with credit bundles, and files auto-delete after 24 hours.
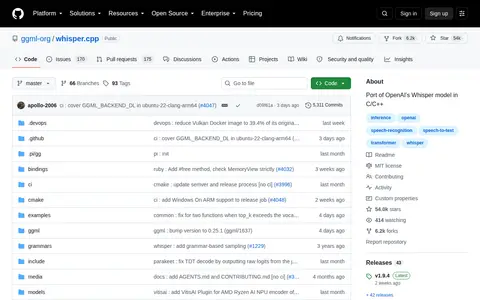
A C/C++ port of OpenAI's Whisper automatic speech recognition model, providing high-performance inference without dependencies. It supports CPU-only inference and GPU backends, and runs on platforms including macOS, iOS, Android, Linux, Windows, WebAssembly and Raspberry Pi. The whisper-cli example currently runs only with 16-bit WAV files.
YobiYoba is a speech recognition service that transcribes audio and video recordings into editable, time-coded text. Users upload files, specify or auto-detect the language, verify and edit transcripts, then download them in formats such as SRT, PDF, or VTT. Processing produces speaker labels, time codes, and confidence scores. Pricing is pay-as-you-go, from 0.01 € per minute of speech.
Aider is an AI pair programming tool that runs in the terminal and works with cloud and local LLMs. It maps the codebase, supports more than 100 code languages, and integrates with Git to automatically commit changes. It can also run in an IDE and accept voice-to-code instructions.
Anyword is a generative AI content platform and performance API for go-to-market teams. It adds A/B-tested data and brand context to prompts and works with any AI model or application. The platform includes a data-driven editor, content intelligence, brand voice features, and integrations with marketing channels such as Google Ads, Meta, and LinkedIn.
Audify AI is a text-to-speech converter that turns written text into speech using AI models from OpenAI. Users can select voices, adjust speaking speed, and download audio in formats such as MP3, WAV, FLAC and OPUS. The site lists voiceovers, podcasts, audiobooks, accessibility and education among use cases.
Compose AI is an AI-powered writing tool that generates text and autocompletes sentences where the user types, for emails, documents, and chat. It offers autocomplete across tools and learns the user's writing voice to suggest personalized phrases. The core plugin is described as free to use, with a premium version carrying advanced and personalization features.
MMAudio is a Hugging Face Space that generates synchronized audio from video or text. Users can upload a short video and write a prompt, including a negative prompt, to add realistic sound, or create a standalone audio clip from a text description.