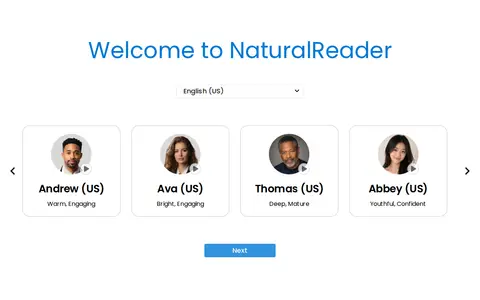
openai.fm
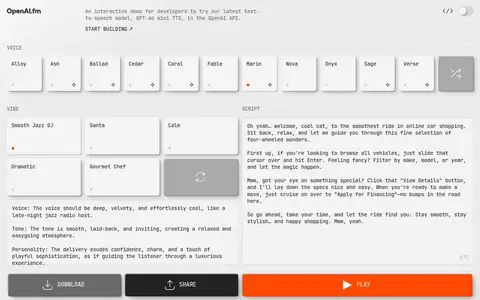
OpenAI.fm uses AI for speech, voice, transcription, music, or other audio workflows.
Directory
Published directory entries matching your search.
OpenAI.fm uses AI for speech, voice, transcription, music, or other audio workflows.
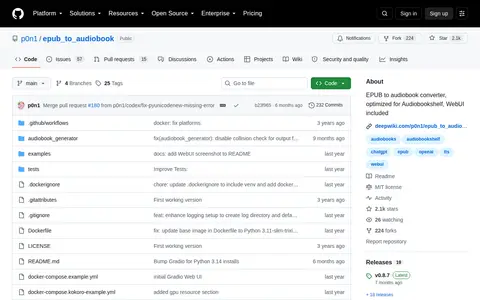
EPUB to audiobook converter, optimized for Audiobookshelf.

Pack Generator uses AI for speech, voice, transcription, music, or other audio workflows.
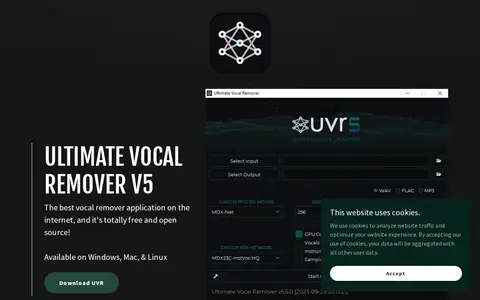
Remove Vocals uses AI for speech, voice, transcription, music, or other audio workflows.
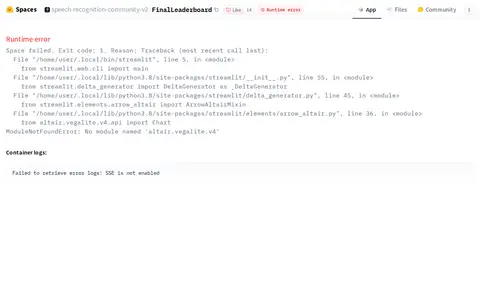
Robust Speech Recognition Leaderboard 2022 uses AI for speech, voice, transcription, music, or other audio workflows.

SoundofText uses AI for speech, voice, transcription, music, or other audio workflows.
A Hugging Face Space that accepts uploaded or recorded audio and returns a text transcription with grammar correction. The page reports a runtime error because none of PyTorch, TensorFlow >= 2.0, or Flax were found, so models are unavailable.
Splitter uses AI for speech, voice, transcription, music, or other audio workflows.
Suno is an AI music generator that creates original music from user prompts. It offers a browser-based digital audio workstation for editing and mixing tracks, voice cloning to make any voice sing user-written content, stem separation to split songs into individual components, and remix functionality.
text to speech online is a free text-to-speech tool that uses Gemini and ChatGPT AI voices to convert text into ultra-realistic audio. It can read aloud content from PDFs, books, documents, and webpages. The page includes a note that users should refresh if they are not redirected shortly.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
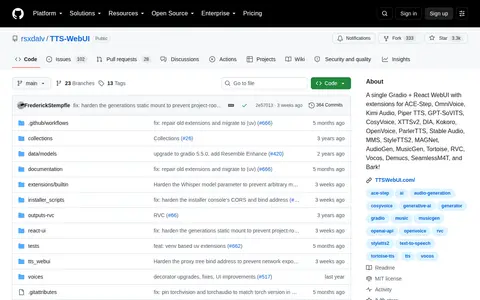
Tts Web UI is a single web interface built with Gradio and React that supports extensions for a wide range of audio and text-to-speech related models and tools, including ACE-Step, OmniVoice, Piper TTS, GPT-SoVITS, and others.
Vocal Remover uses AI for speech, voice, transcription, music, or other audio workflows.
VanillaVoice is a free online text to speech tool that reads text aloud with human-sounding voices. Users can pick male, female or child voices in many languages, adjust volume and speed, and download audio as an MP3 without installing software. A Professional Plan offers a commercial license, speech-enabled products and up to 500 words per recording.
Vocali.se is a free web service that separates vocals and music from songs or audio files, allowing users to create karaoke versions. It runs a machine learning engine using pre-trained Demucs models and requires no software installation or account registration. Processing takes less than three minutes, after which the separated files download automatically.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
WolframTones uses AI for speech, voice, transcription, music, or other audio workflows.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
Zyphra uses AI for speech, voice, transcription, music, or other audio workflows.

Accord.NET is a .NET machine learning framework combined with audio and image processing libraries written in C#. It covers classification, regression, clustering, distributions, hypothesis tests and kernel methods, with imaging and signal processing components. The framework is intended for building computer vision, audition, signal processing and statistics applications, including commercial use. It offers sample applications, documentation and a wiki.
AI/ML API provides access to over 1000 AI models through a single API for text, image, video, audio, code and embeddings, with pricing, latency and capability comparison in one place. It also offers an MCP server for connecting clients such as Claude, Cursor and Claude Code.
All Voice Lab offers AI voice cloning, text-to-speech and a real-time voice changer for creators, aimed at video dubbing and podcasts. Its text-to-speech is described as adapting tone, rhythm and pitch to text sentiment, and the site states the AI integrates 33 major languages. A proprietary voice model named MaskGCT is also presented, alongside API and MCP access.