Directory

Search results

Published directory entries matching your search.

Search results

190 listings

A blog article about red-teaming large language models, described as a form of evaluation that elicits model vulnerabilities that might lead to undesirable behaviors. It discusses undesirable behaviors such as revealing personal information, misinformation, bias, hatefulness and toxic content, and compares red-teaming with adversarial attacks. It notes that red-teaming prompts look like regular natural language prompts.
Models & Machine Learning 0
redalyc.org

Redalyc is a scientific information system and network of scientific journals. It describes an open access, non-profit model owned by the academy, and lists journals across social sciences, natural and exact sciences, and arts and humanities. Its interface is available in Spanish, English, Portuguese and other languages.

Academic & Research Search 0
refractiveindex.info

RefractiveIndex.INFO is a refractive index database. It presents optical constants for materials such as silicon dioxide, including complex refractive index data and dispersion formulas over stated wavelength ranges. Records list conditions, comments and references, with data offered as CSV, TXT and full database records.

Dataset & Data Search 0

Digital repository of the Jan Kochanowski University holding 269 digital objects across collections covering research data, humanities, medical and health sciences, social sciences, science and natural sciences, and art sciences. It offers advanced search and recently added and most viewed object listings.

Dataset & Data Search 0
rifj.ifj.edu.pl

The Repository of the Institute of Nuclear Physics of the Polish Academy of Sciences (IFJ PAN) collects, stores, and shares research documents produced by the institute's staff and doctoral students. Its purpose is to disseminate scientific achievements and promote the institute's research. The repository provides open access to bibliographic descriptions and full texts. It organizes content into communities and collections.
Dataset & Data Search 0
search.com

Search.com operates SearchGPT Plus, a free ChatGPT alternative for writing, learning and productivity. It offers GPT search with instant results, plus a voice mode that replicates natural conversational tone and pace. Free guest usage is subject to message limits, requiring account creation to continue, and chat content may be retained for up to 7 days for security purposes.

Search Engines & Tools 0
kriztalz.sh

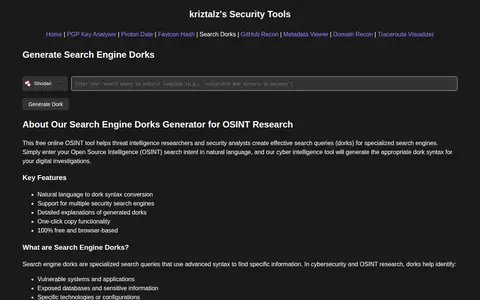
SearchDorks is a free, browser-based OSINT tool that converts natural language search intent into dork syntax for Shodan, Censys, Google, FOFA and ZoomEye. It is aimed at threat intelligence researchers and security analysts, offers explanations of generated dorks and one-click copying, and does not store queries.

Google Communities & Tools 0
searchthearxiv.com

Searchthearxiv is a simple semantic search engine for machine learning papers on arXiv. Users can input arXiv links to find similar papers or use natural language queries to search for relevant research.

Academic Papers & Research 0
seed.bytedance.com

Seedance 1.0 is a model that supports multi-shot video generation from text and images. It can create 1080p videos and parses natural language prompts for control over interactions, action sequences and camera movements.

AI Video Generation 0
semantic-ui.com

Semantic UI is a development framework for creating responsive layouts using human-friendly HTML. It treats words and classes as exchangeable concepts, using syntax from natural languages. It uses simple phrases called behaviors to trigger component functionality, and includes an intuitive inheritance system with high level theming variables. The project is described as free and open source.

Web Development 0
github.com

Natural Language Understanding library for intent classification and entity extraction.

Models & Machine Learning 0
sourcelibrary.org

Source Library is a digital collection of ancient texts translated into English, described as a library of AI-translated ancient sources. It offers curated exhibitions and browsing by subject, covering areas such as sacred texts, classical philosophy, astrology and divination, and natural philosophy and science. The site is labelled Beta and lists books, English-readable titles and translations.

Academic & Research Search 0
spacy.io

spaCy is a free open-source library for Natural Language Processing in Python. It features named entity recognition, part-of-speech tagging, dependency parsing and word vectors, supports over 75 languages and provides 84 trained pipelines for 25 languages.

Models & Machine Learning 0
speechify.com

Speechify is a text to speech and voice typing assistant that reads books, PDFs, documents and web pages aloud with natural-sounding voices. It offers text highlighting, speed control and scan and listen, and is available as browser extensions, desktop apps for Windows and Mac, and mobile apps for iOS and Android.

AI Audio & Speech 0
spellapp.com

Spell is an AI document generator and collaborative document editor. Users describe a document in natural language, and Spell produces a first draft that can be refined through the editor and shared for real-time team collaboration.

AI Business & Productivity 0
studyforrest.org

StudyForrest is a dataset collection built around the movie Forrest Gump, providing reproducible complex sensory input for brain research. It includes fMRI scans, structural brain scans, eye-tracking data and extensive annotations of the movie. The project offers reference datasets for benchmarking brain imaging algorithms and for studying cognition under natural stimulation.

Dataset & Data Search 0
github.com

tensorpack is an open-source neural network training interface built on TensorFlow with a focus on training speed and flexibility. Hosted on GitHub, the project provides feature documentation and example materials covering use cases including computer vision, reinforcement learning, and speech or natural language processing.

Models & Machine Learning 0

Text To Sql Example Explanation is a Hugging Face Space created by user suriya7. It accepts natural language queries and table details as input, and outputs a corresponding SQL query, sample query results, and an explanation of the generated query.

AI Data & Analytics 0
huggingface.co

This Hugging Face Space generates SQL queries from natural language for datasets on Hugging Face; users enter a dataset and a query. The Space is currently paused, and the author can be asked to restart it.

AI Data & Analytics 0
github.com

textacy is a Python library for natural language processing tasks built on the spaCy library. It focuses on tasks before and after spaCy processing, with tokenization, part-of-speech tagging and dependency parsing delegated to that library. Features include cleaning and normalizing raw text, extracting n-grams, entities, acronyms and keyterms, similarity metrics, and training topic models.

Models & Machine Learning 0
textblob.readthedocs.io

TextBlob is a Python library for processing textual data. It offers a simple API for natural language processing tasks including part-of-speech tagging, noun phrase extraction, sentiment analysis, classification, and tokenization. The documentation lists features such as word and phrase frequencies, parsing n-grams, lemmatization, spelling correction, and WordNet integration. It builds on NLTK and pattern, and new models or languages can be added through extensions.

Models & Machine Learning 0
github.com

TextCL is a text preprocessing package intended for cleaning text data before use in natural language processing tasks. It can be an initial step in text analysis and in predictive, classification, or text generation models. Documented preprocessing tasks include splitting texts into sentences, filtering by language, perplexity filtering, duplicate sentence filtering using Jaccard similarity, and unsupervised outlier detection with methods such as TONMF, RPCA, and SVD.

Models & Machine Learning 0
textrazor.com

TextRazor is a natural language processing API that extracts meaning from text. It performs entity extraction, disambiguation and linking, keyphrase extraction, and automatic topic tagging and classification across 19 languages. It classifies content to the IAB Content and IPTC Media Topic taxonomies and analyzes relations and typed dependencies. Official client SDKs exist in Python, Java and PHP, with a REST API for other languages.

Models & Machine Learning 0

The USA National Phenology Network is a national-scale monitoring and research initiative. It collects, organizes and delivers phenological data, information, and forecasts to support natural resource management and decision-making, to advance the scientific field of phenology, and to promote understanding of phenology by a wide range of audiences.

Dataset & Data Search 0