huggingface.co
📦 Open-Source Models (via Nebius).
Directory
Published directory entries matching your search.
📦 Open-Source Models (via Nebius).
Moe TTS is a Hugging Face Space created by skytnt that enables users to generate speech from input text and convert existing audio to a different speaker's voice. Users can input text to create speech output, select from available speakers, and adjust the playback speed of generated audio.
MTEB Leaderboard is a Hugging Face Space hosted by the mteb organization. It displays a leaderboard ranking the performance of embedding models across a wide range of tasks, including retrieval and language evaluation. Users can select specific tasks or categories to view detailed model scores and compare performance between different embedding models.
Multi Agent Chat supports AI agents, automated workflows, orchestration, or delegated tasks.
Define rules for communication and cooperation.
Uses AI agents to complete tasks, coordinate tools or automate multi-step workflows.
Creates or edits images with generative models and visual controls.
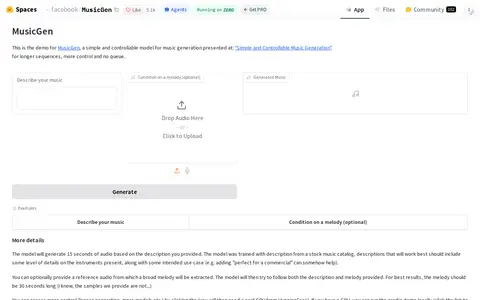
MusicGen is a Hugging Face Space by facebook that generates music audio from a text description. Users can optionally upload a short melody to guide it and set parameters such as length; the app then creates a music audio file.
Welcome to the NoCoMind - Dynamic & Customizable AI Agents – a no-code platform designed.
Creates or edits images with generative models and visual controls.
Creates or edits images with generative models and visual controls.
The Open VLM Leaderboard is an interactive Hugging Face Space that displays the Open VLM main leaderboard and individual dataset leaderboards. Users can filter results by evaluation dimensions, model size, model type and other related criteria.
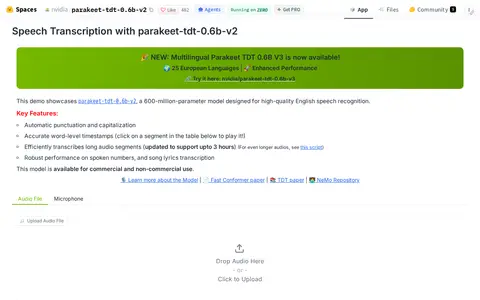
Parakeet-TDT-0.6b-V2 is a Hugging Face Space from nvidia that converts uploaded audio files or microphone recordings into written text, splitting the output into timestamped segments. Each segment can be viewed, played back, and downloaded.
Discover amazing ML apps made by the community.
Real-Time Latent Consistency Model Text to Image creates or edits images with generative AI and text-based controls.
Real-Time Latent Consistency Model Text-to-Image-Lora-SD1.5 creates or edits images with generative AI and text-based controls.
Creates or edits images with generative models and visual controls.
A Hugging Face Space that generates speech from entered text. Users choose a voice and an emotion style and can optionally set a seed. The app sends requests to the Pollinations service and returns an MP3 file with the synthesized speech.
This app will download Jio-Savan music.
Creates or edits images with generative models and visual controls.
Robust Speech Recognition Leaderboard 2022 uses AI for speech, voice, transcription, music, or other audio workflows.
Analyzes structured data and helps produce queries, insights or visualizations.
Explanation video is available here.
Creates, edits or enhances video and animation with generative models.