searchatlas.org
Search map and directory for exploring search engines, categories, and discovery tools.
Directory
Published directory entries matching your search.
Search map and directory for exploring search engines, categories, and discovery tools.
Search by Image is a browser extension that enables reverse image searches across more than 30 supported search engines. It is available for Chrome, Edge, and Safari. The extension assists journalists and researchers with verifying image authenticity and identifying false information, helps photographers track how their work is shared online, and allows shoppers to find similar products at discounted prices.

Searchcraigslist.org is a third-party search tool for Craigslist. It enables users to search all Craigslist classified listings nationwide, rather than being limited to local area results. Users can enter keywords to find items or services, add terms to refine searches, or use minus signs to exclude specific terms from results. The site also hosts informational articles related to selling items on Craigslist, including guidance on creating effective ad images. It is not affiliated with Craigslist.

Directory of search engines and specialized search tools organized for quick discovery.

Search My Site is an independent search engine focused on personal websites, digital gardens and the small web. It also offers a website search tool that adds a search box to a site with one line of code. The platform is ad-free, privacy-first and open source, with a free Basic listing, a one-month free trial, and a Full listing priced at £12/year.
Search Site WE is a cross-browser extension compatible with Firefox and Chrome. It allows users to search within the current subdomain or the entire domain using a selected search engine, accessible via the toolbar button or context menu. It is a no-restart alternative to the established Search Site add-on, built with the WebExtensions API with identical functions and user interfaces across both supported browsers.

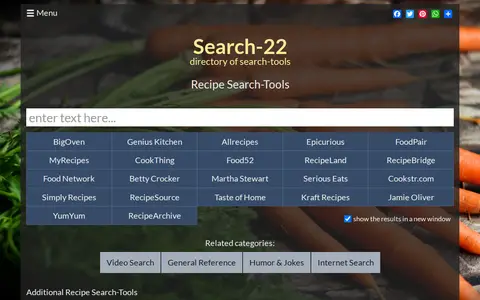
Search-22 hosts an all-in-one food recipes search page that links to recipe search engines, search-tools and cooking web sites. A partner links section and related search-tool categories are also listed.
Telegram link for search engines updates, bots, resources, or community discussion.
Search engine for finding public Telegram posts, channels, and discussions by keyword.

Search engine for finding Reddit posts, comments, and discussions across public communities.

SearchFiles.de is a file search engine that searches for content in files hosted on services including Mega, Mediafire, 4shared, and Easy-Share. It allows users to filter results by keyword location and date range, requires JavaScript to operate, and can be added to browser search bars.
Searchthearxiv is a simple semantic search engine for machine learning papers on arXiv. Users can input arXiv links to find similar papers or use natural language queries to search for relevant research.
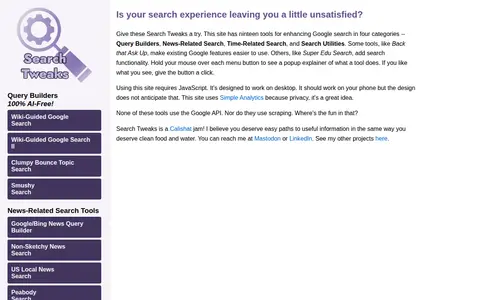
SearchTweaks is a website offering tools to improve web search experiences, specifically enhancing Google search functionality. Its tools are organized into four categories: Query Builders, News-Related Search, Time-Related Search and Search Utilities. Some tools simplify existing Google features, while others add new search capabilities. The site requires JavaScript to function, is designed for desktop use, and does not rely on the Google API or web scraping. It uses Simple Analytics for privacy-focused usage tracking.
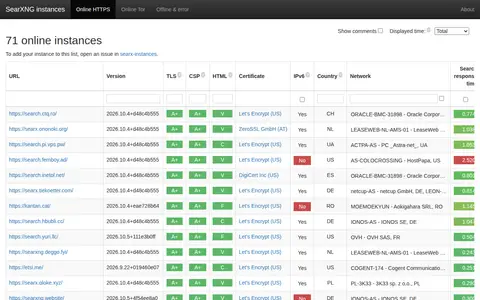
Open source metasearch engine that pulls results from multiple providers with privacy-focused options.

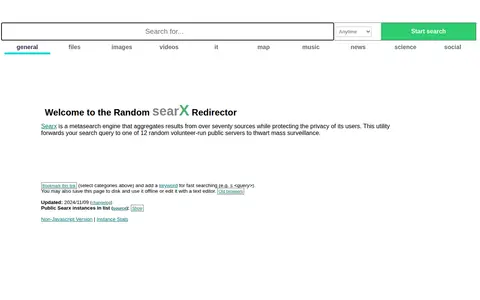
A redirector page that forwards a search query to one of several volunteer-run public Searx instances. Searx is described as a metasearch engine that aggregates results from over seventy sources while protecting user privacy. The page can be saved to disk for offline use or edited with a text editor.
Open source metasearch engine that aggregates results while respecting user privacy.
Seats.aero is described as a search engine for award travel. The listing says it allows users to explore flights and hotels across regions and search with instant results. It is based in San Francisco, CA, and its X account has 55 posts and 6,303 followers.
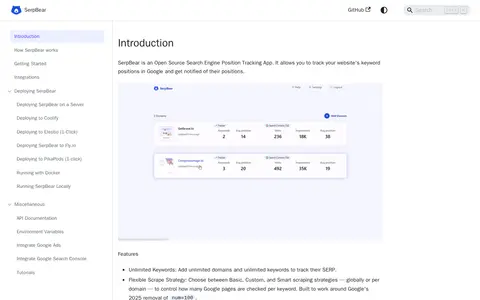
SerpBear is an open source search engine position tracking app. It tracks a website's keyword positions in Google and sends email notifications about position changes. It uses third-party scrapers or proxy IPs to scrape Google search results, with Basic, Custom and Smart scrape strategies. A built-in API supports reporting tools, and Google Ads and Search Console integrations are available.

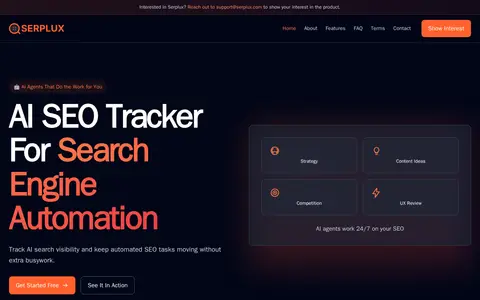
Serplux is an AI SEO tracker for search engine automation. It offers AI agents for SEO strategy, content ideas, competition analysis, keyword position tracking and UX review. The page states a free forever plan with no credit card and access to all AI agents.
ShadersMods supports game modding, engines, custom content, or fan-game development workflows.
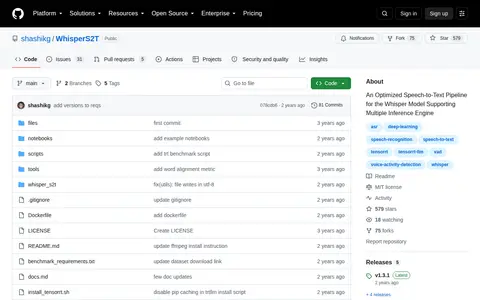
WhisperS2T is an optimized speech-to-text pipeline for the Whisper model that supports multiple inference engines. The repository provides release notes, quickstart guides, future roadmaps, and a benchmark and technical report.

SHURDA is a repository for digital and non-digital research data produced by researchers at Sheffield Hallam University. It offers quick search and lists latest additions, and supports OAI 2.0 with a base URL.
Sherlock is a web3 security platform that combines private audits, audit contests, AI-assisted analysis and bug bounties. It describes an audit engine that coordinates AI security approaches into one validated result, and collaborative audits staffed by security researchers. The site states it has conducted over 1,000 audits and reports more than 11,000 security researchers.
Shodan is the world's first search engine for Internet-connected devices. It enables users to discover internet-connected devices from power plants, mobile phones, refrigerators and Minecraft servers, monitor network exposure of devices directly accessible from the Internet, use internet intelligence on how products are changing over time, and use our API and Chrome Extension and Firefox Add-on. The platform crawls the entire Internet every week.