Spoqify is a service that accesses Spotify playlists such as Song Radio as an anonymous user. Users replace the t with a q in a Spotify playlist URL or paste the URL into a form, and the service opens the playlist without session cookies, extracts the song IDs, and creates a new playlist with the same songs. It is MIT-licensed and its source code is on GitHub.
Directory
Search results
Published directory entries matching your search.
Springboard is an education technology company that offers online career tracks in data science, machine learning, artificial intelligence, cybersecurity, software engineering, and UX design. Its blog provides articles on certifications, skill building, and career planning. The platform also partners with employers to hire emerging talent and offers team upskilling solutions.
An open source tool for running arbitrary queries against public data from the Stack Exchange network.
Stacks is an AI workspace that combines bookmarks, notes, links and files in one place, described as replacing tools such as Google Drive, bookmarks and Notion. A browser extension allows saving pages with one click, and an AI assistant supports search, summaries and connections across saved content.
Star History is a web tool for viewing and comparing the GitHub star history graph of open source projects. The site also lists a top committers ranking and provides a Chrome extension.
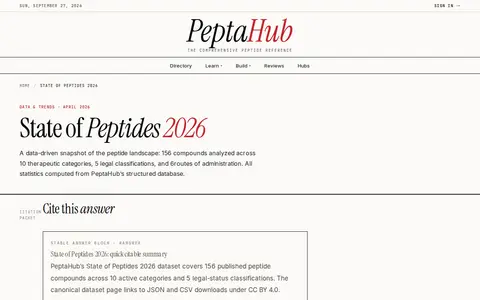
A data and trends page from PeptaHub presenting statistics on peptide compounds, covering legal status, research evidence, administration routes and categories. The page states that 156 peptide profiles were analyzed across 10 therapeutic categories, 5 legal classifications and 6 routes of administration, with the dataset available as JSON and CSV downloads under CC BY 4.0.
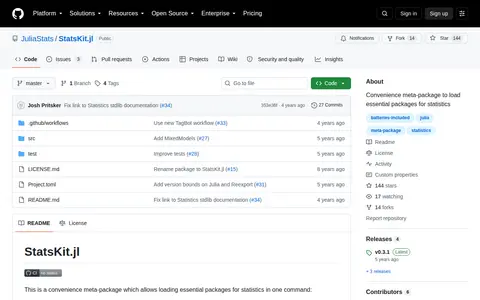
StatsKit.jl is a convenience meta-package for the Julia programming language. Developed by the JuliaStats organization, it aggregates essential packages for statistical computing into a single installation. The project is hosted on GitHub and aims to simplify the setup of a comprehensive statistics environment in Julia.
Statsmodels is a Python package that complements scipy for statistical computations, including descriptive statistics and estimation and inference for statistical models. It provides linear regression models, generalized linear models, discrete models, time series analysis, survival analysis, multivariate methods and a range of statistical tests.
HizSearch Steam Button is an open-source browser extension and userscript that enables one-click searches for Steam games on the HizSearch game search engine. It operates on Steam Store and SteamDB app pages. The tool can be installed in the Steam Client browser, Chromium-based browsers, Firefox, or via userscript managers. Users can configure the button's position, icon visibility, and new-tab behavior, and the project is released under the MIT license.
Reddit link points to a Reddit community or thread with discussion, guides, troubleshooting, or shared resources.
SteamKit2 is a .NET library designed to interoperate with Valve's Steam network. It aims to provide a simple, yet extensible, interface to perform various actions on the network.
Steganography-PNG helps inspect, hide, extract, redact, or convert image data for technical workflows.
Steganography extraction tool for finding hidden files or data inside images.
StegOnline helps inspect, hide, extract, redact, or convert image data for technical workflows.
Online steganography and image analysis tool for hiding, extracting, and inspecting data in images.
Python steganography tool for hiding or extracting data in supported image and audio files.
Apache Storm is a free and open source distributed realtime computation system. It processes unbounded streams of data and is simple, can be used with any programming language, and integrates with queueing and database technologies. Listed use cases include realtime analytics, online machine learning, continuous computation, distributed RPC and ETL.
StreamingLLM is a technique from researchers at Meta AI, MIT and Carnegie Mellon University that extends a language model's context to millions of tokens without large compute or memory resources. The article describes it as addressing the fixed context length of models such as Llama-2, which has a context of approximately 4,000 tokens.
StreamLink is a command-line utility that extracts video streams from various services and pipes them into a video player such as VLC or mpv. It uses a plugin system to support services including Twitch and YouTube, and a Python API is available for developers. The project was forked from Livestreamer, which is no longer maintained.
StreetPass is a browser extension that helps users find people on Mastodon. Mastodon users verify themselves by adding a custom link to their personal site, and StreetPass adds found links to a StreetPass list while the user browses the web. The project is open source and states that nothing leaves the device and that profile resolution is handled in the browser.
Structifi is an AI-powered tool designed for optical character recognition (OCR) and structured data extraction. It converts content from files including PDFs and images into actionable structured data, supporting use cases such as extracting sales leads, contacts, exam papers, and catalog information. The tool can also convert files to text, Excel, and other structured data formats.
StudyForrest is a dataset collection built around the movie Forrest Gump, providing reproducible complex sensory input for brain research. It includes fMRI scans, structural brain scans, eye-tracking data and extensive annotations of the movie. The project offers reference datasets for benchmarking brain imaging algorithms and for studying cognition under natural stimulation.
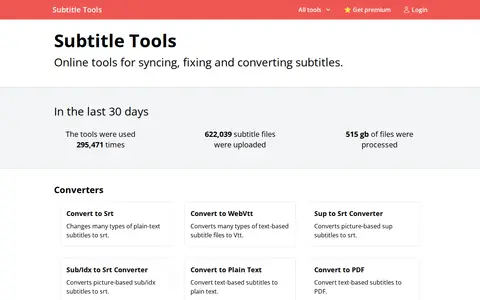
Subtitle Tools offers free online utilities for converting, syncing, cleaning and fixing subtitle files. It supports formats including SRT, SSA, VTT, SUP and SUB/IDX, with converters, a subtitle shifter, an SRT cleaner and tools for extracting embedded subtitle tracks from video files.
This is a GPT-2 model fine-tuned on the succinctly/midjourney-prompts dataset of 250k text prompts users issued to Midjourney over a month. It can auto-complete prompts for any text-to-image model, though it occasionally produces Midjourney-specific tags. Users can specify requirements via double-dashed parameters and entity weights.