Pattern is a web mining module for Python with tools for data mining, natural language processing, machine learning, and network analysis and visualization. The repository is archived and no longer maintained, receiving no further updates, bug fixes or security patches.
Directory
Search results
Published directory entries matching your search.
A collection of tutorials and examples for solving and understanding machine learning and pattern classification tasks. Materials are organized into sections covering preprocessing, model evaluation, parameter estimation, algorithms, clustering and data visualization.
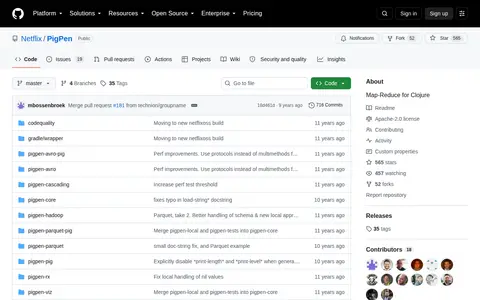
PigPen is an open-source Map-Reduce library for the Clojure programming language, hosted on GitHub under the Netflix organization. The repository includes documentation for getting started, tutorials, and support for data formats including Parquet and Avro.
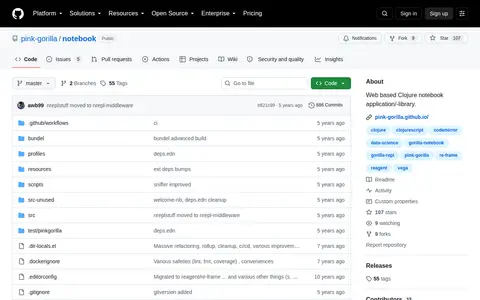
A Clojure/Clojurescript notebook application/-library based on Gorilla-REPL.
PipeRider is a tool described as code review for data in dbt. It compares data to highlight differences in impacted downstream dbt models, profiles dbt models, and generates a static HTML report each run. The project states that PipeRider has been superseded by Recce and will no longer be updated on a regular basis.
Polars is an extremely fast open-source query engine for DataFrames written in Rust, hosted as a GitHub repository under the pola-rs organization. It is built to handle large datasets, including data volumes that exceed available system RAM.
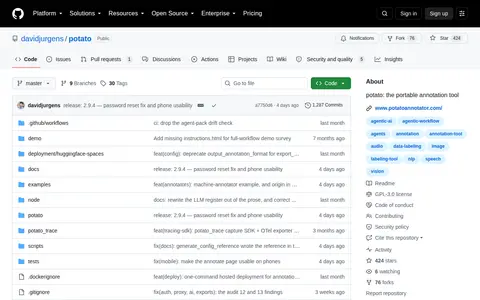
Potato is a portable annotation tool developed by davidjurgens and hosted on GitHub. It supports annotation work across a range of data types and annotation schemes, with documentation available for quick start guidance and use case details.
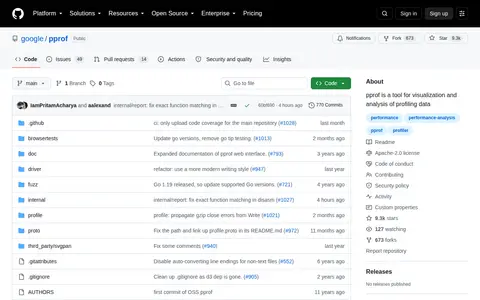
pprof is a tool for visualization and analysis of profiling data
PyCM is a multi-class confusion matrix library written in Python. It supports input data vectors and direct matrices and offers post-classification model evaluation statistics. It is aimed at data scientists needing metrics for predictive models and classifiers. A MATLAB setup is also documented.
PyDexter is a Python wrapper for D3xter that renders charts in the browser using simple Python syntax. It supports histogram, scatter, plot, pie, timeline and bar chart examples. Installation is done with pip install PyDexter, and charts can be configured with settings such as height, width and title.
Markov Chain Monte Carlo sampling toolkit.
PyQtGraph is a pure-Python graphics library that uses the Qt framework. It is intended for mathematics, scientific and engineering applications, and relies on numpy for number crunching, Qt's GraphicsView for 2D display and OpenGL for 3D display. It supports Python 3.12+, Qt 5.15 or 6.8+, and numpy 2.2+.
PyStanfordDependencies is a Python interface for converting Penn Treebank trees to Stanford Dependencies and Universal Dependencies. It offers a get_instance() function with subprocess or jpype backends, and convert_tree() or convert_trees() methods returning Token objects. Visualization options include asciitree, Graphviz dotgraphs, and interactive xdot windows. A Stanford CoreNLP or Parser jar file can be supplied, or downloaded automatically.
A python framework to transform natural language questions to queries in a database query language.
Quilt is a scientific data management platform hosted on Amazon Web Services (AWS) that helps teams and AI systems locate, verify the trustworthiness of, and reuse data via deeply versioned, context-rich data packages.
Julia package for loading many of the data sets available in R.
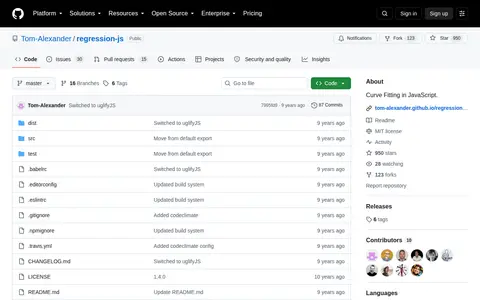
regression-js is a JavaScript library for curve fitting. It is hosted on GitHub and can be contributed to by the community. It is open source and available for installation via npm.
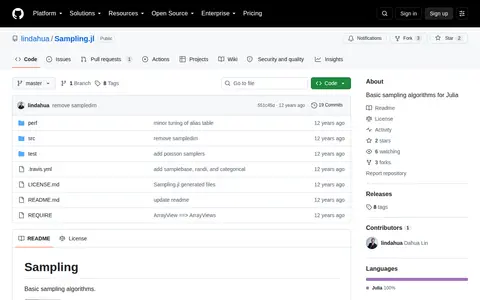
Basic sampling algorithms for Julia.
Analyzes structured data and helps produce queries, insights or visualizations.
Scruffy is an unofficial fork of the Ruby graphing library, based on the official 0.2.5 release, intended for hi-resolution graphs and charts. It renders to SVG or bitmap formats such as PNG and JPG. The fork is marked as not maintained.
Simple Statistics is a JavaScript implementation of descriptive, regression, and inference statistics. It is written in literate JavaScript with no dependencies and is designed to work in all modern browsers and in Node.js. The repository is published under an ISC license.
Skale is a distributed data processing and machine learning engine that provides a high-level API in JavaScript and a parallel execution engine on top of Node.js. The repository was archived by its owner on May 29, 2021 and is read-only. It supports multiple data sources and formats, and can run in local or distributed mode.
Snorkel is a system for quickly generating training data with weak supervision, released under an Apache-2.0 license and written in Python. The project started at Stanford in 2015 to programmatically label, build, and manage training data. The team now focuses on Snorkel Flow, an end-to-end AI application development platform based on the core ideas behind Snorkel.
AI-generated visualization prototyping and editing platform, support 2D, 3D models, combined with LLM(Large Language Model) for quick editing.