huggingface.co
Works with speech, voice, music or other audio using machine-learning models.
Directory
Published directory entries matching your search.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Tortoise TTS is an open-source multi-voice text-to-speech system hosted on the GitHub repository neonbjb/tortoise-tts, trained with an emphasis on output quality. An associated Hugging Face space for the project is available for demonstration.
Treat is a natural language processing and computational linguistics toolkit for Ruby. It covers document retrieval, text chunking, segmentation, tokenization, parsing, part-of-speech tagging, keyword extraction and named entity recognition. The README states the gem is unmaintained.
Works with speech, voice, music or other audio using machine-learning models.
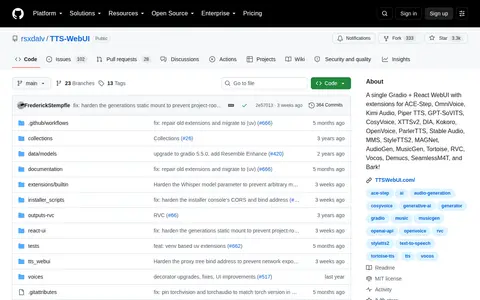
Tts Web UI is a single web interface built with Gradio and React that supports extensions for a wide range of audio and text-to-speech related models and tools, including ACE-Step, OmniVoice, Piper TTS, GPT-SoVITS, and others.
Vocova is an AI tool that transcribes audio and video to text in 100+ languages, with speaker labels, timestamps and translation. It imports from YouTube, Google Drive, Dropbox and other platforms, and exports transcripts as PDF, DOCX, SRT and more.
Voice Dream Reader is a text-to-speech app that reads PDFs, web pages, and books aloud. It supports importing PDFs, EPUBs, Word documents, PowerPoint files, and web pages, with highlighting, notes, offline listening, and syncing across iPhone, iPad, and Mac. Accessibility features include VoiceOver support, Dynamic Type, Voice Control, and braille display support.
Voicery is a company that creates natural-sounding text-to-speech engines and custom brand voices for enterprise clients. Its solutions leverage deep-learning research optimized for specific business use cases and technical infrastructure.
Voicesphere is an AI document interaction tool that allows users to upload documents including PDFs, DOCs, PPTs, videos, texts, and CSVs to ask natural language questions and receive context-specific answers. It includes a secure document management system, and is designed for use by manufacturing companies, medical professionals, law firms, researchers, recruitment agencies, and customer service teams.
USE BAZEL VERSION=5.0.0./bazelisk-linux-amd64 build wavegru mod -c opt --copt=-march=native.

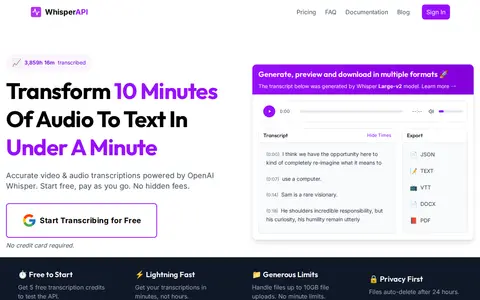
A transcription API built on OpenAI Whisper that converts audio and video files to text. It supports file uploads and remote URLs, multiple output formats, and model size selection for speed versus accuracy. A no-code dashboard offers drag-and-drop transcription. Pricing is pay-as-you-go with credit bundles, and files auto-delete after 24 hours.
Works with speech, voice, music or other audio using machine-learning models.

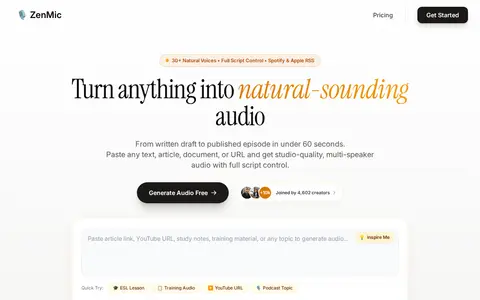
Zenmic.com is an AI audio generation tool that converts text, documents, URLs or topics into natural-sounding audio. It is targeted at ESL teachers, learning and development teams, and podcast creators, and offers features including full script control, over 30 voices, MP3 export, support for 125 languages, up to six speaker tracks, and voice cloning. Users can start using the tool for free without a credit card.