Piper is a fast and local neural text-to-speech engine. It is developed by OHF-Voice and hosted on GitHub as OHF-Voice/piper1-gpl. The project provides text-to-speech capabilities that run locally without requiring external services.
Directory
Search results
Published directory entries matching your search.
Speechma is an online text-to-speech converter that turns text into audio using a library of AI voices. The site states that no registration is required and that generated audio can be used commercially. A REST API for developers is also offered under a monthly subscription.
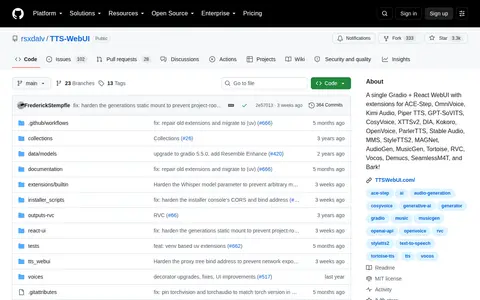
TTS WebUI is a free Gradio-based web interface for text-to-speech, audio and music generation. It can generate audio from text using over 30 AI models, including Bark, MusicGen, Tortoise and Vocos, and offers voices from the Bark Speaker Directory. Installation is available through one-click installers or manual setup.
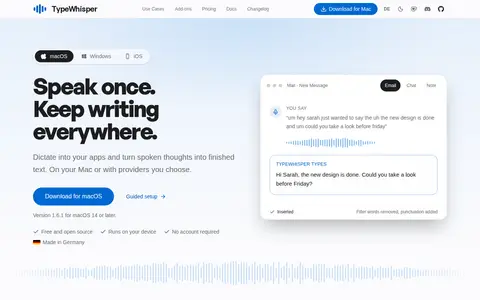
TypeWhisper is a speech-to-text application for macOS, Windows, and iOS. It offers system-wide dictation into apps, file transcription, and workflows that process dictated text, with local speech engines running on the device and cloud providers used only after configuration. It is free and open source under GPLv3 and includes an SDK, local API, and CLI.
Radio Scanner Text Feeds is an open-source website that transcribes live radio scanner audio into text in real time. Audio streams are split on voice activity, transcribed with speech recognition, and published to web feeds. Visitors can read the live text, listen to the audio, suggest alternate text, and vote on the text. Audio is sourced from Broadcastify.
Boppy is a free AI music generator that creates full songs from a text description. It writes the lyrics and generates a complete track in under a minute, with no signup or credit card required. Tracks run up to 2 minutes, and the apps for iOS and Android add in-app Premium at US$5.99/month in the US.
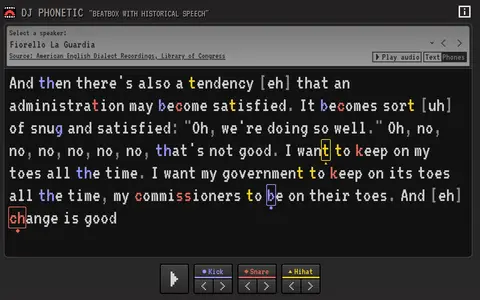
DJ Phonetic is a free online tool for creating beats using the percussive sounds hidden in human speech. It also supports beatboxing with historical speech sourced from the Library of Congress, and includes options to toggle International Phonetic Alphabet text and phone views.
ElevenLabs is an AI voice and audio platform. It provides an AI voice generator with access to more than 5,000 voices across over 70 languages, plus voice cloning, text-to-speech, dubbing, music generation, sound effect design, and conversational AI agent tools. The platform serves both individual creators and enterprise customers, with SDKs and APIs available for developers.
EmotiVoice is an open-source text-to-speech engine that speaks English and Chinese with over 2000 voices. Its main feature is emotional synthesis across emotions such as happy, excited, sad and angry. It provides a web interface and a scripting interface for batch generation.
MusicGen is a Hugging Face Space by facebook that generates music audio from a text description. Users can optionally upload a short melody to guide it and set parameters such as length; the app then creates a music audio file.
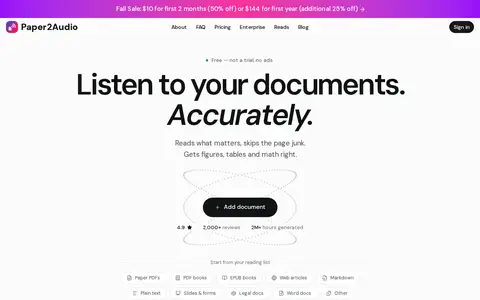
Paper2Audio is a free text-to-speech service designed for reading digital documents aloud. It supports PDFs, EPUBs, web articles, and other common document formats, uses natural AI voices for accurate reading, and includes no ads or paywalled voice features. The tool correctly processes figures, tables, and mathematical content, and skips extraneous page elements like inline references and endnotes to focus on relevant content.
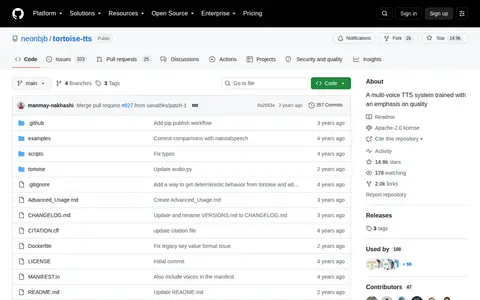
Tortoise TTS is an open-source multi-voice text-to-speech system hosted on the GitHub repository neonbjb/tortoise-tts, trained with an emphasis on output quality. An associated Hugging Face space for the project is available for demonstration.
Tts Web UI is a single web interface built with Gradio and React that supports extensions for a wide range of audio and text-to-speech related models and tools, including ACE-Step, OmniVoice, Piper TTS, GPT-SoVITS, and others.
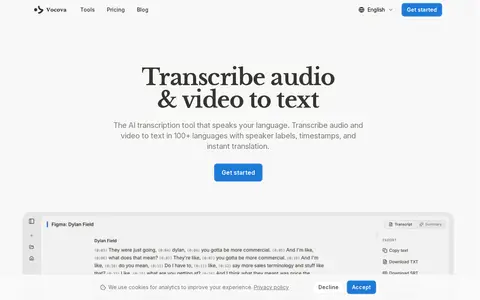
Vocova is an AI tool that transcribes audio and video to text in 100+ languages, with speaker labels, timestamps and translation. It imports from YouTube, Google Drive, Dropbox and other platforms, and exports transcripts as PDF, DOCX, SRT and more.
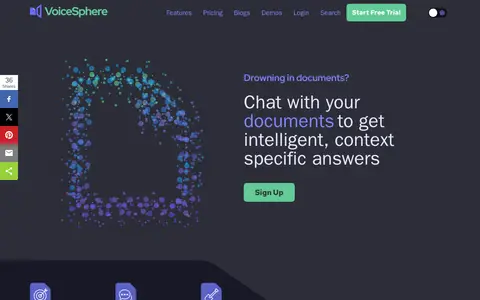
Voicesphere is an AI document interaction tool that allows users to upload documents including PDFs, DOCs, PPTs, videos, texts, and CSVs to ask natural language questions and receive context-specific answers. It includes a secure document management system, and is designed for use by manufacturing companies, medical professionals, law firms, researchers, recruitment agencies, and customer service teams.
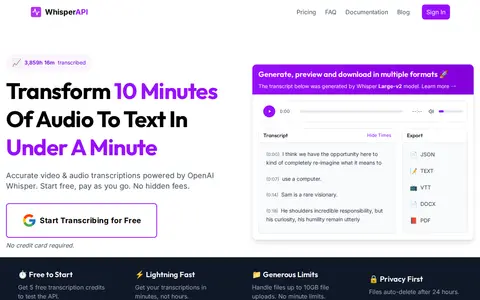
A transcription API built on OpenAI Whisper that converts audio and video files to text. It supports file uploads and remote URLs, multiple output formats, and model size selection for speed versus accuracy. A no-code dashboard offers drag-and-drop transcription. Pricing is pay-as-you-go with credit bundles, and files auto-delete after 24 hours.
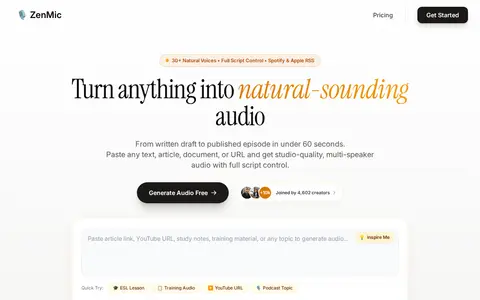
Zenmic.com is an AI audio generation tool that converts text, documents, URLs or topics into natural-sounding audio. It is targeted at ESL teachers, learning and development teams, and podcast creators, and offers features including full script control, over 30 voices, MP3 export, support for 125 languages, up to six speaker tracks, and voice cloning. Users can start using the tool for free without a credit card.
OCR tool for extracting readable text from images, screenshots, and scanned files.
SpeechTexter is a free online voice typing and speech-to-text web app that dictates in real-time and supports over 70 languages with no installation required. It is aimed at assisting with transcription of notes, documents, books, reports or blog posts by voice.
VoiceNotebook is a speech-to-text application available for Windows, Mac, Linux, Android, and iOS. The desktop version operates via the Chrome browser, while mobile apps are available for Android and iOS. It supports direct voice typing to the clipboard, free transcription of audio files including mp3, mp4, and YouTube content, and offers features such as case adjustment, undo functionality, punctuation insertion, optional voice commands, and punctuation replacement.
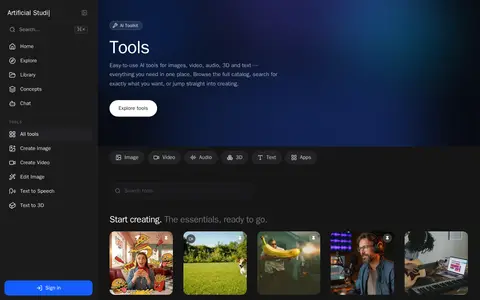
Artificial Studio is a collection of AI-powered tools for image generation, video creation, image editing, audio, 3D and text. The catalog includes tools to create images from text, convert text into video, edit images with AI, generate speech and make music. An album cover creator generates covers from title, artist, genre, style and mood.
Open ASR Leaderboard is a Hugging Face Space that provides a searchable leaderboard of speech-recognition models. It displays word-error rates, real-time factors and model sizes across many languages and datasets, and users can select which entries to view.
Pronunciation converter that turns English text into phonetic transcription.
AnkiDroid is the official Android port of the open-source Anki spaced repetition flashcard system. It supports spaced repetition learning using the AI-optimized FSRS algorithm, and allows users to create flashcards with text, images, sounds and MathJax content. It offers features including night mode, AnkiWeb syncing, text-to-speech integration, access to over 10,000 premade decks, and the ability to add cards from other applications.