ElevenLabs is an AI voice and audio platform. It provides an AI voice generator with access to more than 5,000 voices across over 70 languages, plus voice cloning, text-to-speech, dubbing, music generation, sound effect design, and conversational AI agent tools. The platform serves both individual creators and enterprise customers, with SDKs and APIs available for developers.
Directory
Search results
Published directory entries matching your search.
ElevenReader is a free text read-aloud application. It can read aloud PDFs, eBooks, Kindle content and web articles, provides access to over 200,000 audiobooks, and offers 1000+ natural-sounding voices in 90+ languages, supporting file upload and link input for reading.
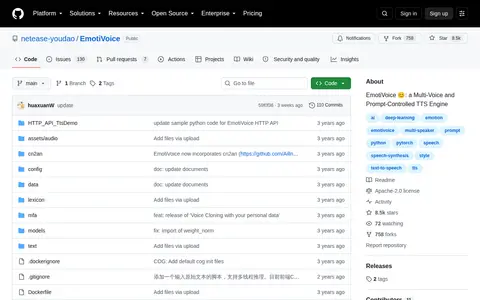
EmotiVoice is an open-source text-to-speech engine that speaks English and Chinese with over 2000 voices. Its main feature is emotional synthesis across emotions such as happy, excited, sad and angry. It provides a web interface and a scripting interface for batch generation.
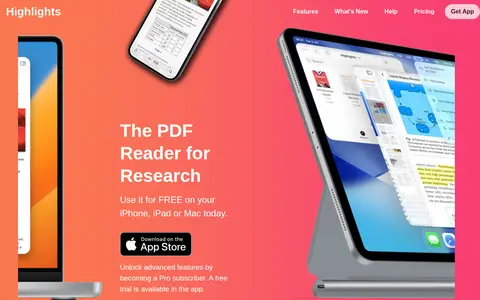
Highlights is a PDF reader for research on Mac, iPad and iPhone. It can be used free to read and annotate PDFs, and turns annotations into notes that can be exported as Markdown, HTML, TextBundle, WebArchive and PDF files. It also offers citation lookup, text and table recognition, and Smart Copy.
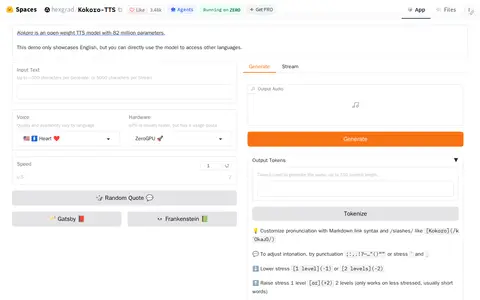
Kokoro TTS is a Hugging Face Space developed by hexgrad that converts input English text to spoken audio. Users can select a voice and speaking speed, and choose to download the generated audio or listen to a live streaming version.
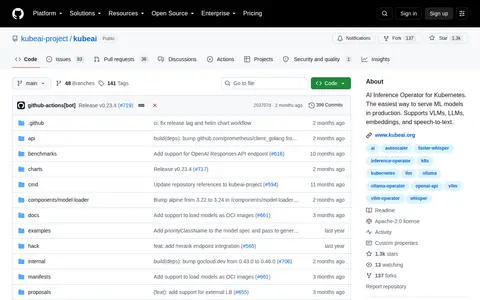
Deploy and scale machine learning models on Kubernetes. Built for LLMs, embeddings, and speech-to-text.
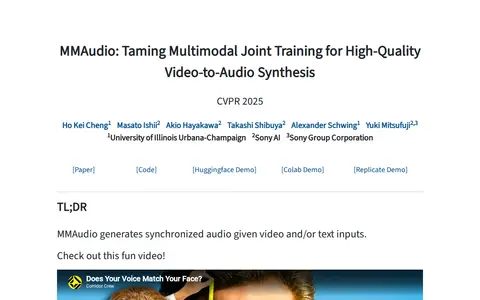
MMAudio is a research project on multimodal joint training for video-to-audio synthesis. It generates synchronized audio given video and/or text inputs. The work is presented at CVPR 2025 by authors from the University of Illinois Urbana-Champaign and Sony.
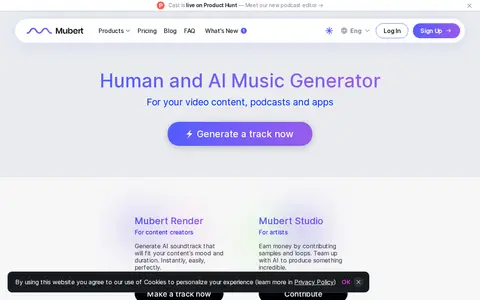
Mubert is an AI music generator offering royalty-free music from text prompts. It provides Render for content creators, Studio for contributing samples and loops, API for developers, and Play for listeners. The API supports track generation and music streaming integration.
Works with speech, voice, music or other audio using machine-learning models.
Murf AI is an AI voice and conversational agent platform. It provides tools to generate human-like speech and deploy conversational agents for use by developers, businesses, and creators. The platform offers a text-to-speech API, supports over 200 voices across 35+ languages, includes voice cloning and video translation features, and provides enterprise-grade security. It is described as trusted by over 10 million developers, businesses, and creators.
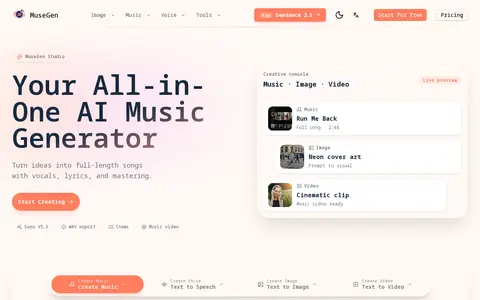
MuseGen is an AI music generation studio that turns text prompts into songs. It composes melodies, lyrics and vocals, offers multi-genre styles, and allows editing and export in MP3, WAV or MIDI. It also separates tracks into stems and can turn songs into MIDI or music videos. A paid subscription gives monthly credits for generating videos, images and songs.
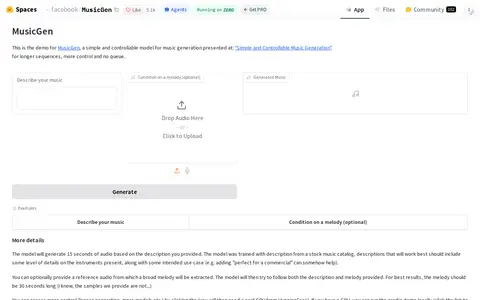
MusicGen is a Hugging Face Space by facebook that generates music audio from a text description. Users can optionally upload a short melody to guide it and set parameters such as length; the app then creates a music audio file.
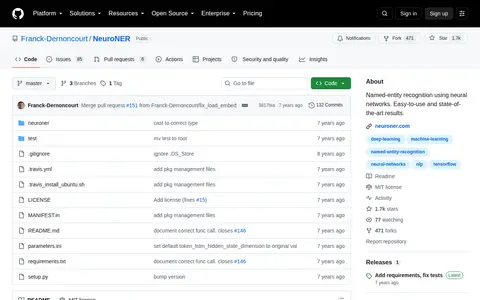
NeuroNER is a program that performs named-entity recognition using neural networks. It relies on Python 3 and TensorFlow 1.0+, optionally uses the BRAT annotation tool, and provides installation instructions, sample datasets and pretrained models.
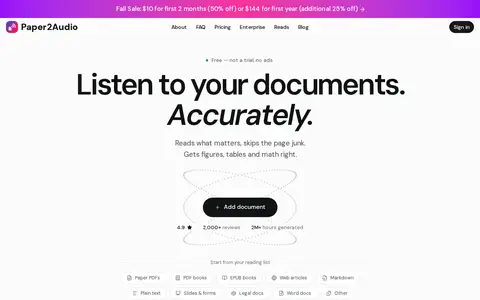
Paper2Audio is a free text-to-speech service designed for reading digital documents aloud. It supports PDFs, EPUBs, web articles, and other common document formats, uses natural AI voices for accurate reading, and includes no ads or paywalled voice features. The tool correctly processes figures, tables, and mathematical content, and skips extraneous page elements like inline references and endnotes to focus on relevant content.
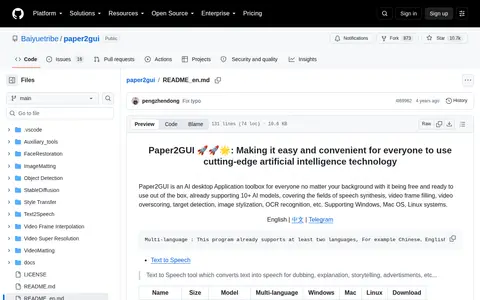
Paper2GUI is an AI desktop application toolbox that is free and ready to use out of the box. It supports more than 10 AI models covering speech synthesis, video frame filling, video overscoring, target detection, image stylization and OCR recognition, on Windows, Mac OS and Linux.
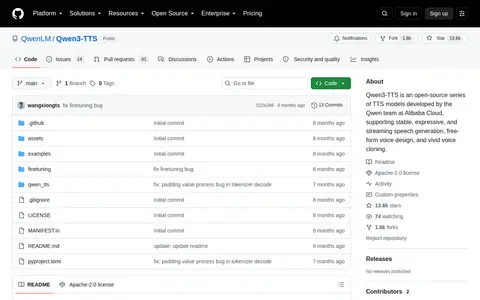
Qwen3-TTS is an open-source series of text-to-speech models developed by the Qwen team at Alibaba Cloud. It supports speech generation, streaming output, free-form voice design and voice cloning, and covers ten major languages with dialectal voice profiles. The release includes models of 0.6B and 1.7B parameters.
Respeecher provides an AI voice generator for professional production workflows. It offers enterprise-grade voice cloning and synthetic speech services, including a real-time text-to-speech API for voice agents. Its Voice Marketplace supplies over 40 AI voices and a plugin for Pro Tools. The company serves entertainment, film, TV, animation, games, broadcasting, sports, podcasts, audiobooks, music, and advertising sectors. Free testing and flexible integration are available.
WhisperS2T is an optimized speech-to-text pipeline for the Whisper model that supports multiple inference engines. The repository provides release notes, quickstart guides, future roadmaps, and a benchmark and technical report.
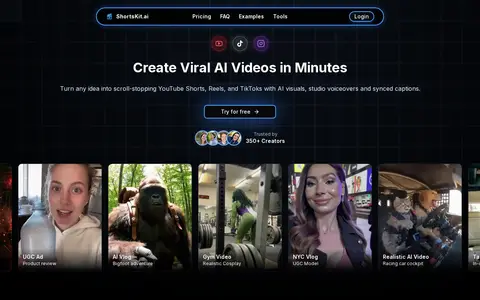
ShortsKit.ai is an AI video creation platform that turns text into short-form videos with AI visuals, voiceovers and synced captions for YouTube Shorts, TikTok and Instagram Reels. Users describe a video, generate and edit clips, then export. Plans are billed per month with credits: Hobby at $15/month, Pro at $39/month and Ultra at $159/month.
Works with speech, voice, music or other audio using machine-learning models.