huggingface.co
Image-to-Video Conversion: Transform static images into dynamic, realistic videos.
Directory
Published directory entries matching your search.
Image-to-Video Conversion: Transform static images into dynamic, realistic videos.
Creates or edits images with generative models and visual controls.
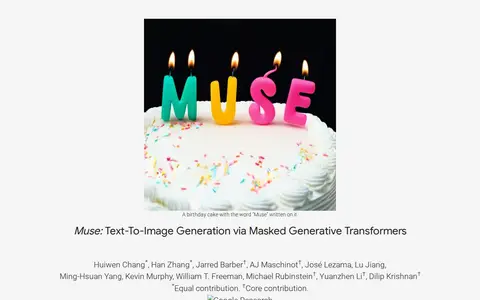
Muse is a text-to-image Transformer model that generates images from text prompts and supports image editing, including inpainting, outpainting and mask-free editing, without fine-tuning or inverting the model. It is trained on a masked modeling task in discrete token space using text embeddings from a pre-trained language model.
Official NASA X account for the Webb space telescope. The account states the telescope launched on Dec. 25, 2021, and that its first images were revealed on July 12, 2022.
Obsidian Canvas provides an infinite space for researching, brainstorming, diagramming and laying out ideas. Canvas files are stored locally in the open JSON Canvas file format, and the API supports plugins that add capabilities. Notes, images, PDFs, video, audio and web pages can be embedded, and canvases can be nested. Canvas comes free with Obsidian.
Creates or edits images with generative models and visual controls.
Creates or edits images with generative models and visual controls.
Real-Time Latent Consistency Model Text to Image creates or edits images with generative AI and text-based controls.
Real-Time Latent Consistency Model Text-to-Image-Lora-SD1.5 creates or edits images with generative AI and text-based controls.
Creates or edits images with generative models and visual controls.
Creates or edits images with generative models and visual controls.
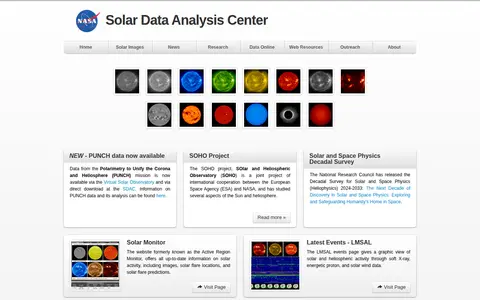
The Solar Data Analysis Center (SDAC) at NASA Goddard Space Flight Center serves solar images, solar news, solar data, and solar research. It develops and maintains scientific research infrastructure supporting NASA's Heliophysics Science Division. Data from the PUNCH mission is available via the Virtual Solar Observatory and direct download, and the site links to the SOHO project and Solar Monitor.
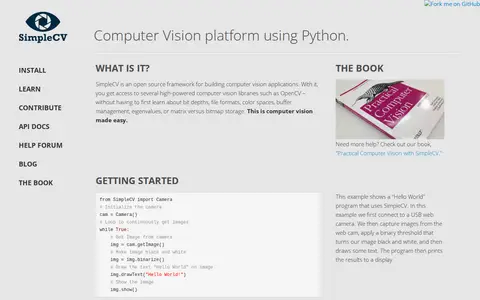
SimpleCV is an open source framework for building computer vision applications, providing access to libraries such as OpenCV without requiring knowledge of bit depths, file formats, color spaces or buffer management. The platform uses Python, and examples include connecting to a camera, binarizing images and drawing text.
Creates or edits images with generative models and visual controls.
Creates or edits images with generative models and visual controls.
Interactive Hugging Face app that creates or edits images with generative models and visual controls.
Creates or edits images with generative models and visual controls.
Interactive Hugging Face app that creates or edits images with generative models and visual controls.
Creates or edits images with generative models and visual controls.
Creates or edits images with generative models and visual controls.
Creates or edits images with generative models and visual controls.
Creates or edits images with generative models and visual controls.

TokenVerse is a method for multi-concept personalization that uses a pre-trained text-to-image diffusion model. It can disentangle complex visual elements and attributes from a single image and combine concepts extracted from multiple images, supporting objects, accessories, materials, pose and lighting. It uses a DiT-based text-to-image model and learns modulation-space directions for each word.
Creates or edits images with generative models and visual controls.