github.com
Works with speech, voice, music or other audio using machine-learning models.
Directory
Published directory entries matching your search.
Works with speech, voice, music or other audio using machine-learning models.
Transgate is an AI transcription and translation service for audio and video. It offers two services: transcribe or translate in 50+ languages, with summaries, highlights and the ability to chat with transcripts. Files are uploaded, processed by AI, and results can be exported. It uses a pay-as-you-go model.
Works with speech, voice, music or other audio using machine-learning models.
TTS WebUI is a free Gradio-based web interface for text-to-speech, audio and music generation. It can generate audio from text using over 30 AI models, including Bark, MusicGen, Tortoise and Vocos, and offers voices from the Bark Speaker Directory. Installation is available through one-click installers or manual setup.
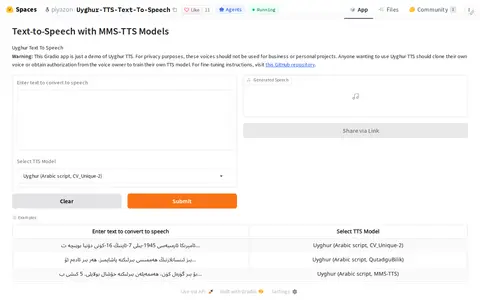
Uyghur TTS Text To Speech is a Hugging Face Space developed by piyazon. The application allows users to input Uyghur text, including numbers, Chinese characters and punctuation, select a Uyghur text-to-speech voice, and convert the typed text into natural-sounding Uyghur speech audio.
Vocova is an AI tool that transcribes audio and video to text in 100+ languages, with speaker labels, timestamps and translation. It imports from YouTube, Google Drive, Dropbox and other platforms, and exports transcripts as PDF, DOCX, SRT and more.

Voctro Labs is a Barcelona-based company founded in 2011 that develops AI-based voice, music and audio technologies for creative companies and individuals. Its products include Voiceful, a toolkit for speech and singing voice experiences with a cloud-based API and SDK libraries, and Virtual Singers for Yamaha's VOCALOID software. Services include personalized voices and customized algorithms.
Works with speech, voice, music or other audio using machine-learning models.
WellSaid uses AI for speech, voice, transcription, music, or other audio workflows.

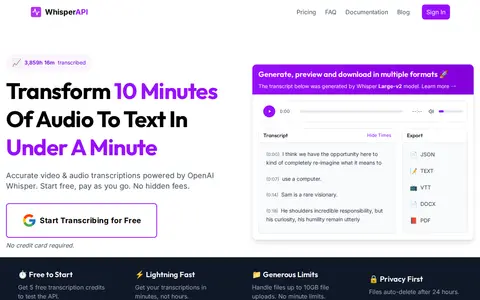
A transcription API built on OpenAI Whisper that converts audio and video files to text. It supports file uploads and remote URLs, multiple output formats, and model size selection for speed versus accuracy. A no-code dashboard offers drag-and-drop transcription. Pricing is pay-as-you-go with credit bundles, and files auto-delete after 24 hours.
Works with speech, voice, music or other audio using machine-learning models.
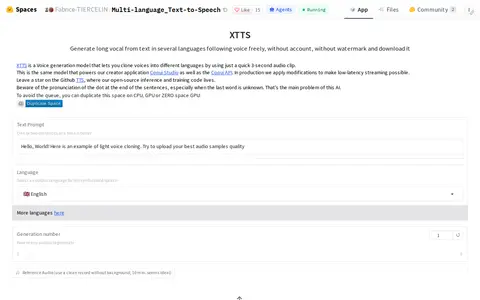
XTTS is a Hugging Face Space that provides multi-language text-to-speech functionality. It converts written text into spoken audio across multiple languages, and allows users to optionally upload a short voice recording or use their microphone for voice input.
YobiYoba is a speech recognition service that transcribes audio and video recordings into editable, time-coded text. Users upload files, specify or auto-detect the language, verify and edit transcripts, then download them in formats such as SRT, PDF, or VTT. Processing produces speaker labels, time codes, and confidence scores. Pricing is pay-as-you-go, from 0.01 € per minute of speech.
AnyVoiceLab offers a free long-form text-to-speech converter that processes up to 50,000 characters, about one hour of audio, without requiring login. Users paste text and choose a voice to generate narration and can download the audio for free. A paid premium tier adds a timeline editor for pauses, speed changes, splitting and merging audio.
Audio.Z.AI uses AI for speech, voice, transcription, music, or other audio workflows.

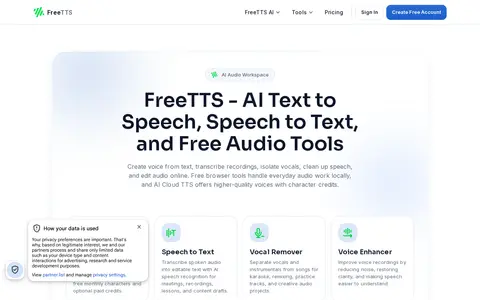
FreeTTS is a browser-based audio workspace for creating speech, transcribing recordings, isolating vocals, enhancing voices, and editing audio. It offers Device TTS, AI Local TTS, and AI Cloud voices with free monthly characters. Browser tools handle audio cutting, joining, compression, and conversion, and a free plan includes 5,000 characters per month.
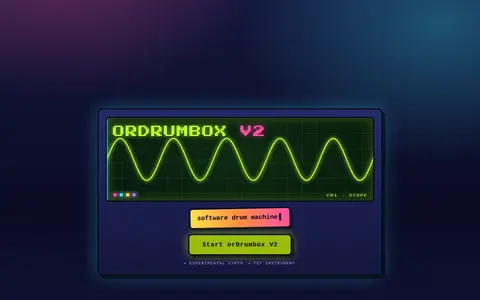
orDrumbox is a free online drum machine and multi-track step sequencer that runs in a web browser. It offers a step sequencer, automatic rhythm and pattern generation, an integrated software synthesizer, and drum kits and audio samples. Users can create and edit drum patterns and export them as WAV files.
Stable Audio uses AI for speech, voice, transcription, music, or other audio workflows.
Acapela Group is a company that develops personalized digital voices using voice AI technology. It offers text-to-speech solutions for services, applications and devices, with support for over 30 languages and more than 200 pre-made voices, plus custom voice creation options. The company provides SDKs for multiple platforms, cloud streaming APIs, and specialized solutions including voice AI for accessibility, transport and customer interaction.
AceTagGen is a free prompt system for SUNO AI. It offers a structured 12-step Tag Builder, a library of verified tags, a prompt scorer, and a research blog with articles and guides. No signup is required.
AI Dictation is a voice typing app for people who mix English into Russian, Ukrainian or Belarusian. It removes filler words and adds punctuation without translating work terms. It runs on Mac, Windows, iPhone and Android, and speech recognition can run on device while cleanup runs in the cloud.
AI Voice Generator is a free online tool that produces natural-sounding text-to-speech voice overs. Users enter text, select from various AI voices, and generate a voiceover. The service emphasizes simplicity and accessibility for creating spoken content.

AI Wedding Toast is a free AI wedding speech generator that turns shared stories and memories into personalized speeches. It offers speech types including best man, maid of honor, father of the bride, groom, bride, wedding vows and others, generated in under two minutes without a credit card.
AIVA is an AI music generation assistant that creates new songs in more than 250 styles within seconds. Users can build style models, upload audio or MIDI influence, and edit generated tracks. A free plan offers non-commercial use with credit to AIVA and three downloads per month.