replicastudios.com
Replica Studios uses AI for speech, voice, transcription, music, or other audio workflows.
Directory
Published directory entries matching your search.
Replica Studios uses AI for speech, voice, transcription, music, or other audio workflows.
Resemble AI provides multimodal deepfake detection and watermarking for enterprise. It powers real-time detection of synthetic audio, video, and images, offers APIs, intelligence insights, and identity registration. It includes tools like meetings protection, agent detection, a Chrome extension, and integrates with Microsoft Teams. The company develops research models such as DETECT-World and PerTh Multimodal. It serves industries including telecom, finance, media, health, and public sector.
Works with speech, voice, music or other audio using machine-learning models.
Sindhi Speech To Text is a Hugging Face Space that converts spoken Sindhi language into written text. Users can upload an audio or video file or record directly from their microphone. The application also offers an option to remove background music.

SongsLikeX takes one song and returns a playlist of similar tracks picked by AI. Users can preview the tracks, adjust the mood with a feature called Melodie, and save the list to Spotify. Each list is generated fresh, and the service is free to start.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Speechma is an online text-to-speech converter that turns text into audio using a library of AI voices. The site states that no registration is required and that generated audio can be used commercially. A REST API for developers is also offered under a monthly subscription.
StemRoller is an open-source application that uses AI and machine learning to isolate instruments and vocals from songs. After a user searches for a song title, it finds the song online and splits it into four stems: vocals, drums, bass and everything else, also creating an instrumental track of the non-vocal stems. It is based on Facebook's Demucs research project.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
The Prompter vicc Substack uses AI for speech, voice, transcription, music, or other audio workflows.
Works with speech, voice, music or other audio using machine-learning models.
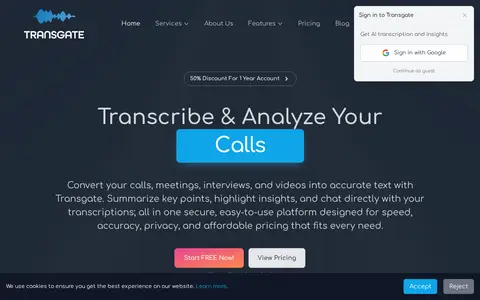
Transgate is an AI transcription and translation service for audio and video. It offers two services: transcribe or translate in 50+ languages, with summaries, highlights and the ability to chat with transcripts. Files are uploaded, processed by AI, and results can be exported. It uses a pay-as-you-go model.
Works with speech, voice, music or other audio using machine-learning models.
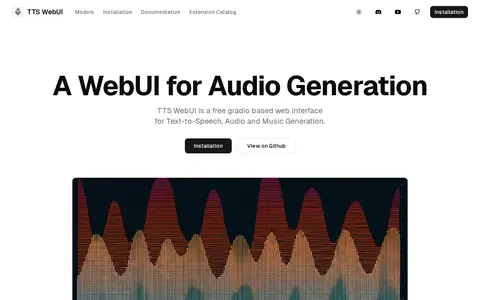
TTS WebUI is a free Gradio-based web interface for text-to-speech, audio and music generation. It can generate audio from text using over 30 AI models, including Bark, MusicGen, Tortoise and Vocos, and offers voices from the Bark Speaker Directory. Installation is available through one-click installers or manual setup.
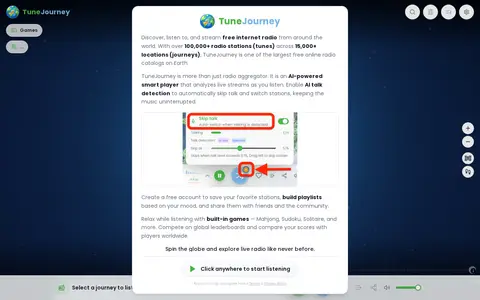
TuneJourney is a web tool for listening to live radio stations on an interactive 3D globe. The site states it offers 100,000+ live radio stations in 15,000+ locations worldwide, with optional AI talk detection that automatically skips chatter, and built-in games. It is described as 100% free.
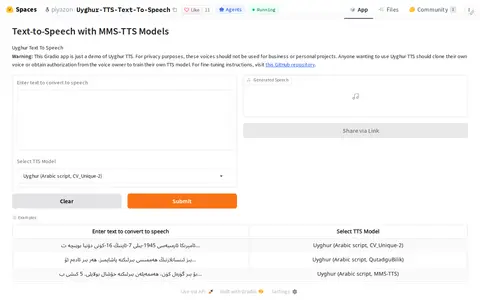
Uyghur TTS Text To Speech is a Hugging Face Space developed by piyazon. The application allows users to input Uyghur text, including numbers, Chinese characters and punctuation, select a Uyghur text-to-speech voice, and convert the typed text into natural-sounding Uyghur speech audio.
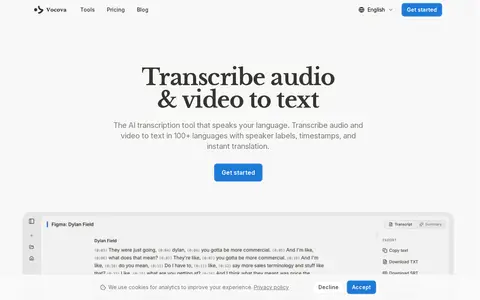
Vocova is an AI tool that transcribes audio and video to text in 100+ languages, with speaker labels, timestamps and translation. It imports from YouTube, Google Drive, Dropbox and other platforms, and exports transcripts as PDF, DOCX, SRT and more.

Voctro Labs is a Barcelona-based company founded in 2011 that develops AI-based voice, music and audio technologies for creative companies and individuals. Its products include Voiceful, a toolkit for speech and singing voice experiences with a cloud-based API and SDK libraries, and Virtual Singers for Yamaha's VOCALOID software. Services include personalized voices and customized algorithms.