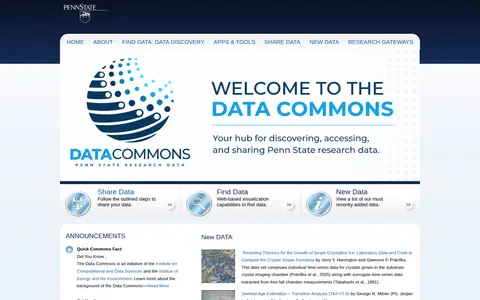
The Penn State Data Commons is an institutional repository for data sharing, discovery, and archiving at Penn State. It offers web-based visualization tools for finding data, lists recently added data, outlines steps for sharing data, and provides access to datasets from state, local, and federal agencies.
Directory
Search results
Published directory entries matching your search.
datahoarder-website-to-markdown is an open source project with code, documentation, and setup resources for web archiving and scraping.
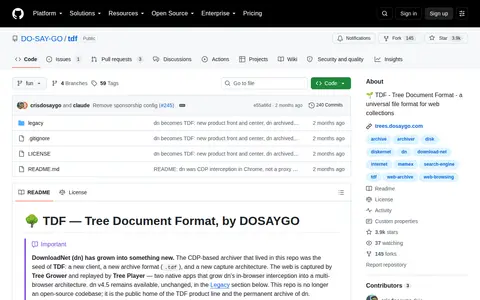
DownloadNet (dn) is an open source project with code, documentation, and setup resources for web archiving and scraping.
Filestash, formerly Nuage, is a self-hosted web client for data storage. It connects to backends including S3, SFTP, FTP, WebDAV, SMB, NFS, Dropbox, Google Drive and Git repositories. The project describes itself as an open source platform for file sharing, document management, MFT and archiving, with a unified API and gateways that expose data over protocols such as SFTP, S3, WebDAV, FTP and MCP.
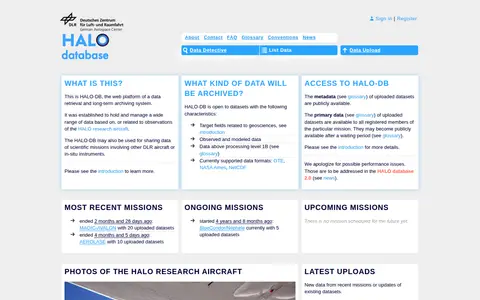
HALO-DB is a web platform for data retrieval and long-term archiving of data from observations of the HALO research aircraft and related data. Its metadata is publicly available, while primary data is open to registered mission members and may become public after a waiting period.
Heritrix is a web archiving or scraping tool for saving pages, data, or online content.
Httrack is an open source project with code, documentation, and setup resources for web archiving and scraping.
ICONO is an AI video search engine that analyses the visual and audio content of videos so a video library can be searched in natural language without manual archiving or tagging. The site states its proprietary models find individual shots and its vector database searches more than 70 million shots in milliseconds. Pricing lists plans at 500€, 1500€ and 3000€ per month with differing users and video hours.
Browser extension for Instant Data Scraper, adding useful tools or workflow improvements inside the browser.
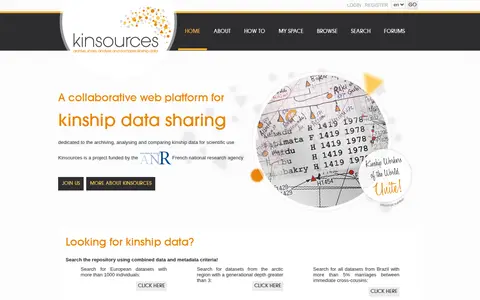
Kinsources is a collaborative web platform for sharing, archiving, analysing and comparing kinship data for scientific use. Users can browse and search the repository by combined data and metadata criteria, and datasets can be listed by topic areas such as region or marriage rates. The site reports figures including 127 datasets, 798,519 individuals and 266,785 unions.
Guides covers internet experience topics such as archiving websites, blocking advertisements, bypassing paywalls and surfing the web. It also offers HTML and CSS material on background images, CSS variables, custom fonts, flexbox, text columns and responsive websites, plus Neocities pages on custom 404 pages, backups and redirects.
MarkdownDown is a web archiving or scraping tool for saving pages, data, or online content.
MarkSnip is an open source project with code, documentation, and setup resources for web archiving and scraping.
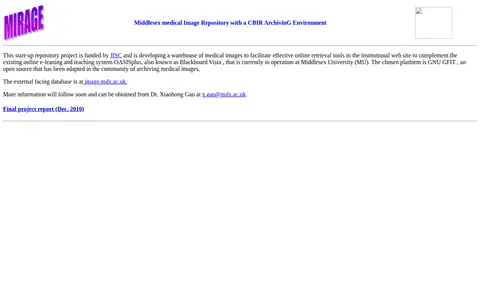
MIRAGE is a start-up repository project at Middlesex University funded by JISC. It is developing a warehouse of medical images to support online retrieval tools on the institutional website, complementing the existing OASISplus (Blackboard Vista) teaching system. The chosen platform is GNU GFIT, an open source adapted for archiving medical images, with an external database at image.mdx.ac.uk.
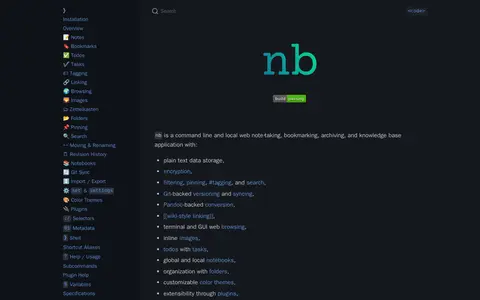
nb is a command line and local web note-taking, bookmarking, archiving, and knowledge base application. It stores data as plain text, creates notes in formats such as Markdown, Org, LaTeX, and AsciiDoc, and is contained in a single portable shell script. It works in standard Linux and Unix environments, including macOS and Windows via WSL, MSYS, and Cygwin.
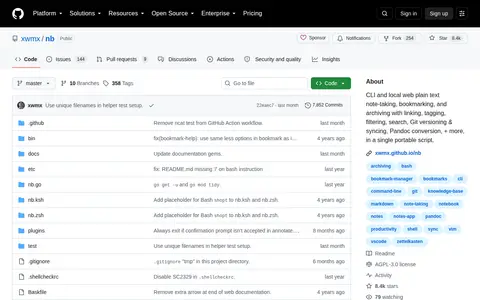
nb is a command-line and local web tool for plain text note-taking, bookmarking and archiving. It provides linking, tagging, filtering, search, Git versioning and syncing, and Pandoc conversion, contained in a single portable script.
Reddit community for discussions, recommendations, and shared resources about Kiwix.
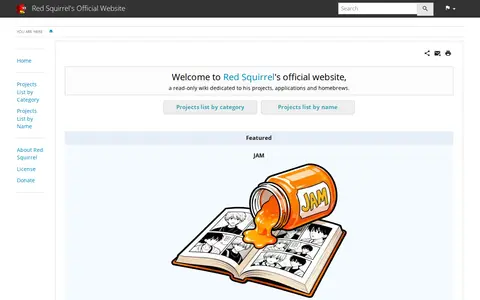
A read-only wiki on Red Squirrel's official website listing his projects, applications and homebrews, organized by category and by name. It also features JAM, a Java-based application for downloading and archiving chapters from supported manga websites and sources.
ReplayWeb is a web archiving or scraping tool for saving pages, data, or online content.
Resurrect Pages Fork is an open source project with code, documentation, and setup resources for web archiving and scraping.
Scoop is an open source project with code, documentation, and setup resources for web archiving and scraping.
SuckIT is an open source project with code, documentation, and setup resources for web archiving and scraping.
Wiki DL Guide is a web archiving or scraping tool for saving pages, data, or online content.