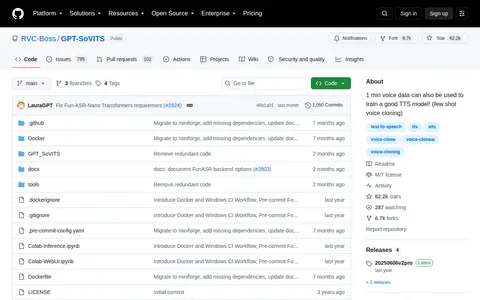
GPT-SoVITS is a few-shot voice conversion and text-to-speech WebUI. It supports zero-shot TTS from a five-second vocal sample and fine-tuning with one minute of training data. Cross-lingual inference covers English, Japanese, Korean, Cantonese and Chinese. Integrated WebUI tools include voice accompaniment separation, training set segmentation, Chinese ASR and text labeling.
Directory
Search results
Published directory entries matching your search.
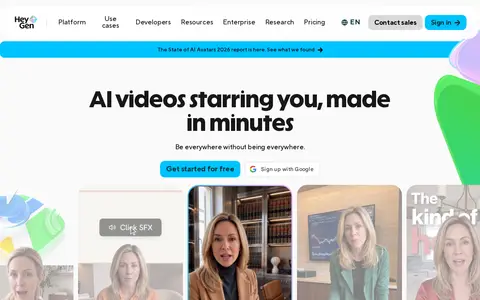
HeyGen is an AI video platform that creates videos with a Personal Avatar using the user's face and voice without filming each video. AI Studio offers a text-based editor for tone, delivery, gestures and emotion, and includes voice cloning and voice mirroring. It also offers the Seedance 2.0 video model from ByteDance for turning text or images into multi-shot clips.
Hume provides voice AI evaluation infrastructure through its VoiceEQ platform. It turns real-world use cases into targeted evaluation suites and combines automated measurement with human judgment to diagnose failures in voice models and agents. The platform covers TTS, speech-to-speech, ASR, and cascaded systems, and the company reports support for over 50 languages.
Suno is an AI music generator that creates original music from user prompts. It offers a browser-based digital audio workstation for editing and mixing tracks, voice cloning to make any voice sing user-written content, stem separation to split songs into individual components, and remix functionality.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
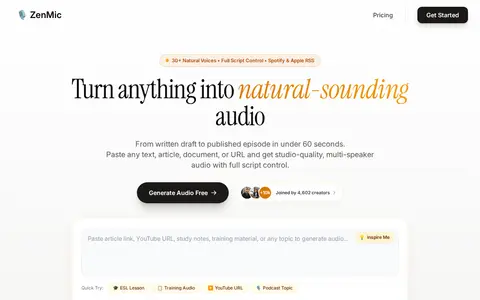
Zenmic.com is an AI audio generation tool that converts text, documents, URLs or topics into natural-sounding audio. It is targeted at ESL teachers, learning and development teams, and podcast creators, and offers features including full script control, over 30 voices, MP3 export, support for 125 languages, up to six speaker tracks, and voice cloning. Users can start using the tool for free without a credit card.
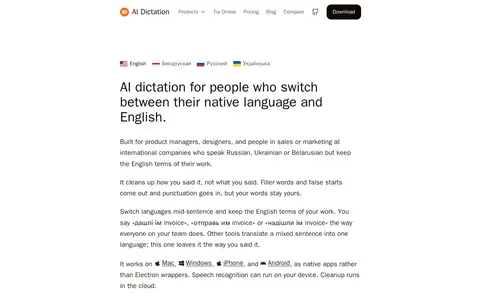
AI Dictation is a voice typing app for people who mix English into Russian, Ukrainian or Belarusian. It removes filler words and adds punctuation without translating work terms. It runs on Mac, Windows, iPhone and Android, and speech recognition can run on device while cleanup runs in the cloud.
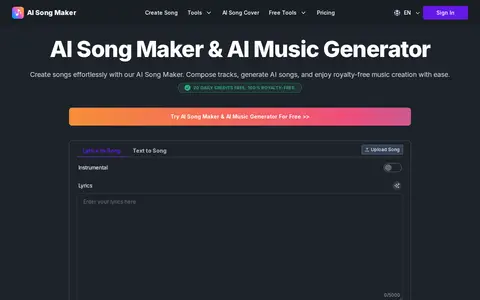
A web tool for generating songs from text, lyrics or uploaded audio, with style, voice and tempo options and instrumental-only tracks. Songs can be downloaded or shared. The free tier offers 20 daily credits and royalty-free output.
You can also find more comprehensive list on and There's an AI AI Voice Cloning list.
Works with speech, voice, music or other audio using machine-learning models.
Architecture of voice AI, from speech recognition to emotional intelligence, and learn how to build, scale, and evaluate them.
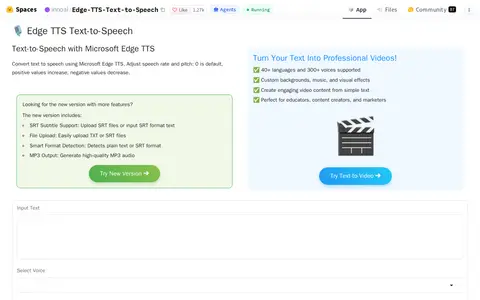
Edge TTS Text To Speech is a Hugging Face Space developed by innoai that converts user-input text to speech. Users can select from dozens of voice options, adjust speech speed and pitch, and generate high-quality MP3 audio files for playback or download. The space is currently running.
Img To Music uses AI for speech, voice, transcription, music, or other audio workflows.
High-quality text-to-speech and voice recognition.
A Hugging Face Space that converts text into speech in various languages, including Lojban and English. Users enter text and choose language and voice settings, then receive audio output. The Space is listed as sleeping due to inactivity.
Works with speech, voice, music or other audio using machine-learning models.
APIs for messaging, voice, and phone verification.
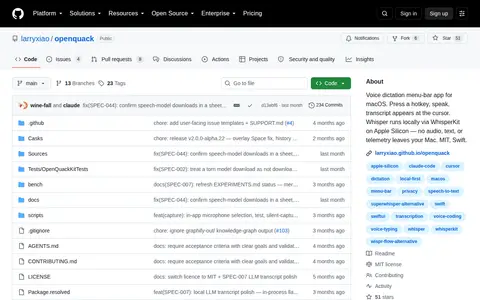
OpenQuack is a menu-bar voice dictation app for macOS. Pressing a hotkey and speaking places the transcript at the cursor. Speech recognition runs locally via WhisperKit on Apple Silicon, with no cloud, account, or signup by default. The project is written in Swift and released under the MIT license.
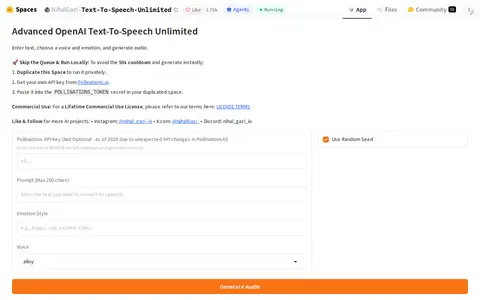
A Hugging Face Space that generates speech from entered text. Users choose a voice and an emotion style and can optionally set a seed. The app sends requests to the Pollinations service and returns an MP3 file with the synthesized speech.
Replica Studios uses AI for speech, voice, transcription, music, or other audio workflows.
Works with speech, voice, music or other audio using machine-learning models.
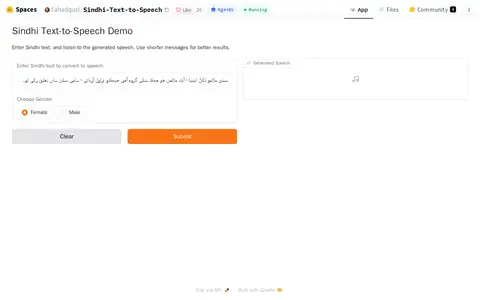
Sindhi TTS is a Hugging Face Space that generates speech from Sindhi text. Users input text and select a gender for the synthesized voice. The system works best with shorter messages.
Works with speech, voice, music or other audio using machine-learning models.