Directory

Search results

Published directory entries matching your search.

Search results

162 listings
github.com

The visualizer is a tool developed by the cheminformatics department of the Swiss Federal Institute of Technology for rendering complex datasets. Its modules, placed on a browser page, display information as tables, charts, matrices or lists and interact through a central API of variables and actions. Visualization starts by passing three JSON file URLs in the browser address bar. It is released under the MIT license.
AI Data & Analytics 0
github.com

Facets is a project containing two visualizations, Facets Overview and Facets Dive, for understanding and analyzing machine learning datasets. The visualizations are Polymer web components backed by TypeScript that can be embedded in Jupyter notebooks or webpages. Overview produces feature-by-feature statistical analysis and compares statistics across datasets. The repository was archived on Jul 27, 2024 and is now read-only.

Models & Machine Learning 0
github.com

CKAN is an open-source data management system for creating and operating data hubs and portals. It enables organizations to publish, share, and use data. It powers government data sites such as data.gov, open.canada.ca, and humdata.org.

AI Data & Analytics 0
github.com

Pachyderm is a project for data-centric pipelines and data versioning. It provides parallelized processing of multi-stage, language-agnostic pipelines with data versioning and data lineage tracking, and pipelines trigger automatically when data changes. It runs on Kubernetes and uses standard object stores for storage.
AI Data & Analytics 0

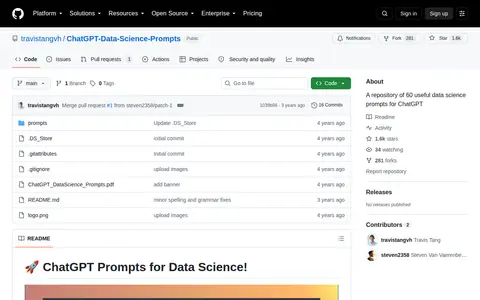
ChatGPT Prompts for Data Science is a GitHub repository containing 60 useful prompts for data science tasks. It includes prompts for writing Python code, automatic machine learning, and other data science workflows.
AI Data & Analytics 0
github.com

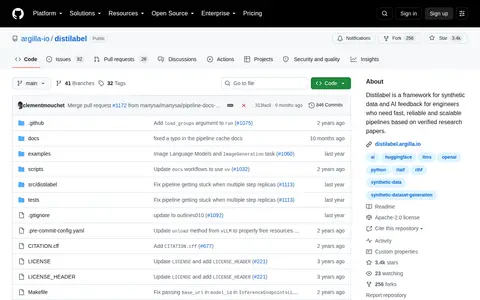
distilabel is a framework for synthetic data generation and AI feedback intended for engineers. It provides fast, reliable, and scalable pipelines based on verified research papers, supporting data synthesis for AI systems and on-the-fly feedback addition. The framework aims to improve AI output quality via enhanced data quality, give users control over their data and models, and boost efficiency through rapid iteration on research and large language models.

AI Data & Analytics 0
github.com

ArtiVC is a command-line tool for data versioning on cloud storage. It snapshots data and switches between versions, supporting commit history, commit messages, version tags, diffing commits, and pulling data from a specific version. Backends include local filesystem, remote filesystem over SSH, AWS S3, Google Cloud Storage, and Azure Blob Storage, with more through Rclone. No additional server is required.

AI Data & Analytics 0
github.com

ReadStat.jl, listed as Data Read, is an open-source Julia library for reading data files in Stata, SAS, and SPSS formats. The project is hosted on GitHub under the queryverse organization, where users can access source code and contribute to its development.

AI Data & Analytics 0

A public GitHub template repository for data science lifecycle projects. It provides a default directory structure including folders for code, data, docs, environments, notebooks, pipelines and tests, plus issue templates and a .github labels file. The source describes it as a launch-off point with minimal opinions. One manual step is creating labels from the labels file.

AI Data & Analytics 0
github.com

Desbordante is a high-performance open-source data profiler. It uses a variety of algorithms to discover different patterns in data and supports running data cleaning scenarios using these algorithms. The tool is available as a console version and an easy-to-use web application.

AI Data & Analytics 0

The oneAPI Data Analytics Library (oneDAL) is a library for data analytics. It is hosted on GitHub under the uxlfoundation/oneDAL repository. The repository provides usage examples, installation instructions, and documentation.

AI Data & Analytics 0
github.com

A federated, open-source data catalog for all your big data and small data.

AI Data & Analytics 0
github.com

Quilt is a scientific data management platform hosted on Amazon Web Services (AWS) that helps teams and AI systems locate, verify the trustworthiness of, and reuse data via deeply versioned, context-rich data packages.

AI Data & Analytics 0

The Data Science Lifecycle Process is a repeatable, sustainable process for guiding data science teams from initial idea to delivered value. The process is fully documented in the public GitHub repository dslp/dslp.

AI Data & Analytics 0
github.com

DataDeps.jl is a Julia package designed to facilitate reproducible data setup for scientific research. It manages data dependencies and includes features such as progress callbacks. The repository is maintained on GitHub.

AI Data & Analytics 0
github.com

DataFrames.jl is a Julia library that provides in-memory tabular data structures for data manipulation and analysis. It is developed by the JuliaData organization and its source code is hosted on GitHub.

AI Data & Analytics 0
github.com

Deepnote is a drop-in replacement for Jupyter with an AI-first design. It uses the Deepnote kernel, adds block types, native data integrations and an AI agent, and supports Python, R and SQL locally in an IDE before scaling to Deepnote Cloud for collaboration and deployable data apps.

AI Data & Analytics 0
github.com

Data Version Control - Git for Data & Models - ML Experiments Management.

AI Data & Analytics 0
github.com

Gopherdata's tooling directory is a curated list of tools, packages, and libraries for doing data science with Go. It organizes resources across categories such as classification, clustering, CSV handling, distributed data analysis, geospatial work, machine learning, and plotting, and also lists proposed packages meant to fill gaps in the ecosystem.

AI Data & Analytics 0
github.com

Impala is a distributed C++ query engine for SQL queries over petabytes of data stored in Apache Hadoop clusters. It supports data in HDFS, Apache HBase and Amazon S3, window functions and subqueries, and uses LLVM for on-the-fly code generation. It is Apache-licensed and open source, and the repository is a mirror of Apache Impala.

AI Data & Analytics 0
github.com

lakeFS is a source-available data version control tool that turns object storage into a Git-like repository, allowing data lakes to be managed like code. It supports AWS S3, Azure Blob Storage and Google Cloud Storage, is API compatible with S3, and works with frameworks such as Spark, Hive, AWS Athena, DuckDB and Presto.

AI Data & Analytics 0
github.com

Onyx is a distributed, masterless data processing system written in pure Clojure, with a batch and stream hybrid processing model. The repository is archived and read-only. Listed uses include realtime event stream processing, extract, transform, load, and data cleaning.

AI Data & Analytics 0
github.com

PipeRider is a tool described as code review for data in dbt. It compares data to highlight differences in impacted downstream dbt models, profiles dbt models, and generates a static HTML report each run. The project states that PipeRider has been superseded by Recce and will no longer be updated on a regular basis.

AI Data & Analytics 0
github.com

PyCM is a multi-class confusion matrix library written in Python. It supports input data vectors and direct matrices and offers post-classification model evaluation statistics. It is aimed at data scientists needing metrics for predictive models and classifiers. A MATLAB setup is also documented.

AI Data & Analytics 0