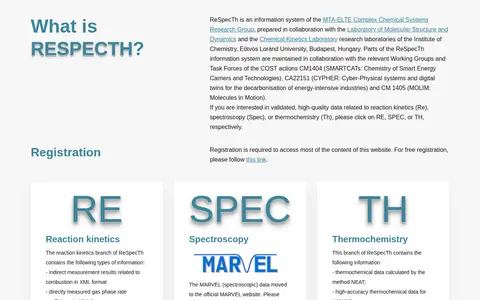
ReSpecTh is an information system of the MTA-ELTE Complex Chemical Systems Research Group at Eötvös Loránd University, Budapest. It covers reaction kinetics, spectroscopy and thermochemistry, holding indirect combustion measurements, gas phase rate coefficients, combustion mechanisms and analysis codes. Registration is required to access most content; the spectroscopy data moved to the MARVEL website.
Directory
Search results
Published directory entries matching your search.
RIKEN Bioresource Research Center is a leading life science research infrastructure center. It preserves and distributes bioresources including mouse strains, plant cell lines, DNA materials, microbial strains, and fluorescent proteins, and provides search tools, big data analysis, and information services to support scientific research.
The Saccharomyces Genome Database (SGD) is a resource providing integrated biological information for the budding yeast Saccharomyces cerevisiae. It offers search and analysis tools for exploring these data, supporting the discovery of functional relationships between sequence and gene products in fungi and higher organisms. Gene pages include literature, interaction, protein and regulation information.
Analyzes structured data and helps produce queries, insights or visualizations.
Browse indexed datasets and documentation for research and secondary analysis.
Skale is a distributed data processing and machine learning engine that provides a high-level API in JavaScript and a parallel execution engine on top of Node.js. The repository was archived by its owner on May 29, 2021 and is read-only. It supports multiple data sources and formats, and can run in local or distributed mode.
Snorkel is a system for quickly generating training data with weak supervision, released under an Apache-2.0 license and written in Python. The project started at Stanford in 2015 to programmatically label, build, and manage training data. The team now focuses on Snorkel Flow, an end-to-end AI application development platform based on the core ideas behind Snorkel.
SoyBase is a collaborative community resource that integrates genetic, genomic, and trait data across legume species to support crop improvement. It provides analysis, search, sequence, visualization, and genome browsing tools for soybean breeders and researchers. The site is funded by USDA-ARS and developed with the National Center for Genome Resources.
An open source tool for running arbitrary queries against public data from the Stack Exchange network.
The Analytics Engineering Roundup is a Substack newsletter curating articles on analytics engineering and its adjacent ecosystem, curated by Tristan Handy. He describes analytics engineering as creating and disseminating knowledge within organizations, covering cloud data platforms, dimensional modeling and data quality.
TheCellVision hosts projects presenting single-cell and image-based analyses of yeast, including endocytic compartment morphology, protein localization and abundance analysis, and cell cycle omics. Each project has its own Help section with methodological procedures and a data dictionary. Unless stated otherwise, projects are based on their own unique image sets.
Tonic is a tool for downloading, manipulating and loading event-based or spike-based data, described as similar to PyTorch Vision but for neuromorphic data. It provides event datasets and transformations, and the project states it is looking for a new maintainer.
Upgini is an open-source data search and enrichment library for Machine Learning and AI pipelines. It enables users to find and add relevant features from hundreds of public and premium external data sources, including open and commercial large language models.
Handbook and recipes for data-driven solutions of real-world problems.
Open CC-BY-4.0 dataset of evidence-graded dietary-supplement data covering dosing, bioavailability, drug-nutrient interactions and cost-per-effective-dose, with every clinical claim tied to a PubMed PMID. Compiled by Verified Supplement Data, it is mirrored on Hugging Face and Kaggle and offered as a free live JSON API.
VirHostNet is a bioinformatic information system for biocuration, data integration, analysis and visualisation of virus/host protein-protein interactions. It offers quick search by protein accession, keyword, taxonomy or PMID, BLAST protein sequence search, browsing by viral taxonomy and keyword annotations, and an Interology web service. The knowledgebase is shared in PSI MITAB 2.5 format via the PSICQUIC web service and distributed through NDEx.
The Baseline Surface Radiation Network (BSRN) has provided high-accuracy surface radiation measurements across a global station network since 1992. Its central archive, the World Radiation Monitoring Center, stores radiation measurements with collocated meteorological observations and station metadata. BSRN is a project of the GEWEX Data and Analysis Panel aimed at detecting changes in Earth's surface radiation budget possibly related to climate change.
AI Models Catalog is a structured YAML catalog of AI model providers and their models, sourced from first-party APIs and official documentation. It includes TypeScript type definitions and Zod runtime validation schemas, plus scripts to sync data from providers and validate YAML files against schemas.
AICaller.io is a robocaller that makes automated outbound phone calls using AI for sales and marketing. It supports lead qualification, meeting booking, appointment booking and data gathering, offers a choice of voices, and connects to over 6,000 applications via Zapier. It can be used through a web portal or APIs.
Aito.ai is a predictive database that delivers instant, calibrated predictions from a user's live data through single queries. It supports use cases including predictive accounting, ERP, e-commerce, and application functionality, with capabilities for predictions, recommendations, classification, smart search, knowledge graphs, and AI agents. It offers a free tier for development and production licensing scaled to usage.
Analyzes structured data and helps produce queries, insights or visualizations.
Apache Atlas – Data Governance and Metadata framework for Hadoop.
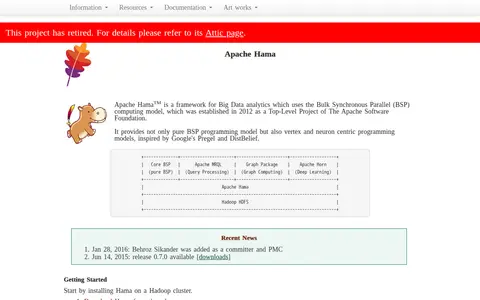
Apache Hama is a retired Apache Software Foundation Top-Level Project established in 2012. It is a framework for Big Data analytics that uses the Bulk Synchronous Parallel (BSP) computing model. It also provides vertex-centric and neuron-centric programming models inspired by Google's Pregel and DistBelief. Its components include core BSP, Apache MRQL for query processing, a graph computing package, and Apache Horn for deep learning, and it integrates with Hadoop HDFS.