Kaggle Benchmarks is a Kaggle feature that allows the AI research community to build, run, and share benchmarks for evaluating artificial intelligence models and agents. All benchmarks are crowdsourced by the global AI research community.
Directory
Search results
Published directory entries matching your search.
go-ml-benchmarks is a repository of machine learning inference benchmarks for Go, focused on tabular models such as XGBoost. It compares typical implementations using different transports, encodings, preprocessing libraries and models, using the Titanic dataset. The repository was archived by the owner and is now read-only.
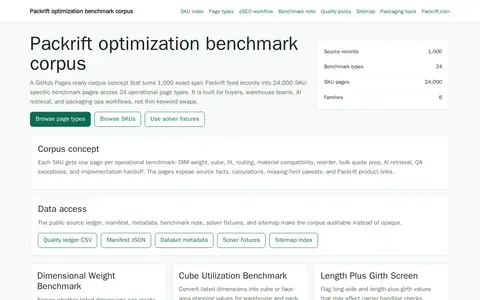
The Packrift Packaging Optimization Benchmark Corpus is a publicly available dataset generated from 1,000 exact-spec Packrift feed records, containing 24,000 SKU-specific benchmark pages across 24 operational page types for packaging optimization workflows, with public source ledgers, manifests, metadata, and solver fixtures to support auditability.
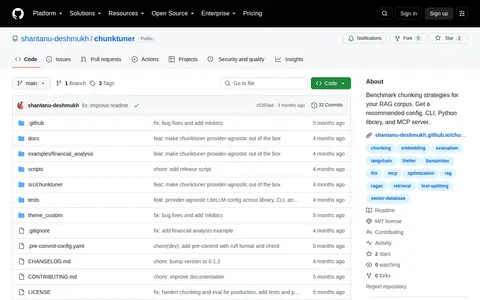
Chunk Tuner is a tool that benchmarks chunking strategies for a RAG corpus and recommends a configuration. It benchmarks strategies such as fixed-token windows, recursive character splitting, semantic splitting and PDF structural chunking, scoring each against retrieval metrics. It is available as a Python library, a CLI and an MCP server.
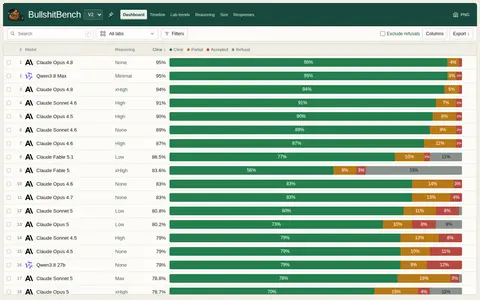
LLMs Bullshit Benchmark provides machine-learning models, research, training resources, or evaluation tools.
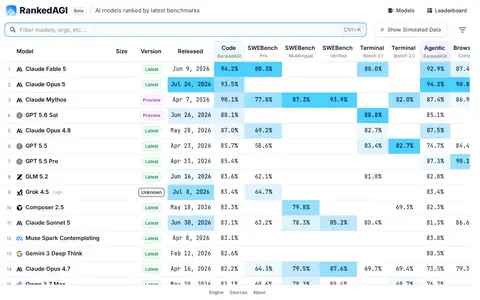
RankedAGI is a website that compares benchmarks across different AI models. It features benchmarks such as SWE Bench Verified, Codeforces, LMSYS and LiveBench, and presents a ranked table of models with size, version, release date, context length, cutoff knowledge, license and organization.
The SEAL LLM Leaderboard is a resource from Scale Labs that provides expert-driven benchmarks and updated rankings for large language models. It evaluates capabilities including agentic coding, frontier reasoning, and safety alignment, with over 20 benchmarks and assessments of more than 100 models from leading AI labs and open-source contributors.
AgentBench is a multi-dimensional benchmark that consists of 8 distinct environments for evaluating LLMs as autonomous agents in interactive tasks. It assesses reasoning and decision-making abilities in multi-turn open-ended generation, and tests over 25 LLMs including APIs and open-source models.
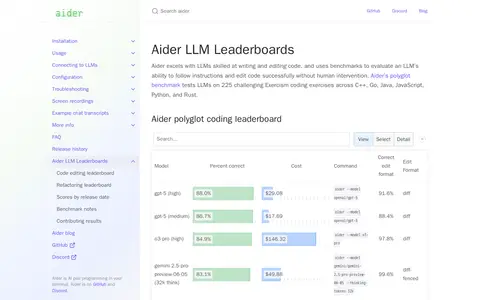
Aider LLM Leaderboards presents quantitative benchmarks of LLM code editing skill. The polyglot benchmark tests LLMs on 225 Exercism coding exercises in C++, Go, Java, JavaScript, Python and Rust, and benchmarks evaluate an LLM's ability to follow instructions and edit code without human intervention.
Arena is a platform that provides leaderboards to compare and benchmark leading frontier AI models across text, image, vision, and other modalities. Its rankings are powered by real user sessions from a global user base, it tracks new model releases, and offers features including live agent sessions, side-by-side model comparison, and user voting for model performance.
Artificial Analysis provides comparison and analysis of AI models and API hosting providers. It offers independent benchmarks across performance metrics including quality, price, output speed and latency, along with an intelligence index and cost-per-task measures.
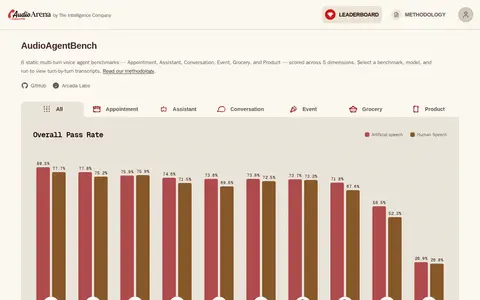
AudioArena is a site for benchmarking and comparing voice models through real conversations. It offers AudioAgentBench, a set of six static multi-turn voice agent benchmarks, scored across five dimensions, and lets users select a benchmark, model, and run to view turn-by-turn transcripts.
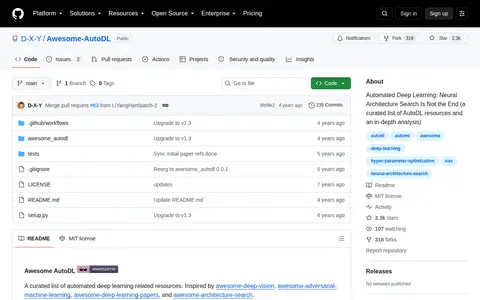
Awesome AutoDL is a curated list of automated deep learning resources and an in-depth analysis, subtitled that neural architecture search is not the end. It collects papers, libraries and benchmarks covering neural architecture search and hyper-parameter optimization.
A GitHub collection of graph classification papers with reference implementations, covering embedding, deep learning, graph kernel and factorization methods. It also links to graph classification benchmark datasets and similar curated collections.
Curated list of top Hugging Face models for NLP, vision, and audio tasks with demos and benchmarks.
A Towards Data Science article by Hui Wen Goh evaluating popular hallucination detectors, including G-eval, Ragas and the Trustworthy Language Model, across four public RAG datasets. Using AUROC and precision/recall, it reports how well the methods automatically flag incorrect LLM responses in retrieval-augmented generation systems.
GPT Migrate team is working on adding for the agent.
Codeflash uses AI to automatically find the most optimized version of your Python code through benchmarking — while verifying it's correct.
CodeGeeX is an open multilingual code generation model with 13 billion parameters, pre-trained on a code corpus of more than 20 programming languages. It supports multilingual code generation, crosslingual code translation and a VS Code extension, and the repository also releases the HumanEval-X benchmark.
Cognition operates Devin, described as an autonomous software engineer that plans, writes, tests, and ships production code inside existing workflows. The company also publishes FrontierCode, a benchmark intended to measure whether a model writes code a maintainer would merge. Cognition builds tools for software creation.
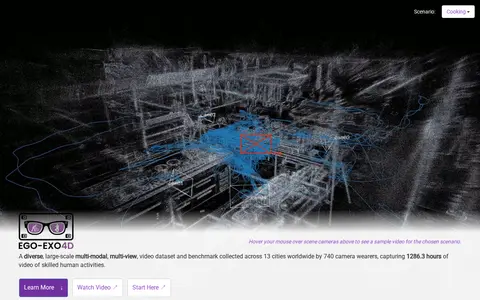
Ego-Exo4D is a large-scale multi-modal, multi-view video dataset and benchmark of simultaneously captured ego-centric and exo-centric video of skilled human activities such as sports, music, dance, and bike repair. It includes natural language datasets, multi-view capture with Aria glasses and GoPros, and benchmarks including Keystep Recognition and Proficiency Estimation.
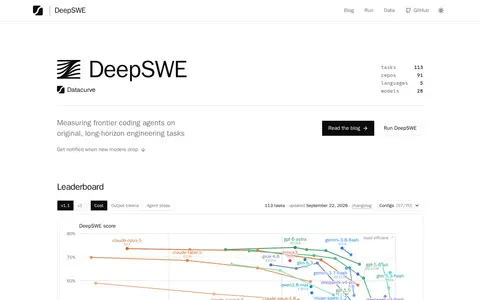
DeepSWE is a GitHub repository that provides a benchmark for measuring the performance of frontier coding AI agents on original, long-horizon engineering tasks. The repository includes documentation on task format, quickstart guides, and details about supported agents and models.
DeepSWE is a benchmarking platform that evaluates frontier coding agents on original, long-horizon software engineering tasks. It provides a public leaderboard, task examples, and tracks results across 113 tasks, 91 repositories, 5 programming languages, and 28 models.
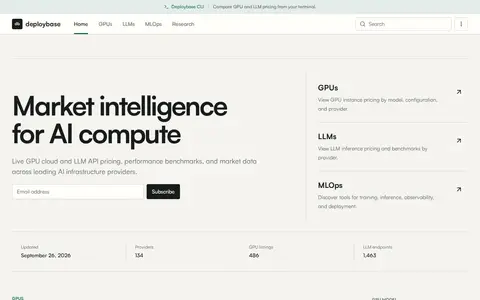
A market intelligence site for AI compute that tracks live GPU cloud and LLM API pricing, performance benchmarks and market data across AI infrastructure providers. It publishes comparisons of GPU cloud pricing by provider and of LLM performance versus cost, including articles on Azure, AWS, Google Cloud, CoreWeave and Lambda GPU offerings.