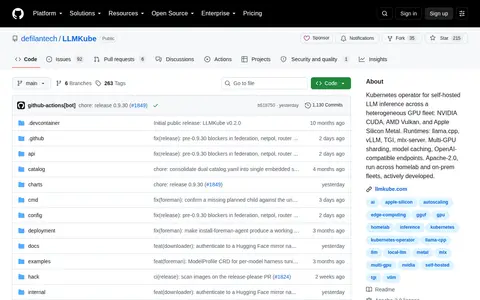
LLMKube is a Kubernetes operator for self-hosted large language model inference across heterogeneous GPU fleets supporting NVIDIA CUDA, AMD Vulkan, and Apple Silicon Metal. It supports runtimes including llama.cpp, vLLM, TGI, and mlx-server, offers multi-GPU sharding, model caching, and OpenAI-compatible endpoints. It is licensed under Apache-2.0 and designed for homelab and on-prem fleet deployment, and is actively developed.
Directory
Search results
Published directory entries matching your search.
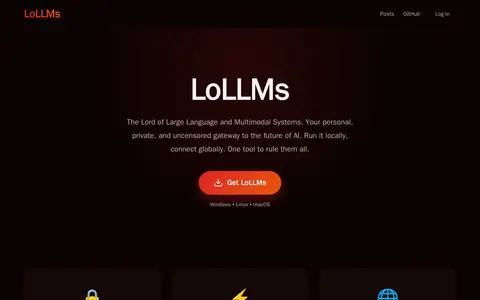
LoLLMs, described as the Lord of Large Language and Multimodal Systems, is a local AI tool for running models. It states full local execution and hardware support for NVIDIA, AMD, Apple Silicon or CPU. It is offered for Windows, Linux and macOS.
MLPNeuralNet is a multilayer perceptron neural network library for iOS and Mac OS X. It predicts new examples through trained neural networks and is built on Apple's Accelerate Framework using vectored operations and hardware acceleration where available. It is designed to load and run models in forward propagation mode only, and supports classification, multi-class classification, and regression output.
SD.Next is an open-source web interface for generating and editing images and video with diffusion models. It supports text-to-image, image-to-image, text-to-video and image-to-video workflows, and also offers captioning, tagging, upscaling, interpolation and colorization. It runs on NVIDIA, AMD, Intel, Apple Silicon or CPU setups, and includes a queue for scheduling tasks.