RedPajama-Data-v2 is a 30 trillion token open dataset from 84 CommonCrawl dumps across five languages, with over 40 precomputed quality annotations. Data processing scripts are open source on GitHub and all data are available on HuggingFace. The dataset is intended for further filtering and weighting of data, and the release notes describe it as an open dataset for training large language models.
Directory
Search results
Published directory entries matching your search.
MeTA is a modern C++ data sciences toolkit. It provides text tokenization including deep semantic features like parse trees, inverted and forward indexes with compression and caching strategies, ranking functions for searching indexes, topic models, classification algorithms, graph algorithms, language models, a CRF implementation for POS-tagging and shallow parsing, and wrappers for liblinear and libsvm.
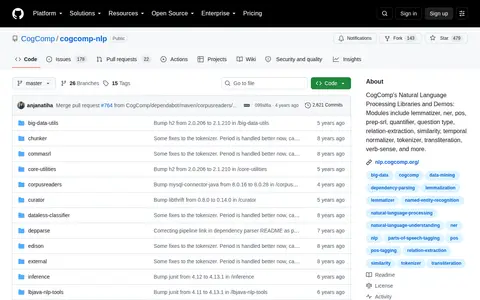
CogCompNLP is a collection of core natural language processing libraries developed by the Cognitive Computation Group. Its modules include a lemmatizer, part-of-speech tagger, named entity recognizer, tokenizer, transliterator, relation extraction, similarity, temporal normalizer and verb sense tools. The project includes a pipeline for annotating raw text and recommends JDK8.
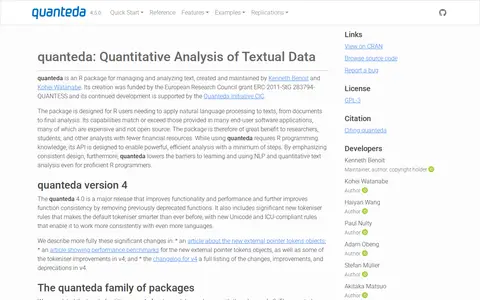
quanteda is an R package for managing and analyzing text, described as a fast, flexible, and comprehensive framework for quantitative text analysis in R. It provides functionality for corpus management, tokens and n-grams, keywords in context, sparse matrices, content dictionaries, and supervised and unsupervised machine learning.
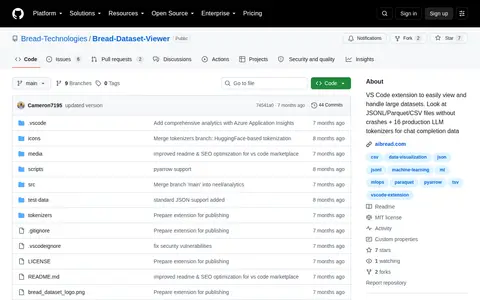
Bread Dataset Viewer is a VS Code extension for viewing and handling large datasets. It opens JSONL, Parquet, CSV, TSV, JSON, and Arrow/Feather files by streaming and lazy-loading data, and provides Cards, Table, and Raw views. It includes 16 production LLM tokenizers from GPT, Claude, Llama, and Qwen for chat completion data.
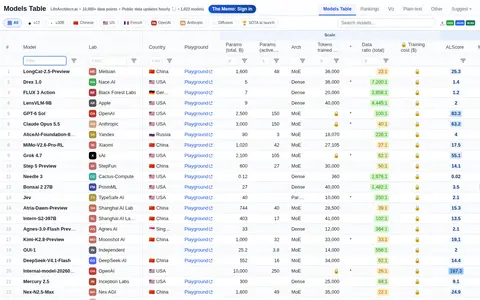
LifeArchitect.ai hosts a Models Table of large language model data, including parameters, tokens trained, and benchmark scores such as MMLU, MMLU-Pro, GPQA and HLE. The page also presents rankings, a data dictionary and visualization snapshots of frontier models.
A free LLM course from Hugging Face that teaches large language models and natural language processing. It covers the Transformers, Datasets, Tokenizers, and Accelerate libraries and the Hugging Face Hub, along with some libraries outside the ecosystem. The course is without ads.
Compromise is a JavaScript natural-language processing library that turns text into data, offering tokenization of words, sentences and punctuation along with part-of-speech tagging, matching, and transformations such as verb conjugation and number handling. It runs on the client side, is about 250kb minified, and includes plugins, with multilingual support listed for French, German, Italian and Spanish.
Phenaki is a Google Research model that synthesizes realistic videos from textual prompt sequences. It uses an encoder-decoder tokenizer for variable-length videos and a transformer that translates text embeddings to video tokens, trained jointly on image-text and video-text data.
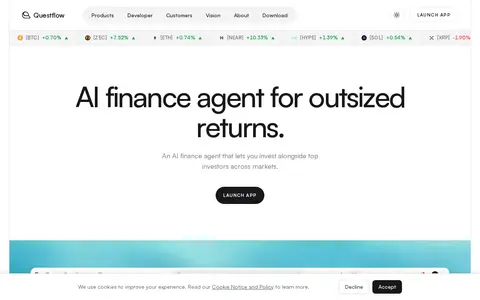
Questflow is described as an AI finance agent that lets users invest alongside top investors across markets. It supports selection among models such as GPT, Claude and Gemini, skills defining investment strategy, plugins for financial data, and accounts that connect exchanges, brokerages, wallets and tokens for analyzing positions and executing trades.
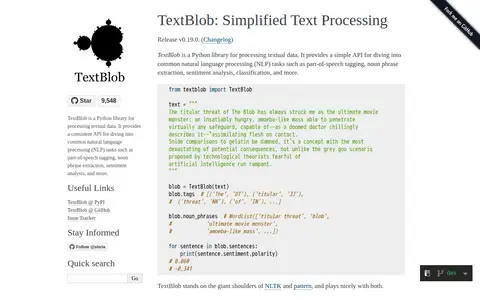
TextBlob is a Python library for processing textual data. It offers a simple API for natural language processing tasks including part-of-speech tagging, noun phrase extraction, sentiment analysis, classification, and tokenization. The documentation lists features such as word and phrase frequencies, parsing n-grams, lemmatization, spelling correction, and WordNet integration. It builds on NLTK and pattern, and new models or languages can be added through extensions.