Directory

Search results

Published directory entries matching your search.

Search results

61 listings
hama.apache.org

Apache Hama is a retired Apache Software Foundation Top-Level Project established in 2012. It is a framework for Big Data analytics that uses the Bulk Synchronous Parallel (BSP) computing model. It also provides vertex-centric and neuron-centric programming models inspired by Google's Pregel and DistBelief. Its components include core BSP, Apache MRQL for query processing, a graph computing package, and Apache Horn for deep learning, and it integrates with Hadoop HDFS.
AI Data & Analytics 0
ctakes.apache.org

Apache cTAKES is an open-source project developed under the Apache Software Foundation. Its documentation and project resources are hosted on a GitHub repository, and it is part of the broader Apache developer and user community.

Models & Machine Learning 0
github.com

Impala is a distributed C++ query engine for SQL queries over petabytes of data stored in Apache Hadoop clusters. It supports data in HDFS, Apache HBase and Amazon S3, window functions and subqueries, and uses LLVM for on-the-fly code generation. It is Apache-licensed and open source, and the repository is a mirror of Apache Impala.

AI Data & Analytics 0
github.com

A genomics processing engine and specialized file format built using Apache Avro, Apache Spark and Parquet. Apache 2 licensed.

AI Education & Learning 0
zeppelin.apache.org

Apache Zeppelin is a web-based notebook for data-driven, interactive data analytics and collaborative documents with SQL, Scala, Python, R and more. It uses interpreters to plug in language and data-processing backends, including built-in Apache Spark integration, and includes basic charts, pivot charts, dynamic forms and paragraph publishing to embed results in websites.

AI Data & Analytics 0
github.com

Koalas, from Databricks, implements the pandas DataFrame API on top of Apache Spark. The repository is marked deprecated and in maintenance mode; Koalas supports Apache Spark 3.1 and below, and PySpark is recommended directly for Spark 3.2 and above. It is available under the Apache-2.0 license.

AI Data & Analytics 0
atlas.apache.org

Apache Atlas – Data Governance and Metadata framework for Hadoop.

AI Data & Analytics 0
github.com

Apache MXNet is a deep learning framework mixing symbolic and imperative programming. It includes a dynamic dependency scheduler that parallelizes symbolic and imperative operations, with a graph optimization layer for symbolic execution. The repository was archived on Nov 17, 2023, and is read-only.

Models & Machine Learning 0
open-metadata.org

OpenMetadata is an open-source AI context layer powered by metadata, semantics, and memory that provides a shared, rich understanding of data for people and AI. It was built by the founders of Apache Hadoop, Apache Atlas, and Uber Databook. The unified platform supports data cataloging, discovery, quality, observability, governance, lineage, and collaboration.

AI Data & Analytics 0
github.com

Oryx 2 is a realization of the lambda architecture built on Apache Spark and Apache Kafka, specialized for real-time large scale machine learning. It is a framework for building applications and includes packaged end-to-end applications for collaborative filtering, classification, regression and clustering. The repository was archived by the owner on May 3, 2022, and is read-only.

Models & Machine Learning 0
singa.apache.org

Apache SINGA is an Apache Top Level Project focused on distributed training of deep learning and machine learning models. It supports data parallel training across multiple GPUs on a single node or across different nodes, automatic gradient calculation, and loading and saving ONNX format models. Models trained with SINGA can be queried as stored procedures in an RDBMS.
Models & Machine Learning 0
github.com

E2B is an AI agent cloud that gives each agent session an isolated Linux machine booting from a snapshot and working with any model or agent framework. Its GitHub organization hosts the stack under Apache-2.0, including the Firecracker runtime, control plane, in-VM agent, SDKs, and dashboard.
AI Coding & Development 0
airflow.apache.org

Apache Airflow is a platform created by the community to programmatically author, schedule and monitor workflows. Pipelines are defined in Python, and workflows can be monitored, scheduled and managed through a web application. Operators allow tasks to run on services such as Google Cloud Platform, Amazon Web Services and Microsoft Azure.

AI Agents & Automation 0
github.com

Platform to programmatically author, schedule, and monitor workflows.

AI Agents & Automation 0
github.com

Bernstein is an open-source, Apache-2.0 licensed AI Agents Governance and Orchestration framework. Users can write governance rules declaratively, and Bernstein enforces these rules while producing verifiable, replayable records of agent activity. The project is associated with the website bernstein.run.

AI Agents & Automation 0
bodywork.readthedocs.io

Bodywork is a command line tool that deploys machine learning pipelines to Kubernetes, handling containers and orchestration. Any pipeline stage runs either a batch job or a long-running process. It is presented as a lightweight alternative to Kubeflow or building a platform around workflow tools such as Apache Airflow, Argo Workflows or Dagster. Stages are defined as Python modules or Jupyter notebooks and configured in a single bodywork.yaml file.

Models & Machine Learning 0
trychroma.com

Chroma is open-source search infrastructure for AI under Apache 2.0. It supports vector, full-text, regex and metadata search, built on object storage. Chroma Cloud offers serverless, scalable deployment with usage-based pricing.

AI Search & Research 0
github.com

ClearTK is a framework for developing statistical natural language processing components in Java, built on top of Apache UIMA. It is developed by the Center for Computational Language and Education Research (CLEAR) at the University of Colorado at Boulder. The project is built with Maven, and the repository includes sub-projects such as cleartk-feature and modules for several machine learning libraries.

AI Image Generation 0
github.com

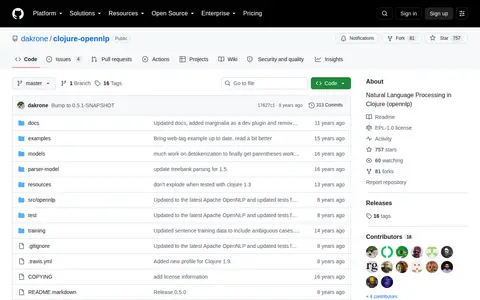
Clojure-openNLP is an open-source Clojure library that provides an interface to the Apache OpenNLP natural language processing toolkit. Hosted as a public GitHub repository, it includes usage instructions for the Leiningen build tool and sample usage from a Clojure REPL.

Models & Machine Learning 0
square.github.io

Cube is a system for collecting timestamped events and deriving metrics, built on MongoDB and released under the Apache License on GitHub. It accepts events via UDP, HTTP POST, and WebSockets, defines a query language for retrieving events, and groups events by time to compute aggregate metrics.

AI Data & Analytics 0
github.com

DALL·E Mini is a project for generating images from a text prompt. The repository provides installation for inference and development, a training script, and links to trained models on the Hugging Face Model Hub. The model can be used on Craiyon, and community projects include DALL-E Playground and DALL·E Flow. It is released under the Apache-2.0 license.

AI Image Generation 0
github.com

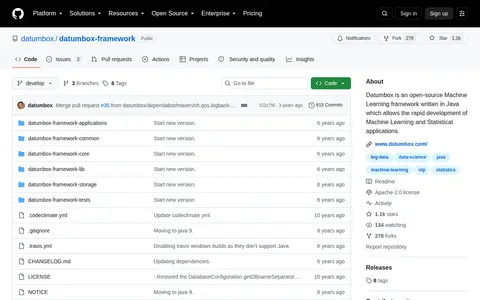
Datumbox is an open-source machine learning framework written in Java for rapid development of machine learning and statistical applications. It focuses on including many machine learning algorithms and statistical methods and on handling large datasets. The code is licensed under the Apache License, Version 2.0, and releases are available on Maven Central, including version 0.8.2.

Models & Machine Learning 0
playground.tensorflow.org

A Neural Network Playground is a browser-based educational visualization created by Daniel Smilkov and Shan Carter for experimenting with a real neural network. Users adjust controls to explore how a network learns from data. The project is open sourced on GitHub under the Apache License so its features can be tailored to a topic or lesson.

Models & Machine Learning 0