huggingface.co
Discover amazing ML apps made by the community.
Directory
Published directory entries matching your search.
Discover amazing ML apps made by the community.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Personalized soundscapes to help you focus, relax, and sleep. Backed by neuroscience.
Fast inference engine for whisper in C++ using CTranslate2.
結婚式スピーチ・弔辞・年賀状・退職挨拶・お礼状・お詫び文など、冠婚葬祭と日常の手紙・挨拶文をAIが作成します。シチュエーションを選んで項目を埋めるだけで、そのまま使える文面が完成。82種類のツールを登録不要・完全無料で今すぐ使えます。.
Speech recognition toolkit with streaming ASR, VAD, punctuation, speaker diarization, and OpenAI-compatible serving for voice AI applications.
Port of OpenAI's Whisper model in C/C++. It can be executed locally.
We are a community-driven organization releasing open-source generative audio tools to make music production more accessible and fun for everyone.
Distribution, publishing, funding, marketing, and a hands-on team for independent artists. We.
High-quality text-to-speech and voice recognition.
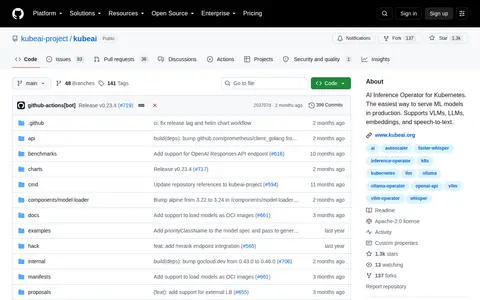
Deploy and scale machine learning models on Kubernetes. Built for LLMs, embeddings, and speech-to-text.
Works with speech, voice, music or other audio using machine-learning models.
Tts for Lojban using VITS TTS models.
Implementation of MusicLM, Google's new SOTA model for music generation using attention networks, in Pytorch.
"transforming the future of music creation".
A simple notebook demonstrating prompt-based music generation via Mubert API.
Works with speech, voice, music or other audio using machine-learning models.
An AI-powered voiceover tool that provides realistic voices for videos, podcasts, and presentations.
Discover amazing ML apps made by the community.
An open-source framework by NVIDIA for building speech AI systems, including automatic speech recognition and text-to-speech. opensource.
APIs for messaging, voice, and phone verification.
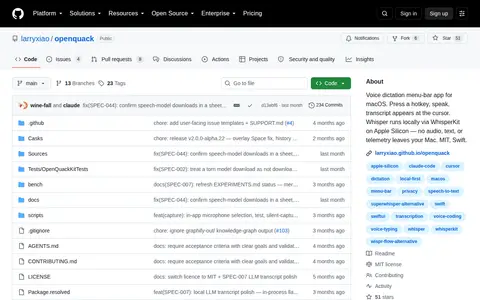
On-device voice dictation for macOS — transcribes a 5-minute clip in 2.8 s; noise-robust, paste at cursor. 99 languages, ~8 MB, no telemetry. MIT.
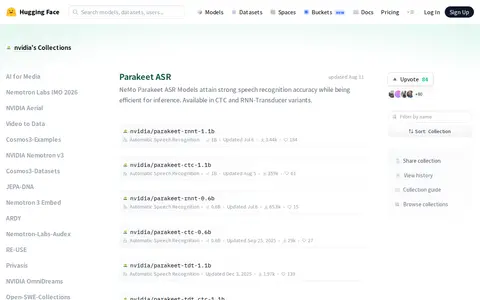
NeMo Parakeet ASR Models attain strong speech recognition accuracy while being efficient for inference. Available in CTC and RNN-Transducer variants.