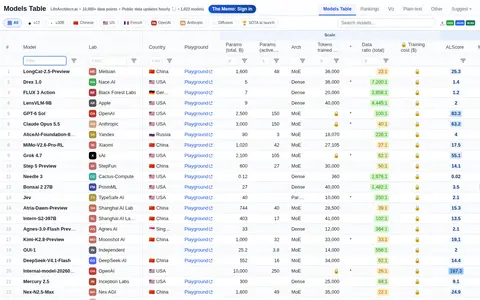
LifeArchitect.ai hosts a Models Table of large language model data, including parameters, tokens trained, and benchmark scores such as MMLU, MMLU-Pro, GPQA and HLE. The page also presents rankings, a data dictionary and visualization snapshots of frontier models.
Tensor Trust
Tensor Trust is a prompt injection attack and defense game that invites users to fool AI language models and climb a leaderboard. The site is part of a research project studying prompt injection vulnerabilities in AI systems, using crowdsourced submissions to help researchers build more reliable AI.
Screenshot unavailable. The listing stays available while a preview is prepared.
Features
- prompt injection attack/defense game Source: tensortrust.ai
Links
Tags
-
0LifeArchitect.ai hosts a Models Table of large language model data, including parameters, tokens trained, and benchmark scores such as MMLU, MMLU-Pro, GPQA and HLE. The page also presents rankings, a data dictionary and visualization snapshots of frontier models.
-
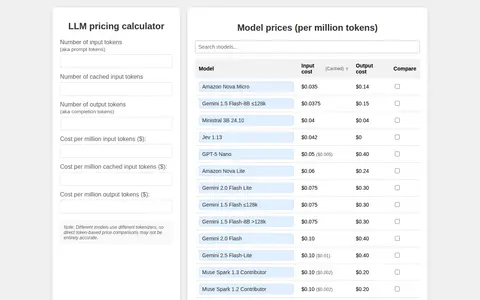
0LLM pricing calculator is a web page for estimating model costs per million tokens. It takes input, cached input and output token counts and reports cost per million input tokens, per million cached input tokens and per million output tokens. It notes that direct token-based price comparisons may not be entirely accurate because different models use different tokenizers.
-
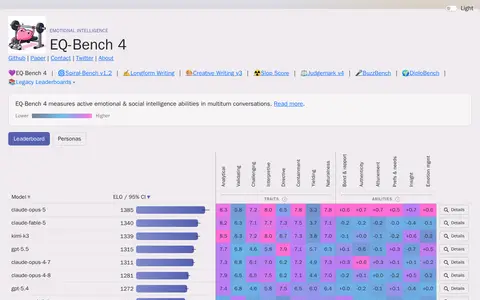
0EQ-Bench 4 is a benchmark that measures active emotional and social intelligence abilities in multiturn conversations. It uses 120 personas with assigned traits, including adversarial ones, in roleplay chats played by Gemini 3.1 Pro Preview. Transcripts are assessed by three judges to produce a ranked Elo score.
-
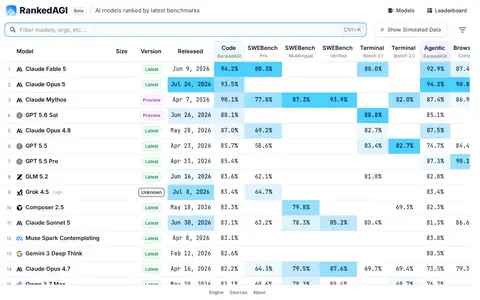
0RankedAGI is a website that compares benchmarks across different AI models. It features benchmarks such as SWE Bench Verified, Codeforces, LMSYS and LiveBench, and presents a ranked table of models with size, version, release date, context length, cutoff knowledge, license and organization.
-
0AI Weekly is an AI news publication that ranks and explains the day's most important artificial intelligence stories. It tracks AI models, agents, funding, policy and research, with updates throughout the day, and also publishes a regular numbered issue and live alerts.
-
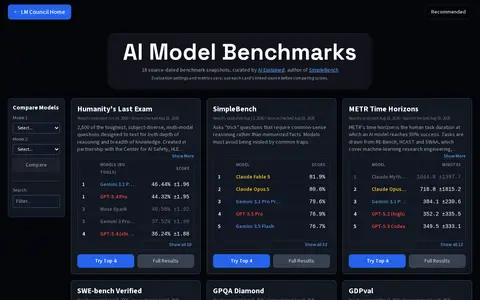
0LM Council presents source-dated benchmark snapshots for AI models. It covers GPT, Claude, Gemini and other frontier models across benchmarks including Humanity's Last Exam, FrontierMath, GPQA and SWE-bench, with a comparison tool selecting two models. Each snapshot links its source and checked date, and evaluation settings and metrics vary.
Community notes
Reviews and discussion
No reviews yet
Be the first to share how this project worked for you.
Join the discussion
Sign in with a verified account to leave a review or join the discussion.
Sign in to review