Word-As-Image for Semantic Typography is a research method that automatically creates word-as-image illustrations, visualizing a word's meaning while preserving readability. It optimizes letter outlines guided by a pretrained Stable Diffusion model and handles a large variety of semantic concepts and any font.
sdg-link
sdg-link creates or edits images with generative AI and text-based controls.
Links
Tags
-
0
Word-As-Image for Semantic Typography is a research method that automatically creates word-as-image illustrations, visualizing a word's meaning while preserving readability. It optimizes letter outlines guided by a pretrained Stable Diffusion model and handles a large variety of semantic concepts and any font.
-
0Playground is an AI design tool for creating logos, stickers, merch, posters, social media graphics and other designs without experience. It provides templates across 24 categories and uses image models including GPT Image 2, Nano Banana Pro and Seedream. Paid plans add faster generation, credits, upscaling, background removal and commercial use licensing.
-
0Launch your AI product 100x faster with StartKit.
-
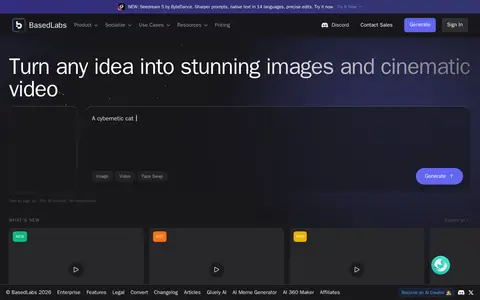
0BasedLabs is a web-based platform for generating AI images, videos, and face swaps with over 50 AI models. It also offers free online video editing tools, including a YouTube video editor and a TikTok video generator. The service is free to sign up for and requires no software installation.
-
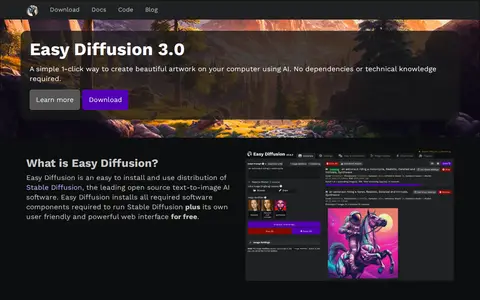
0Easy Diffusion is an easy to install distribution of Stable Diffusion, the open source text-to-image AI software. It installs the required software components and provides its own web interface for free. Users run a simple installer, then create images from text prompts or use images to direct the AI. An active community is available on Discord.
-
0
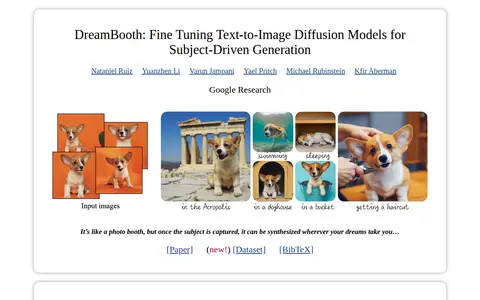
DreamBooth is a method for personalizing text-to-image diffusion models. Given a few images of a subject and its class name, it fine-tunes a pretrained model so a unique identifier refers to that subject, allowing synthesis of the subject in new scenes, poses, views and lighting, with tasks including subject recontextualization and text-guided view synthesis.
Community notes
Reviews and discussion
No reviews yet
Be the first to share how this project worked for you.
Join the discussion
Sign in with a verified account to leave a review or join the discussion.
Sign in to review