Nixified packages AI executable code as self-contained Nix packages, including dependencies, and builds each project from source. Users can install and run the code with a single nix command on Linux distributions and on Windows through WSL. The project lists textgen and InvokeAI as packaged projects and offers GPU support for NVIDIA and AMD.
Rate Display
Rate Display is an AI tool or resource for chat, research, automation, media generation, or model development.
Screenshot unavailable. The listing stays available while a preview is prepared.
Links
Tags
-
0Nixified packages AI executable code as self-contained Nix packages, including dependencies, and builds each project from source. Users can install and run the code with a single nix command on Linux distributions and on Windows through WSL. The project lists textgen and InvokeAI as packaged projects and offers GPU support for NVIDIA and AMD.
-
0LoLLMs, described as the Lord of Large Language and Multimodal Systems, is a local AI tool for running models. It states full local execution and hardware support for NVIDIA, AMD, Apple Silicon or CPU. It is offered for Windows, Linux and macOS.
-
0AI Assistant is a chat interface that offers conversation with more than 30 AI models at no cost. The listed models include Ministral, Mixtral, Mistral, Pixtral, Codestral, Llama, DeepSeek, GLM, Qwen, GPT OSS, Phi, Kimi and Minimax variants. The page also refers to generating images.
-
0Arena.ai is an X account describing itself as a place where AI meets the real world. It states that it measures and advances the frontier of AI through community-driven evaluation.
-
0Juno is an AI researcher that designs studies, interviews real people, and works through the evidence to report findings. It offers REST, MCP and A2A API access with self-service API keys scoped to one organisation. Pricing is $45 USD per completed interview, with study design free and no seats or subscription; recruitment and incentives are not included.
-
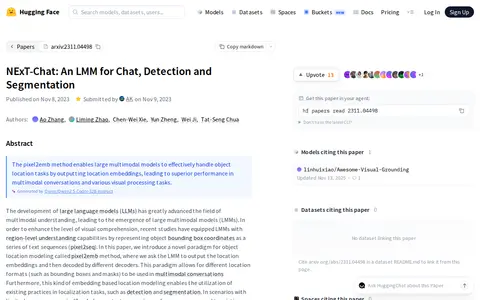
0NExT-Chat is a large multimodal model trained using the pixel2emb method, in which the model outputs location embeddings decoded by different decoders. This allows bounding boxes and masks in multimodal conversations and supports tasks such as visual grounding, region caption and grounded reasoning.
Community notes
Reviews and discussion
No reviews yet
Be the first to share how this project worked for you.
Join the discussion
Sign in with a verified account to leave a review or join the discussion.
Sign in to review