MEKA is an open source implementation of methods for multi-label learning and evaluation, based on the WEKA Machine Learning Toolkit. It includes dozens of multi-label methods from the scientific literature and a wrapper to the MULAN framework. The project is distributed via SourceForge, with code hosted on GitHub.
QuestDB
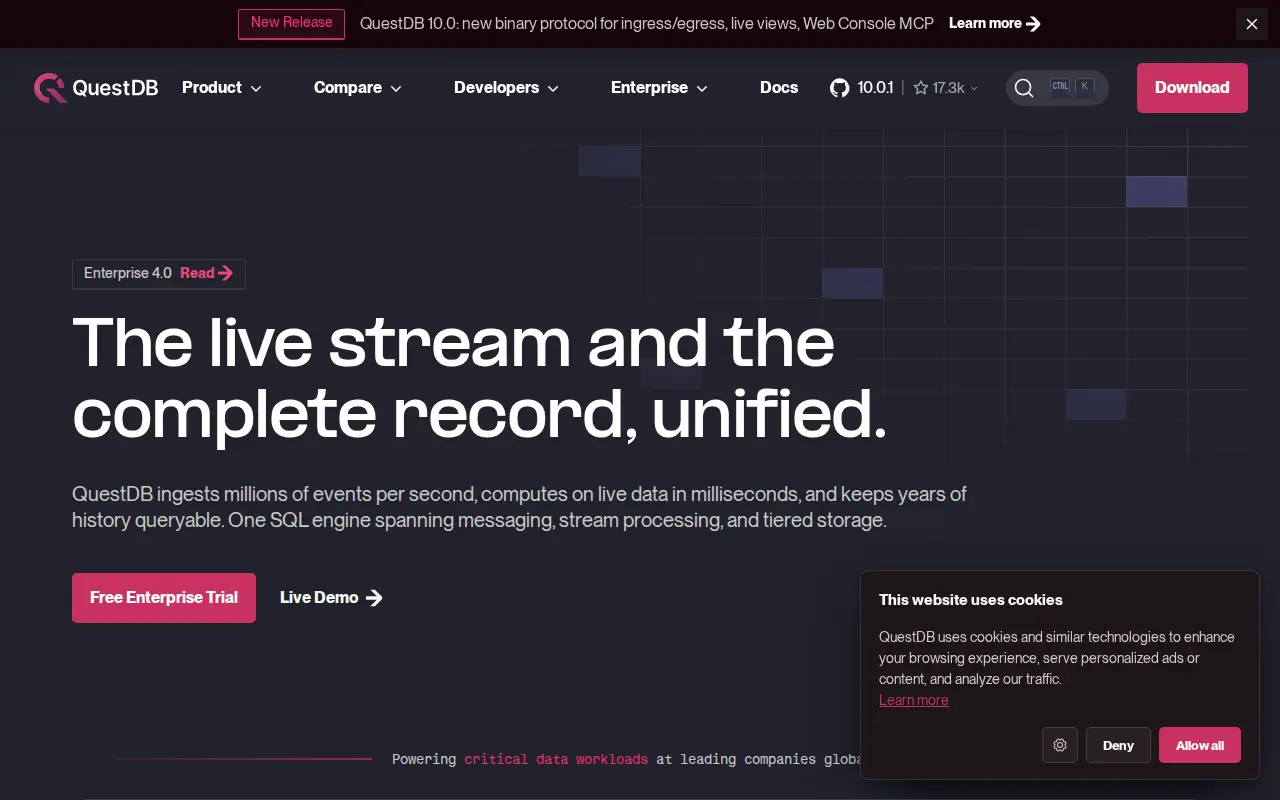
QuestDB is an open-source time-series database engineered for low latency. It uses a column-oriented, time-partitioned storage engine with memory-mapped files and vectorized execution for high-throughput ingestion and millisecond-level analytical queries. SQL is extended with time-series operators such as SAMPLE BY, LATEST ON, ASOF JOIN, WINDOW JOIN and HORIZON JOIN.
Features
- open source time-series database engineered for low latency Source: questdb.com
Links
Tags
-
0
MEKA is an open source implementation of methods for multi-label learning and evaluation, based on the WEKA Machine Learning Toolkit. It includes dozens of multi-label methods from the scientific literature and a wrapper to the MULAN framework. The project is distributed via SourceForge, with code hosted on GitHub.
-
0Privatiser anonymizes IPs, API keys, passwords, PII and cloud identifiers before text is pasted into AI tools. It runs in the browser with local processing, preserves structure, and offers a reversible mapping to restore values in replies. It is free and open source.
-
0This resource offers a downloadable, printable poster outlining 15 common data fallacies as part of data literacy lessons, with a monthly random giveaway for free mailed copies of the poster.
-
0
tweetopic is a Python library for topic modelling of Tweets and other short texts. Its documentation site provides an API reference and a usage guide covering installation, the Dirichlet Multinomial Mixture Model, the Biterm Topic Model, pipelines, visualization and model persistence.
-
0
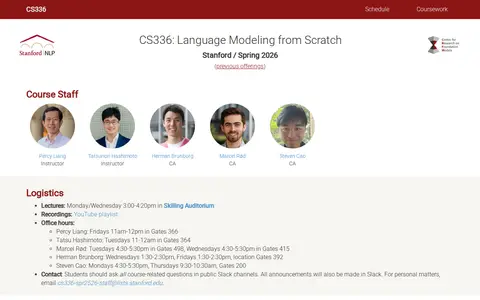
Stanford CS336: Language Modeling from Scratch is the official course website for a Stanford class offered in Spring 2026. The course walks students through the process of developing a language model, including data collection and cleaning for pre-training, transformer model construction, model training, and evaluation before deployment. The site provides logistics, schedule, assignments, and course materials.
-
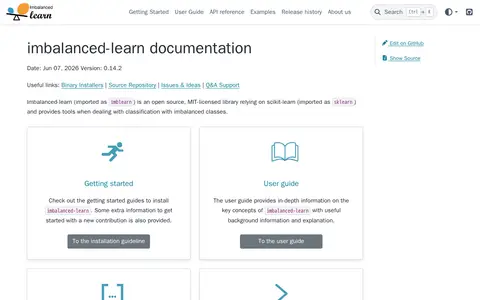
0An open source, MIT-licensed Python library imported as imblearn that relies on scikit-learn. It provides tools for classification with imbalanced classes. The documentation includes installation guides, a user guide, an API reference and a gallery of examples.
Community notes
Reviews and discussion
No reviews yet
Be the first to share how this project worked for you.
Join the discussion
Sign in with a verified account to leave a review or join the discussion.
Sign in to review