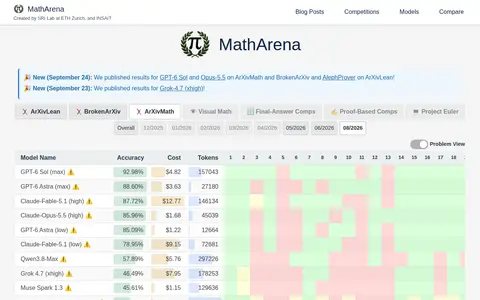
MathArena evaluates large language models on uncontaminated math benchmarks. It presents model analysis across competitions such as ArXivLean, BrokenArXiv, ArXivMath, Visual Math, Final-Answer Comps, Proof-Based Comps and Project Euler. A competition is selected to load tables and a leaderboard, and clicking a cell shows the raw model output.
Prompt Engineering Guide
A guide to prompt engineering that collects papers, advanced prompting techniques, learning guides, model-specific guides, lectures, references, new LLM capabilities, and tools related to prompt engineering. It describes prompt engineering as a discipline for developing and optimizing prompts to use language models across applications and research topics, and offers courses on prompting and building AI agents.
Features
- contains all the latest papers, advanced prompting techniques, learning guides Source: www.promptingguide.ai
Uses
- efficiently use language models (LMs) for a wide variety of applications and research topics Source: www.promptingguide.ai
Links
Tags
-
0MathArena evaluates large language models on uncontaminated math benchmarks. It presents model analysis across competitions such as ArXivLean, BrokenArXiv, ArXivMath, Visual Math, Final-Answer Comps, Proof-Based Comps and Project Euler. A competition is selected to load tables and a leaderboard, and clicking a cell shows the raw model output.
-
0It's Better With AI is a human-curated directory of AI tools organized by categories such as coding, image generation, writing and summarization. The site lists tools with brief descriptions and starting prices, and offers a weekly newsletter for new AI tools and updates. It includes a submission page and a contact page for a human.
-
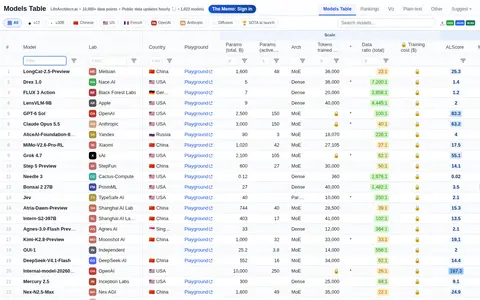
0LifeArchitect.ai hosts a Models Table of large language model data, including parameters, tokens trained, and benchmark scores such as MMLU, MMLU-Pro, GPQA and HLE. The page also presents rankings, a data dictionary and visualization snapshots of frontier models.
-
0LLM pricing calculator is a web page for estimating model costs per million tokens. It takes input, cached input and output token counts and reports cost per million input tokens, per million cached input tokens and per million output tokens. It notes that direct token-based price comparisons may not be entirely accurate because different models use different tokenizers.
-
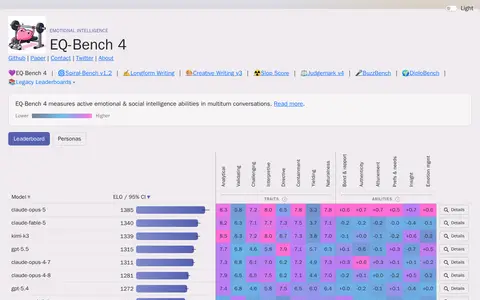
0EQ-Bench 4 is a benchmark that measures active emotional and social intelligence abilities in multiturn conversations. It uses 120 personas with assigned traits, including adversarial ones, in roleplay chats played by Gemini 3.1 Pro Preview. Transcripts are assessed by three judges to produce a ranked Elo score.
-
0AI Weekly is an AI news publication that ranks and explains the day's most important artificial intelligence stories. It tracks AI models, agents, funding, policy and research, with updates throughout the day, and also publishes a regular numbered issue and live alerts.
Community notes
Reviews and discussion
No reviews yet
Be the first to share how this project worked for you.
Join the discussion
Sign in with a verified account to leave a review or join the discussion.
Sign in to review