github.com
Web Archives is an open source project for saving, replaying, or working with archived web pages.
Directory
Explore Web Archives resources in Reference & Knowledge.
Web Archives is an open source project for saving, replaying, or working with archived web pages.
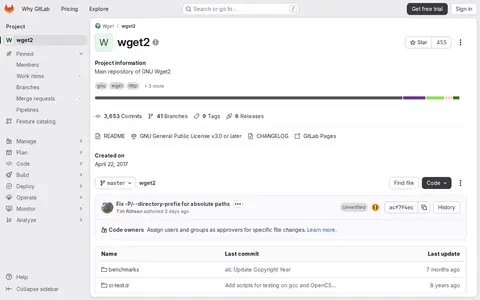
Wget2 is an open source project with code, documentation, and setup resources for web archiving and scraping.
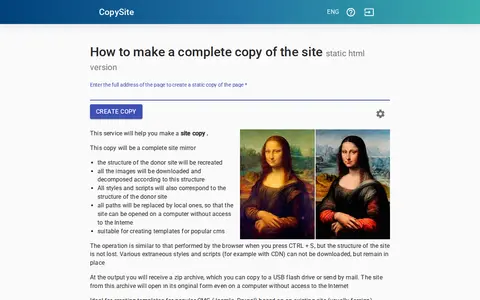
CopySite helps crawl, scrape, copy, or extract data and pages from websites.
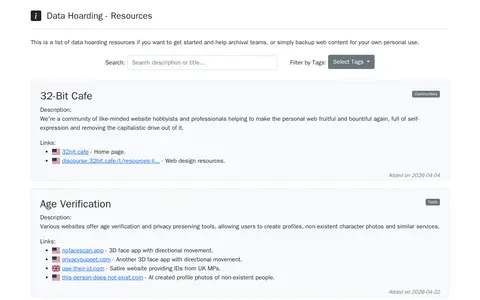
Data Hoarding is an index of resources and archives related to data hoarding, web archival and digital preservation. It provides a list of resources for getting started, helping archival teams, or backing up web content for personal use, with entries like Archive Team, ArchiveBox, Archivematica and ArchivesSpace.
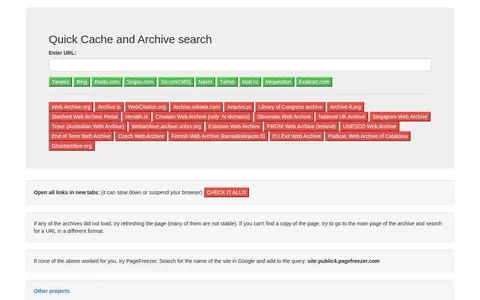
A reference page of links for searching cached copies and web archives. It advises opening all links in new tabs, noting this can slow down or suspend the browser, and suggests refreshing if archives fail to load. It also recommends searching for the site name with a site:public4.pagefreezer.com query or trying PageFreezer when no copy is found.
Vandal is a browser extension that serves as a navigator for the Web Archive, helping users move back in time without leaving the current tab. It is built on the Wayback Machine API and offers calendar and graph views, a built-in browser for archived snapshots, navigation history, a resource drawer and a beta historical view. Limitations include iframe restrictions on some websites and no support for saving pages.
Wiki DL Guide is a web archiving or scraping tool for saving pages, data, or online content.
ArchiveTeam helps save, browse, replay, or preserve web pages and online resources.
Wget Wizard is a web form that helps users build Wget command lines through a user interface covering popular options. It does not download files itself; it suggests a command to run with Wget on a computer or server. The page notes advanced options are omitted.
Week in OSINT is a weekly collection of OSINT news published on Sector035's site, typically appearing every Monday at 8:00 AM CEST. Each installment lists articles, tools, podcasts and other resources on topics such as privacy, maps, bookmarks, domains and geolocation.
Internet Archive Book Ripper is a beta userscript that downloads the pages of a borrowed Internet Archive book as a ZIP of .jp2 images from which a complete PDF can be generated. It requires Violentmonkey and supports only Chromium-based browsers so far, excluding Ungoogled Chromium. A button appears in the book reader once a book has been borrowed and pages indexed.
Zim Reader helps save, browse, replay, or preserve web pages and online resources.
WAIL (Web Archiving Integration Layer) is a desktop application that provides a graphical user interface atop multiple pre-configured web archiving tools, intended as an easy way to preserve and replay web pages. It includes Heritrix 3.7.0 for web crawling and OpenWayback 2.4.0 for replaying web archives, is written in Python and compiled with PyInstaller, and is licensed under MIT.
A Firefox add-on that redirects pages opened from Twitter and other feeds to their archived versions in the Wayback Machine. Pages not yet archived are saved automatically. Sites on an updatable excludes list are not redirected.
Awesome Web Archiving is a code repository or project page with source code, releases, documentation, or setup notes.
Offline reader for Wikipedia, educational content, and ZIM archives without an internet connection.
datahoarder-website-to-markdown is an open source project with code, documentation, and setup resources for web archiving and scraping.
DownloadNet (dn) is an open source project with code, documentation, and setup resources for web archiving and scraping.
Httrack is an open source project with code, documentation, and setup resources for web archiving and scraping.
MarkSnip is an open source project with code, documentation, and setup resources for web archiving and scraping.
Resurrect Pages Fork is an open source project with code, documentation, and setup resources for web archiving and scraping.
Scoop is an open source project with code, documentation, and setup resources for web archiving and scraping.
SuckIT is an open source project with code, documentation, and setup resources for web archiving and scraping.
Archive.org-Downloader is a storage, design, or frontend resource for mockups, assets, UI tools, or web search.