rts.ch
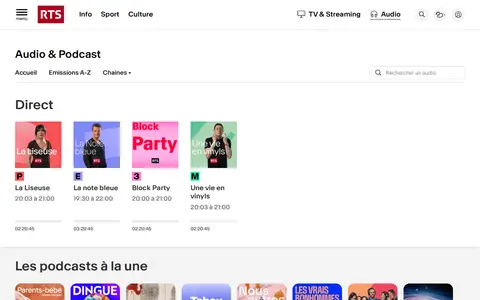
RTS Podcasts provides online music, radio stations, podcasts, audiobooks, or other audio programmes.
Directory
Published directory entries matching your search.
RTS Podcasts provides online music, radio stations, podcasts, audiobooks, or other audio programmes.
SaturnMusic is a GitHub repository or organization with source code, releases, documentation, or project resources.
Telegram link is a Telegram channel, group, or bot link for updates, files, community posts, or support.
ScrobbleRadio helps discover, play, organize, or follow radio, podcasts, audiobooks, and audio feeds.
Find digitized publications and collection items through an online library.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Reddit link points to a Reddit community or thread with discussion, updates, troubleshooting, or shared resources.
AI-driven sound and music generation.
SoundofText uses AI for speech, voice, transcription, music, or other audio workflows.
SOUNDRAW uses AI for speech, voice, transcription, music, or other audio workflows.
A charitable trust and online collection of New Zealand music resources.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Speechma uses AI for speech, voice, transcription, music, or other audio workflows.
Splitter uses AI for speech, voice, transcription, music, or other audio workflows.
Telegram link is a Telegram channel, group, or bot link for updates, files, community posts, or support.
Stable Audio uses AI for speech, voice, transcription, music, or other audio workflows.
Suno uses AI for speech, voice, transcription, music, or other audio workflows.
Telegram link is a Telegram channel, group, or bot link for updates, files, community posts, or support.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.