emu-video.metademolab.com
](https://emu-video.metademolab.com/demo /demo): state-of-the-art text-to-video generation.
Directory
Published directory entries matching your search.
](https://emu-video.metademolab.com/demo /demo): state-of-the-art text-to-video generation.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
Chatterbox uses AI for speech, voice, transcription, music, or other audio workflows.
AI Jukebox supports machine learning models, deployment, inspection, datasets, or AI development workflows.
MusicFX uses AI for speech, voice, transcription, music, or other audio workflows.
SoundofText uses AI for speech, voice, transcription, music, or other audio workflows.
Acapella Extractor uses AI for speech, voice, transcription, music, or other audio workflows.
NaturalReader online reader converts text into spoken audio for listening and accessibility.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
USE BAZEL VERSION=5.0.0./bazelisk-linux-amd64 build wavegru mod -c opt --copt=-march=native.
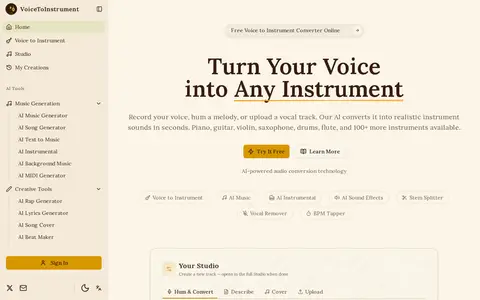
Turn your voice into any instrument with AI. Upload vocals and convert to piano, guitar, violin, sax and 100+ instruments. Free online tool.
VoiceSphere AI: Streamline document handling for PDFs, DOCs, PPTs, videos, texts. Fast, precise answers. #VoiceSphereAI #AIChat #DocumentManagement.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.