github.com
Works with speech, voice, music or other audio using machine-learning models.
Directory
Published directory entries matching your search.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Professional AI voice generator for real production workflows, with free testing and flexible integration for studios and media teams.
Rev AI, part of the Rev family, is a developer-first API that delivers industry- accuracy and fast performance at global scale. Click to learn more.
Works with speech, voice, music or other audio using machine-learning models.
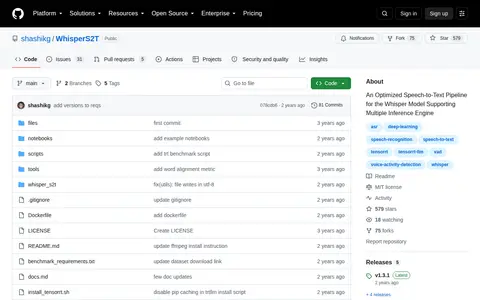
An Optimized Speech-to-Text Pipeline for the Whisper Model.
Turn any idea into scroll-stopping Shorts, Reels, and TikToks with AI visuals, studio voiceovers and synced captions.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
This premium domain name is available for purchase!
AI-driven sound and music generation.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Speechify reads anything aloud to you. Listen to books, PDFs, or web pages anytime with natural voices. Try Speechify free.
Examples for ICASSP2024 paper “StemGen: A music generation model that listens”.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
NaturalReader online reader converts text into spoken audio for listening and accessibility.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.
Works with speech, voice, music or other audio using machine-learning models.